@@ -18,63 +18,42 @@
It streamlines development, training, and inference, and is compatible with any hardware, open-source tools, and frameworks.
-#### Hardware
+#### Accelerators
-`dstack` supports `NVIDIA`, `AMD`, `Google TPU`, `Intel Gaudi`, and `Tenstorrent` accelerators out of the box.
+`dstack` supports `NVIDIA`, `AMD`, `Google TPU`, and `Tenstorrent` accelerators out of the box.
## Latest news ✨
-- [2025/12] [dstack 0.20.0: Fleet-first UX, Events, and more](https://github.com/dstackai/dstack/releases/tag/0.20.0)
-- [2025/11] [dstack 0.19.38: Routers, SGLang Model Gateway integration](https://github.com/dstackai/dstack/releases/tag/0.19.38)
-- [2025/10] [dstack 0.19.31: Kubernetes, GCP A4 spot](https://github.com/dstackai/dstack/releases/tag/0.19.31)
-- [2025/08] [dstack 0.19.26: Repos](https://github.com/dstackai/dstack/releases/tag/0.19.26)
-- [2025/08] [dstack 0.19.22: Service probes, GPU health-checks, Tenstorrent Galaxy](https://github.com/dstackai/dstack/releases/tag/0.19.22)
-- [2025/07] [dstack 0.19.21: Scheduled tasks](https://github.com/dstackai/dstack/releases/tag/0.19.21)
-- [2025/07] [dstack 0.19.17: Secrets, Files, Rolling deployment](https://github.com/dstackai/dstack/releases/tag/0.19.17)
+- [2026/08] [dstack 0.21.0: Pydantic v2, Gateway replicas](https://github.com/dstackai/dstack/releases/tag/0.21.0)
+- [2026/07] [dstack 0.20.29: Presets — agent-driven inference optimization (experimental)](https://dstack.ai/docs/concepts/presets/)
+- [2026/07] [dstack 0.20.27: Slurm backend](https://github.com/dstackai/dstack/releases/tag/0.20.27)
+- [2026/05] [dstack 0.20.21: Kubernetes multiple clusters](https://github.com/dstackai/dstack/releases/tag/0.20.21)
+- [2026/05] [dstack 0.20.20: NVIDIA Dynamo integration](https://github.com/dstackai/dstack/releases/tag/0.20.20)
+- [2026/04] [dstack 0.20.17: Kubernetes volumes](https://github.com/dstackai/dstack/releases/tag/0.20.17)
+- [2026/02] [dstack 0.20.10: PD disaggregation support](https://github.com/dstackai/dstack/releases/tag/0.20.10)
+- [2026/01] [dstack 0.20.7: Replica groups](https://github.com/dstackai/dstack/releases/tag/0.20.7)
## How does it work?
-
-
+
+
-### Installation
+### Launch the server
-> Before using `dstack` through CLI or API, set up a `dstack` server. If you already have a running `dstack` server, you only need to [set up the CLI](#set-up-the-cli).
+> Before using `dstack` through CLI or API, set up a `dstack` server. If you already have a running `dstack` server, you only need to [install the CLI](#install-the-cli).
-#### Set up the server
-
-##### Configure backends
-
-To orchestrate compute across cloud providers or existing Kubernetes clusters, you need to configure backends.
-
-Backends can be set up in `~/.dstack/server/config.yml` or through the [project settings page](https://dstack.ai/docs/concepts/projects#backends) in the UI.
-
-For more details, see [Backends](https://dstack.ai/docs/concepts/backends).
+To orchestrate compute across GPU clouds or Kubernetes clusters, you need to [configure backends](https://dstack.ai/docs/concepts/backends).
> When using `dstack` with on-prem servers, backend configuration isn’t required. Simply create [SSH fleets](https://dstack.ai/docs/concepts/fleets#ssh-fleets) once the server is up.
-##### Start the server
-
-You can install the server on Linux, macOS, and Windows (via WSL 2). It requires Git and
+The server can be installed on Linux, macOS, and Windows (via WSL 2). It requires Git and
OpenSSH.
-##### uv
-
```shell
$ uv tool install "dstack[all]" -U
-```
-
-##### pip
-
-```shell
-$ pip install "dstack[all]" -U
-```
-
-Once it's installed, go ahead and start the server.
-
-```shell
$ dstack server
+
Applying ~/.dstack/server/config.yml...
The admin token is "bbae0f28-d3dd-4820-bf61-8f4bb40815da"
@@ -84,27 +63,18 @@ The server is running at http://127.0.0.1:3000/
> For more details on server configuration options, see the
[Server deployment](https://dstack.ai/docs/guides/server-deployment) guide.
+### Install the CLI
-Set up the CLI
-
-#### Set up the CLI
+If the CLI is not installed with the server
-Once the server is up, you can access it via the `dstack` CLI.
+Once the server is up, you can access it via the `dstack` CLI.
The CLI can be installed on Linux, macOS, and Windows. It requires Git and OpenSSH.
-##### uv
-
```shell
$ uv tool install dstack -U
```
-##### pip
-
-```shell
-$ pip install dstack -U
-```
-
To point the CLI to the `dstack` server, configure it
with the server address, user token, and project name:
@@ -113,28 +83,38 @@ $ dstack project add \
--name main \
--url http://127.0.0.1:3000 \
--token bbae0f28-d3dd-4820-bf61-8f4bb40815da
-
+
Configuration is updated at ~/.dstack/config.yml
```
+### Install agent skills
+
+Install [`dstack` skills](https://skills.sh/dstackai/dstack/dstack) to help AI agents use the CLI and edit configuration files.
+
+```shell
+$ npx skills add dstackai/dstack
+```
+
+AI agents like Claude, Codex, and Cursor can now create and manage fleets and submit workloads on your behalf.
+
### Define configurations
`dstack` supports the following configurations:
-* [Dev environments](https://dstack.ai/docs/dev-environments) — for interactive development using a desktop IDE
-* [Tasks](https://dstack.ai/docs/tasks) — for scheduling jobs (incl. distributed jobs) or running web apps
-* [Services](https://dstack.ai/docs/services) — for deployment of models and web apps (with auto-scaling and authorization)
-* [Fleets](https://dstack.ai/docs/fleets) — for managing cloud and on-prem clusters
-* [Volumes](https://dstack.ai/docs/concepts/volumes) — for managing persisted volumes
-* [Gateways](https://dstack.ai/docs/concepts/gateways) — for configuring the ingress traffic and public endpoints
+* [Fleets](https://dstack.ai/docs/concepts/fleets) — Provision and manage clusters across clouds, Kubernetes, and on-prem
+* [Dev environments](https://dstack.ai/docs/concepts/dev-environments) — Launch dev environments to be accessed by agents or from your IDE
+* [Tasks](https://dstack.ai/docs/concepts/tasks) — Run training, batch or other jobs across a single node or clusters
+* [Services](https://dstack.ai/docs/concepts/services) — Deploy model inference as secure and scalable endpoints
+* [Presets](https://dstack.ai/docs/concepts/presets) — Agent-driven inference optimization (experimental)
+* [Volumes](https://dstack.ai/docs/concepts/volumes) — Managing instance and network volumes for persisting data
Configuration can be defined as YAML files within your repo.
### Apply configurations
-Apply the configuration either via the `dstack apply` CLI command or through a programmatic API.
+Apply the configuration via the `dstack apply` CLI command, a programmatic API, or through [AI agent skills](#install-ai-agent-skills).
`dstack` automatically manages provisioning, job queuing, auto-scaling, networking, volumes, run failures,
out-of-capacity errors, port-forwarding, and more — across clouds and on-prem clusters.
diff --git a/contributing/AUTOSCALING.md b/contributing/AUTOSCALING.md
index 7fa987aaf9..f977e4d60f 100644
--- a/contributing/AUTOSCALING.md
+++ b/contributing/AUTOSCALING.md
@@ -2,18 +2,21 @@
`dstack` features auto-scaling for services published via the gateway. The general flow is:
-- STEP 1: `dstack-gateway` parses nginx `access.log` to collect per-second statistics about requests to the service and request times.
-- STEP 2: `dstack-gateway` aggregates statistics over a 1-minute window.
-- STEP 3: The dstack server pulls all service statistics in the `process_gateways` background task.
-- STEP 4: The `process_runs` background task passes statistics and current replicas to the autoscaler.
-- STEP 5: The autoscaler (configured via the `dstack.yml` file) returns the replica change as an int.
-- STEP 6: `process_runs` calls `scale_run_replicas` to add or remove replicas.
-- STEP 7: `scale_run_replicas` terminates or starts replicas.
- - `SUBMITTED` and `PROVISIONING` replicas get terminated before `RUNNING`.
- - Replicas are terminated by descending `replica_num` and launched by ascending `replica_num`.
+- STEP 1: The gateway parses nginx `access.log` to collect per-second statistics about requests to the service and request times.
+- STEP 2: The gateway aggregates statistics over several predefined windows.
+- STEP 3: The server keeps gateway connections alive in the scheduled `process_gateways_connections` task and continuously collects stats from active gateways. This is separate from `GatewayPipeline`, which handles gateway provisioning and deletion.
+- STEP 4: When `RunPipeline` processes a service run, it loads the latest collected gateway stats for that service.
+- STEP 5: The autoscaler (configured via `dstack.yml`) computes the desired replica count for each replica group.
+- STEP 6: `RunPipeline` applies that desired state.
+ - For scale-up, it creates new `SUBMITTED` jobs. `JobSubmittedPipeline` then assigns existing capacity or provisions new capacity for them.
+ - For scale-down, it marks the least-important active replicas as `TERMINATING` with `SCALED_DOWN`. `JobTerminatingPipeline` unregisters and cleans them up.
+- STEP 7: If the service is in rolling deployment, `RunPipeline` handles that in the same active-run processing path.
+ - It allows only a limited surge of replacement replicas.
+ - It delays teardown of old replicas until replacement capacity is available.
+ - It also cleans up replicas that belong to replica groups removed from the configuration.
## RPSAutoscaler
-`RPSAutoscaler` implements simple target tracking scaling. The target value represents requests per second per replica (in a 1-minute window).
+`RPSAutoscaler` implements simple target tracking scaling. The target value represents requests per second per replica (in a configurable window).
`scale_up_delay` tells how much time has to pass since the last upscale or downscale event before the next upscaling. `scale_down_delay` tells how much time has to pass since the last upscale or downscale event before the next downscaling.
diff --git a/contributing/BACKENDS.md b/contributing/BACKENDS.md
index f53750791a..90b56a55ab 100644
--- a/contributing/BACKENDS.md
+++ b/contributing/BACKENDS.md
@@ -31,14 +31,23 @@ git clone https://github.com/dstackai/gpuhunt.git
- **Online providers** offer dynamic machine configurations that are available at the very moment
when you fetch configurations (e.g., GPU marketplaces).
`gpuhunt` collects online providers' instance offers each time a `dstack` user provisions a new instance.
- Examples: `tensordock`, `vastai`, etc.
+ Examples: `vastai`, `hotaisle`, etc.
### 1.3. Create the provider class
Create the provider class file under `src/gpuhunt/providers`.
-Make sure your class extends the [`AbstractProvider`](https://github.com/dstackai/gpuhunt/blob/main/src/gpuhunt/providers/__init__.py)
-base class. See its docstrings for descriptions of the methods that your class should implement.
+Make sure your class extends either `OnlineProvider` or `OfflineProvider` from
+[base.py](https://github.com/dstackai/gpuhunt/blob/main/src/gpuhunt/providers/base.py),
+matching the choice you made above.
+
+Both kinds implement `get`, returning `CatalogItem`s with `provider` set to your provider's `NAME`.
+Additionally:
+
+- Online providers implement the `from_env` classmethod, which reads credentials from the
+ environment with `get_creds_env` and raises `MissingCredsError` if one is missing. Providers that
+ raise it are skipped by `default_catalog()` rather than failing the whole catalog.
+- Offline providers may override `filter` to omit some offers from the published catalog.
Refer to examples:
- Offline providers:
@@ -47,8 +56,8 @@ Refer to examples:
[azure.py](https://github.com/dstackai/gpuhunt/blob/main/src/gpuhunt/providers/azure.py),
[lambdalabs.py](https://github.com/dstackai/gpuhunt/blob/main/src/gpuhunt/providers/lambdalabs.py).
- Online providers:
- [vultr.py](https://github.com/dstackai/gpuhunt/blob/main/src/gpuhunt/providers/vultr.py)
- [tensordock.py](https://github.com/dstackai/gpuhunt/blob/main/src/gpuhunt/providers/tensordock.py),
+ [vultr.py](https://github.com/dstackai/gpuhunt/blob/main/src/gpuhunt/providers/vultr.py),
+ [hotaisle.py](https://github.com/dstackai/gpuhunt/blob/main/src/gpuhunt/providers/hotaisle.py),
[vastai.py](https://github.com/dstackai/gpuhunt/blob/main/src/gpuhunt/providers/vastai.py).
### 1.4. Register the provider with the catalog
@@ -57,7 +66,8 @@ Add your provider in the following places:
- Either `OFFLINE_PROVIDERS` or `ONLINE_PROVIDERS` in `src/gpuhunt/_internal/catalog.py`.
- The `python -m gpuhunt` command in `src/gpuhunt/__main__.py`.
- (offline providers) The CI workflow in `.github/workflows/catalogs.yml`.
-- (online providers) The default catalog in `src/gpuhunt/_internal/default.py`.
+- (online providers) `ONLINE_PROVIDER_MODULES` in `src/gpuhunt/_internal/default.py`, which is what
+ `default_catalog()` loads.
### 1.5. Add data quality tests
@@ -160,8 +170,8 @@ If instances in the backend take more than 10 minutes to start, override the def
### 2.10. Document the backend
-Add the backend to the [Concepts->Backends](https://github.com/dstackai/dstack/blob/master/docs/docs/concepts/backends.md
-) page and the [server/comfig.yml](https://github.com/dstackai/dstack/blob/master/docs/docs/reference/server/config.yml.md) reference.
+Add the backend to the [Concepts->Backends](https://github.com/dstackai/dstack/blob/master/mkdocs/docs/concepts/backends.md
+) page and the [server/comfig.yml](https://github.com/dstackai/dstack/blob/master/mkdocs/docs/reference/server/config.yml.md) reference.
## 3. Appendix
@@ -181,8 +191,9 @@ The agent controls the VM and starts Docker containers for users' jobs.
Since `dstack` controls the entire VM, VM-based backends can support more features,
such as blocks, instance volumes, privileged containers, and reusable instances.
-Note, all VM-based backend `Compute`s should sublass the `ComputeWithPrivilegedSupport` mixin,
-as the `dstack-shim` agent provides this functionality OOTB.
+Note, all VM-based backend `Compute`s should sublass the `ComputeWithPrivilegedSupport`
+and `ComputeWithInstanceVolumesSupport` mixins, as the `dstack-shim` agent
+provides these functionalities OOTB.
To support a VM-based backend, `dstack` expects the following:
diff --git a/contributing/DATABASE.md b/contributing/DATABASE.md
new file mode 100644
index 0000000000..f70dffa084
--- /dev/null
+++ b/contributing/DATABASE.md
@@ -0,0 +1,86 @@
+# Database
+
+This document describes the `dstack` server rules of working with the database. Separately covered:
+
+* DB migrations in `MIGRATIONS.md`
+* Resource locking in `LOCKING.md`
+* Pipeline-based background processing in `PIPELINES.md`.
+
+## Connections
+
+DB connections are a scarce resource. For example, a minimal RDS Postgres instance comes with ~80 connections. Increasing the number of connections requires
+scaling the DB instance and is expensive. This section describes how the `dstack` server should use DB connections to avoid running out of them.
+
+### Connection budget
+
+The server creates one SQLAlchemy async engine per process with an `AsyncAdaptedQueuePool` of `DSTACK_DB_POOL_SIZE` (default 20) persistent connections plus `DSTACK_DB_MAX_OVERFLOW` (default 20) overflow connections, i.e. up to 40 connections per server process. When all of them are checked out, the next checkout waits `pool_timeout` (30 seconds) and then fails with:
+
+```
+sqlalchemy.exc.TimeoutError: QueuePool limit of size 20 overflow 20 reached, connection timed out, timeout 30.00
+```
+
+Far more coroutines compete for the slots than there are slots. This works because each of them holds a connection for a short time.
+
+A session does not hold a connection until it executes its first statement. From that moment until the session commits, rolls back, or closes, the connection is checked out and unavailable to anyone else. The invariant that follows:
+
+**Hold a connection only while doing DB work. Do not keep a session open across when doing heavy work.**
+
+On SQLite the same rule applies for a different reason: a long write transaction blocks every other writer for up to `busy_timeout` (30 seconds).
+
+### Awaits that must not run inside a session
+
+Anything whose completion depends on something other than the database:
+
+* SSH: opening tunnels, `aexec()`, `acheck()`, any subprocess.
+* HTTP to runners, shims, gateways, or external services.
+* Cloud SDK calls, including those wrapped in `run_async()`. The thread pool executor is shared, so a saturated executor makes even a fast call wait.
+* Retry loops with sleeps, and waiting on asyncio locks or events that other tasks control.
+* Streaming a response to a client.
+
+Fetch what you need before opening the session, or commit and close the session before the call and open a new one to apply the results:
+
+```python
+async with get_session_ctx() as session:
+ # Load and lock what processing needs.
+ context = await _load_context(session, item)
+
+# No connection is held here.
+result = await _do_network_work(context)
+
+async with get_session_ctx() as session:
+ # Apply results with a guarded update.
+ await _apply_result(session, item, result)
+```
+
+### Session lifetime by context
+
+**Pipelines**
+
+Pipeline workers follow load, process, apply with a short session for the load and apply phases and no session during processing. See `PIPELINES.md`.
+
+**API handlers**
+
+The request session is created before the handler runs. The authentication dependency executes a SELECT on it, so a connection is checked out before the handler starts and stays checked out until the handler returns and the session commits.
+
+This is acceptable because API handlers are assumed to be quick: read or write a few rows and return. A handler that needs to do slow work must not do it while holding the request session's connection. Either:
+
+* Commit the session before the slow work. Committing returns the connection to the pool. The next statement on the session checks out a new connection and starts a new transaction, so any locks taken earlier are released, and the handler must not rely on them across the gap.
+* Make the API async and move the slow work out of the handler.
+
+The rule is not applied currently applied to API handlers strictly: a handler may make one or a few network calls while holding the connection.
+
+**Startup**
+
+Migrations and server initialization may hold a connection and a session-level advisory lock for long: they run once per process, before anything else competes for connections. Recurring cross-replica coordination should use the pipeline lock columns instead.
+
+### Lock waits
+
+A coroutine blocked on a DB-level lock holds its connection while it waits. This applies to `SELECT ... FOR UPDATE` and to `pg_advisory_lock` alike: the waiter occupies a pool slot on its replica until the holder releases the lock. A lock held for a long time thus costs one slot on the holder plus one per waiter, and a hung holder pins all of them.
+
+Keep locked regions short and bounded. See `LOCKING.md` for how to take advisory locks correctly.
+
+### Settings
+
+`DSTACK_DB_COMMAND_TIMEOUT` (default 300 seconds) bounds every operation on a Postgres connection, so a coroutine waiting on a connection whose socket died silently gets an error and releases the slot instead of holding it forever. It applies to migrations too, since they run on the same engine, so it must leave room for index builds and backfills.
+
+`DSTACK_DB_POOL_SIZE` and `DSTACK_DB_MAX_OVERFLOW` size the pool per process. Raising them lets more coroutines hold connections at once, which hides a long hold rather than fixing it, and each replica needs `pool_size + max_overflow` connections from the Postgres `max_connections` budget.
diff --git a/contributing/DOCS.md b/contributing/DOCS.md
index c20076466e..aa07d9673f 100644
--- a/contributing/DOCS.md
+++ b/contributing/DOCS.md
@@ -1,5 +1,11 @@
# Documentation setup
+> **The dstack.ai site has three parts on one origin:** the **landing** page (`/`) is a React
+> app in [`website/`](../website); the **docs** (`/docs`) and **blog** (`/blog`) are built with
+> MkDocs from `mkdocs/`. This guide covers the **docs and blog** (MkDocs). For the landing and
+> for building everything together, see [The landing page](#the-landing-page-website) and
+> [Building the whole site](#building-the-whole-site) below.
+
## 1. Clone the repo:
```shell
@@ -36,14 +42,183 @@ uv run pre-commit install
## 5. Preview documentation
-To preview the documentation, run the follow command:
+To preview the **docs and blog** (MkDocs), run the follow command:
```shell
-uv run mkdocs serve -w examples -s
+uv run mkdocs serve --livereload -s
```
+The `--livereload` flag is required to work around live-reload bugs in recent `mkdocs` versions.
+
+This serves the docs and blog only. The landing page (`/`) is a separate React app — when you
+run `mkdocs serve` on its own, `/` simply redirects to `/docs/`. To work on the landing, see
+[The landing page](#the-landing-page-website) below.
+
If you want to build static files, you can use the following command:
```shell
uv run mkdocs build -s
```
+
+## The landing page (website/)
+
+The landing page at `/` is a React (Vite) app in [`website/`](../website), not MkDocs. It has
+its own `package.json`/`node_modules`. Preview it on its own (requires Node 20+):
+
+```shell
+just website-dev # Vite dev server on http://127.0.0.1:5173
+```
+
+Docs/blog links on the landing resolve same-origin (`/docs`, `/blog`), which 404 in standalone
+dev. Point them at a live site while iterating: `just website-dev https://dstack.ai`.
+
+Keep page metadata in the HTML entries and `website/src/App/index.tsx` in sync.
+When adding or moving product pages, update the [sitemap template](../mkdocs/overrides/sitemap.xml).
+
+## Building the whole site
+
+CI builds the landing and the MkDocs docs/blog and overlays them into a single `site/`:
+
+```shell
+just site-build # website/dist + `mkdocs build` -> ./site (scripts/docs/build_site.sh)
+just site-serve # preview the combined site on http://127.0.0.1:8001
+```
+
+In the combined build the React `index.html` owns `/`, while MkDocs serves `/docs`, `/blog`, and
+the shared `/assets`. This is what the `Build & Deploy Site` workflow deploys.
+
+## Documentation build system
+
+The documentation uses a custom build system with MkDocs hooks to generate various files dynamically.
+
+### Disable flags
+
+Use these in `.envrc` to disable expensive docs regeneration, especially during `mkdocs serve` auto-reload. Set any of them to disable the corresponding artifact.
+
+```shell
+export DSTACK_DOCS_DISABLE_LLM_TXT=1
+export DSTACK_DOCS_DISABLE_CLI_REFERENCE=1
+export DSTACK_DOCS_DISABLE_YAML_SCHEMAS=1
+export DSTACK_DOCS_DISABLE_OPENAPI_REFERENCE=1
+export DSTACK_DOCS_DISABLE_REST_PLUGIN_SPEC_REFERENCE=1
+```
+
+### Build hooks
+
+The build process is customized via hooks in `scripts/docs/hooks.py`:
+
+#### 1. Schema reference expansion
+
+Files in `docs/reference/**/*.md` can use `#SCHEMA#` placeholders that are expanded with generated schema documentation during the build.
+
+#### 2. llms.txt generation
+
+Two files are generated for LLM consumption:
+
+- **llms.txt**: Structured overview of documentation with titles and descriptions
+ - Generated from mkdocs nav structure
+ - Includes sections: Getting started, Concepts, Guides, Examples
+ - Excludes: Reference section
+ - Configuration: `scripts/docs/gen_llms_files.py` (INCLUDE_SECTIONS, EXCLUDE_SECTIONS)
+
+- **llms-full.txt**: Full concatenation of all pages from llms.txt
+ - Contains complete markdown content of all included pages
+
+The generation logic is in `scripts/docs/gen_llms_files.py` and uses:
+- `site_name`, `site_description`, `site_url` from `mkdocs.yml`
+- Page titles from mkdocs nav structure
+- Page descriptions from markdown frontmatter
+
+**Adding descriptions**: To add descriptions to pages, add YAML frontmatter:
+
+```yaml
+---
+title: Page Title
+description: Short description of what this page covers
+---
+```
+
+For examples, add frontmatter to the page files (e.g., `mkdocs/docs/examples/training/trl.md`).
+
+#### 3. Skills discovery
+
+The build creates `.well-known/skills/` directory structure for skills discovery:
+- Reads `skills/dstack/SKILL.md`
+- Parses name and description from frontmatter
+- Generates `.well-known/skills/index.json`
+- Copies SKILL.md to both `.well-known/skills/dstack/` and site root
+
+#### 4. HTTP API reference
+
+The HTTP API reference is generated from the FastAPI OpenAPI schema:
+
+- `scripts/docs/gen_openapi_reference.py` writes `mkdocs/docs/reference/http/openapi.json`,
+ keeps the per-tag Markdown pages in sync, and updates the generated tag list in the HTTP API
+ index page.
+- Tag pages use `!!swagger openapi.json tag=""!!`. Keep tag names exactly as they appear
+ in the OpenAPI schema.
+- `scripts/docs/hooks.py` expands the `!!swagger` directive into the Swagger UI container and
+ the hidden operation headings that MkDocs uses for the page table of contents.
+- `mkdocs/assets/javascripts/swagger.js` loads the shared `openapi.json`, filters it by tag on
+ the client, and adapts Swagger UI markup to the docs layout.
+- `mkdocs/assets/stylesheets/swagger.css` contains Swagger-specific styling and should stay
+ scoped under `.dstack-swagger-ui`.
+
+Keep hook logic limited to build-time Markdown/page structure, generated assets, and data
+attributes needed by the client. Small presentation changes belong in `swagger.css`; small
+behavior changes belong in `swagger.js`.
+
+If the HTTP API reference needs deeper structural customization, such as replacing major Swagger
+UI panels, request/response rendering, model rendering, or "try it out" behavior, prefer moving
+toward a dedicated local bundle or custom Swagger UI layout instead of adding more DOM patching.
+That bundle can still use the single generated `openapi.json` and filter by tag on the client, so
+we should not reintroduce per-tag OpenAPI files unless there is a concrete reason.
+
+### File structure
+
+```
+mkdocs/ # docs_dir for the mkdocs site
+├── index.md # Redirects to /docs/ (the landing "/" is the React app in website/)
+├── docs/ # /docs/ URL section
+│ ├── index.md # Getting started
+│ ├── installation.md
+│ ├── quickstart.md
+│ ├── concepts/ # Concept pages
+│ ├── guides/ # How-to guides
+│ ├── reference/ # API reference (schema expansion)
+│ └── examples/ # Example pages (inline source code)
+│ └── training/
+│ └── trl.md # Page content with frontmatter
+├── blog/ # Blog posts
+├── overrides/ # Theme customization
+├── layouts/ # Social card layouts
+└── assets/ # Stylesheets, images, fonts
+
+website/ # React (Vite) landing page — served at "/"
+├── index.html # Entry; title, OG/meta, Google Analytics
+├── src/ # App, pages (Home, Sky, Factory), components, routes
+└── public/static/ # Landing assets (namespaced to avoid clashing with /assets)
+
+scripts/docs/
+├── build_site.sh # Build landing + docs/blog and overlay into ./site
+├── hooks.py # MkDocs build hooks
+├── gen_llms_files.py # llms.txt generation
+├── gen_schema_reference.py # Schema expansion
+└── gen_cli_reference.py # CLI reference generation
+
+skills/
+└── dstack/
+ └── SKILL.md # Skills discovery content
+```
+
+### Testing changes
+
+When modifying the build system:
+
+1. Test local build: `uv run mkdocs build -s`
+2. Check generated files in `site/`:
+ - `site/llms.txt`
+ - `site/llms-full.txt`
+ - `site/.well-known/skills/index.json`
+3. Verify example pages render correctly
+4. Check that descriptions appear in llms.txt
diff --git a/contributing/FRONTEND.md b/contributing/FRONTEND.md
index 19b623b1d4..afecdaa29d 100644
--- a/contributing/FRONTEND.md
+++ b/contributing/FRONTEND.md
@@ -54,3 +54,18 @@ The `webpack` dev server expects the API to be running on `http://127.0.0.1:8000
```shell
dstack server --port 8000
```
+
+## Product flavors
+
+The shared frontend supports OSS, Enterprise, Factory, and Sky. From `frontend/`, use
+`npm run build`, `npm run build-enterprise`, `npm run build-factory`, or
+`npm run build-sky`; the corresponding development commands are `start`,
+`start-enterprise`, `start-factory`, and `start-sky`.
+
+`frontend/product.config.cjs` defines product names and inherited UI features for both
+webpack and the application. Components use `product` from `src/product.ts` instead of
+checking `UI_VERSION` directly. Factory and Sky share billing and presets; hosted-service
+content such as Sky terms and onboarding uses `product.isSky`.
+
+All flavors use the same login component. It displays supported providers enabled by
+`/api/auth/list_providers`, independently of the UI flavor, and always offers token login.
diff --git a/contributing/GPUHUNT.md b/contributing/GPUHUNT.md
index 33e3150fa1..360e97366d 100644
--- a/contributing/GPUHUNT.md
+++ b/contributing/GPUHUNT.md
@@ -4,10 +4,12 @@
An offer is a possible configuration. It consists of:
- Provider (or backend in dstack)
+- CPU architecture
- CPU count
- RAM size
- Disk size
- GPU count
+- GPU vendor (if any)
- GPU model name (if any)
- GPU VRAM size (if any)
- Is interruptible (or spot)
@@ -15,11 +17,14 @@ An offer is a possible configuration. It consists of:
- Instance name or ID (provider-specific)
- Price per hour
+Offers are represented by `CatalogItem`. Providers construct them directly, setting `provider` to
+their own `NAME`, and `gpu_vendor` whenever `gpu_count` is non-zero.
+
## Catalog
Some providers don't have a suitable API for querying all offers in real-time. That's why gpuhunt has two types of providers:
-- Online — offers can be queried in real-time
+- Online — offers can be queried quickly in real-time
- Offline — offers must be loaded from a precomputed catalog file
The `Catalog` class hides those details from the user, reading offers from the file for offline providers or querying online providers.
@@ -28,7 +33,16 @@ The `Catalog` class pulls the latest catalog from the S3 bucket and caches it fo
## Provider implementation
-Providers must implement a single method `get`. It has the same name for both online and offline providers but works differently.
+Providers subclass either `OnlineProvider` or `OfflineProvider` from `src/gpuhunt/providers/base.py`.
+
+Both implement `get`. It has the same name for both online and offline providers but works differently.
+
+In addition:
+
+- Online providers implement the `from_env` classmethod, since `default_catalog()` constructs them
+ in the user's process.
+- Offline providers may override `filter` to omit some offers from the published catalog.
+ Credentials are passed in by the caller, so a missing one is an error rather than a skip.
### Offers sorting
@@ -100,7 +114,7 @@ These mechanisms are used to preserve backward compatibility:
- **`gpuhunt` version**: The interfaces in the `gpuhunt` package preserve backward compatibility
within a minor version (`X` in `0.X.Y`).
-- **Offer flags**: If an offer breaks older `dstack` versions, it is marked with a flag in `RawCatalogItem.flags`
+- **Offer flags**: If an offer breaks older `dstack` versions, it is marked with a flag in `CatalogItem.flags`
and the flag is added to the list of supported flags in `dstack`.
Older `dstack` versions that don't support this flag will not see the respective offers.
- **Offline catalog versions**: If a breaking change in the structure or content of an offline catalog is unavoidable,
diff --git a/contributing/LOCKING.md b/contributing/LOCKING.md
index e23fb41f9e..420c493c01 100644
--- a/contributing/LOCKING.md
+++ b/contributing/LOCKING.md
@@ -1,7 +1,6 @@
# Locking
-The `dstack` server supports SQLite and Postgres databases
-with two implementations of resource locking to handle concurrent access:
+The `dstack` server supports SQLite and Postgres databases with two implementations of resource locking to handle concurrent access:
* In-memory locking for SQLite.
* DB-level locking for Postgres.
@@ -30,15 +29,15 @@ Locksets are an optimization. One can think of them as per-resource-id locks tha
Postgres resource locking is implemented via standard SELECT FOR UPDATE.
SQLAlchemy provides `.with_for_update()` that has no effect if SELECT FOR UPDATE is not supported as in SQLite.
-There are few places that rely on advisory locks as when generating unique resource names.
+There are few places that rely on advisory locks as when generating unique resource names or serializing server initialization across replicas. See **Advisory locks** below.
## Working with locks
-Concurrency is hard. Below you'll find common patterns and gotchas when working with locks to make it a bit more manageable.
+Concurrency is hard. Concurrency with locking is especially hard. Below you'll find common patterns and gotchas when working with locks to make it a bit more manageable.
**A task should acquire locks on resources it modifies**
-This is a common sense approach. An alternative could be the inverse: job processing cannot run in parallel with run processing, so job processing takes run lock. This indirection complicates things and is discouraged. In this example, run processing should take job lock instead.
+This is common sense. An alternative could be the inverse: job processing cannot run in parallel with run processing, so job processing takes run lock. This indirection complicates things and is discouraged. In this example, run processing should take job lock instead.
**Start new transaction after acquiring a lock to see other transactions changes in SQLite.**
@@ -75,15 +74,19 @@ unlock resources
If a transaction releases a lock before committing changes, the changes may not be visible to another transaction that acquired the lock and relies upon seeing all committed changes.
-**Don't use `joinedload` when selecting `.with_for_update()`**
+**Using `joinedload` when selecting `.with_for_update()`**
-In fact, using `joinedload` and `.with_for_update()` will trigger an error because `joinedload` produces OUTER LEFT JOIN that cannot be used with SELECT FOR UPDATE. A regular `.join()` can be used to lock related resources but it may lead to no rows if there is no row to join. Usually, you'd select with `selectinload` or first select with `.with_for_update()` without loading related attributes and then re-selecting with `joinedload` without `.with_for_update()`.
+Using `joinedload` and `.with_for_update()` triggers an error in case of no related rows because `joinedload` produces OUTER LEFT JOIN and SELECT FOR UPDATE cannot be applied to the nullable side of an OUTER JOIN. Here's the options:
+
+* Use `.with_for_update(of=MainModel)`.
+* Select with `selectinload`
+* First select with `.with_for_update()` without loading related attributes and then re-select with `joinedload` without `.with_for_update()`.
+* Use regular `.join()` to lock related resources, but you may get 0 rows if there is no related row to join.
**Always use `.with_for_update(key_share=True)` unless you plan to delete rows or update a primary key column**
If you `SELECT FOR UPDATE` from a table that is referenced in a child table via a foreign key, it can lead to deadlocks if the child table is updated because Postgres will issue a `FOR KEY SHARE` lock on the parent table rows to ensure valid foreign keys. For this reason, you should always do `SELECT FOR NO KEY UPDATE` (.`with_for_update(key_share=True)`) if primary key columns are not modified. `SELECT FOR NO KEY UPDATE` is not blocked by a `FOR KEY SHARE` lock, so no deadlock.
-
**Lock unique names**
The following pattern can be used to lock a unique name of some resource type:
@@ -109,6 +112,39 @@ Note that:
* This pattern works assuming that Postgres is using default isolation level Read Committed. By the time a transaction acquires the advisory lock, all other transactions that can take the name have committed, so their changes can be seen and a unique name is taken.
* SQLite needs a commit before selecting taken names due to Snapshot Isolation as noted above.
+**Advisory locks**
+
+Postgres has two kinds of advisory locks:
+
+* `pg_advisory_xact_lock` is released when the transaction ends. The unique names pattern above uses it.
+* `pg_advisory_lock` is bound to the connection. It survives commit and rollback and is released only by `pg_advisory_unlock` on the same connection or when the connection closes. `advisory_lock_ctx()` in `services/locking.py` wraps this kind for work that must span several transactions, such as migrations or server initialization.
+
+Within a single transaction, prefer `pg_advisory_xact_lock` for automatic release on commit or rollback. When using `advisory_lock_ctx()`, the requirement is to acquire and release the lock on the same physical connection:
+
+* An `AsyncSession` is a valid bind when the locked block stays within one transaction. Do not commit, roll back, or close the session before releasing the lock.
+* If the block spans multiple transactions, hold an `AsyncConnection` from `engine.connect()` and bind the lock and any sessions to it. Otherwise, a session's next transaction may use a different pooled connection, and `pg_advisory_unlock` goes to a connection that never held the lock. Postgres only returns `false` with a warning in this case, so the failure is silent: the lock stays on an idle pooled connection until the process exits, and every replica blocks forever on its next acquire. See https://github.com/dstackai/dstack/issues/3881 for an example.
+* Run protected DB work on the connection holding the lock. When binding a new session to an explicit connection, end the lock statement's transaction first so that the session controls its own transactions. If the connection is lost, abort the protected operation instead of reconnecting and continuing without the lock.
+* Keep the locked block short and bounded. Every waiter is blocked inside `pg_advisory_lock` holding a DB connection of its own, so a long or hung holder pins one connection per waiter. See `DATABASE.md`.
+
+For a block that spans multiple transactions:
+
+```python
+async with get_db().engine.connect() as connection:
+ async with advisory_lock_ctx(
+ bind=connection,
+ dialect_name=get_db().dialect_name,
+ resource="server_init",
+ ):
+ # End the lock statement's transaction. The session-level lock survives the commit.
+ await connection.commit()
+ async with get_db().get_session(bind=connection) as session:
+ # Session commits keep using the connection that holds the lock.
+ ...
+ await session.commit()
+```
+
+A released connection goes back to the pool, so a lock that failed to release stays there too. `_release_advisory_lock()` tolerates failures because the common one is an invalidated connection, in which case Postgres has already dropped the lock. A release that fails on a live connection strands the lock.
+
**Use `AsyncExitStack`**
In-memory locking typically requires taking lock for long (until commit).
diff --git a/contributing/MIGRATIONS.md b/contributing/MIGRATIONS.md
index 8918d9e36b..f494d829d5 100644
--- a/contributing/MIGRATIONS.md
+++ b/contributing/MIGRATIONS.md
@@ -47,3 +47,29 @@ These steps apply to **renaming a column** or **changing the type of a column**
### Altering multiple tables
Altering a table requires Postgres to [take an ACCESS EXCLUSIVE lock](https://www.postgresql.org/docs/current/sql-altertable.html). (This applies not only to statements that rewrite the tables but also to statements that modify tables metadata.) Altering multiple tables can cause deadlocks due to conflict with read operations since the `dstack` server does not define an order for read operations. Altering multiple tables should be done in separate transactions/migrations.
+
+### Adding indexes
+
+Use `CREATE INDEX CONCURRENTLY` to avoid tacking exclusive lock on the table for a long time.
+For migrations that create multiple indexes, failures can leave the schema in a partial state
+(some indexes already created, some missing). On Postgres, concurrent index creation can also fail
+midway and leave an invalid index object with the same name. Retrying the migration then fails
+with "already exists".
+
+For retry-safe migrations, pre-drop indexes with `if_exists=True` before creating them again:
+
+```python
+with op.get_context().autocommit_block():
+ op.drop_index(
+ "ix_table_col",
+ table_name="table",
+ if_exists=True,
+ postgresql_concurrently=True,
+ )
+ op.create_index(
+ "ix_table_col",
+ "table",
+ ["col"],
+ postgresql_concurrently=True,
+ )
+```
diff --git a/contributing/PIPELINES.md b/contributing/PIPELINES.md
new file mode 100644
index 0000000000..7e01c2465e
--- /dev/null
+++ b/contributing/PIPELINES.md
@@ -0,0 +1,127 @@
+# Pipelines
+
+This document describes how the `dstack` server implements background processing via so-called "pipelines".
+
+*Historical context: `dstack` used to do all background processing via scheduled tasks. A scheduled task would process a specific resource type like volumes or runs by keeping DB transaction open for the entire processing duration and keeping the resource lock with SELECT FOR UPDATE (or in-memory lock on SQLite). This approach didn't scale well because the number of DB connections was a huge bottleneck. Pipelines replaced scheduled tasks: the do all the heavy processing outside of DB transactions and write locks to DB columns.*
+
+## Overview
+
+* Resources are continuously processed in the background by pipelines. A pipeline consists of a fetcher, workers, and a heartbeater.
+* A fetcher selects rows to be processed from the DB, marks them as locked in the DB, and puts them into an in-memory queue.
+* Workers consume rows from the in-memory queue, process the rows, and unlock them.
+* The locking (unlocking) is done by setting (unsetting) `lock_expires_at`, `lock_token`, `lock_owner`.
+* If the replica/pipeline dies, the rows stay locked in the db. Another replica picks up the rows after `lock_expires_at`.
+* `lock_token` prevents stale replica/pipeline to update the rows already picked up by the new replica.
+* `lock_owner` stores the pipeline that's locked the row so that only that pipeline can recover if it's stale.
+* A heartbeater tracks all rows in the pipeline (in the queue or in processing), and updates the lock expiration. This allows setting small `lock_expires_at` and picking up stale rows quickly
+* A fetcher performs the fetch when the queue size goes under a configured lower limit. It has exponential retry delays between empty fetches, thus reducing load on the DB.
+* There is a fetch hint mechanism that services can use to notify the pipelines within the replica – in that case the fetcher stops sleeping and fetches immediately.
+* Each pipeline locks one main resource but may lock related resources as well. It's not necessary to heartbeat related resources if the pipeline ensures no one else can re-lock them. This is typically done via setting and respecting `lock_owner`.
+
+Related notes:
+
+* All write APIs must respect DB-level locks. The endpoints can either try to acquire the lock with a timeout and error or provide an async API by storing the request in the DB.
+
+## Implementation checklist
+
+Brief checklist for implementing a new pipeline:
+
+1. Fetcher locks only rows that are ready for processing:
+`status/time` filters, `lock_expires_at` is empty or expired, and `lock_owner` is empty or equal to the pipeline name. Keep the fetch order stable with `last_processed_at`.
+2. Fetcher takes row locks with `skip_locked` and updates `lock_expires_at`, `lock_token`, `lock_owner` before enqueueing items.
+3. Worker keeps heavy work outside DB sessions. DB sessions should be short and used only for refetch/locking and final apply.
+4. Apply stage updates rows using update maps/update rows, not by relying on mutating detached ORM models.
+5. Main apply update is guarded by `id + lock_token`. If the update affects `0` rows, the item is stale and processing results must not be applied.
+6. Successful apply updates `last_processed_at` and unlocks resources that were locked by this item.
+7. If related lock is unavailable, reset main lock for retry: keep `lock_owner`, clear `lock_token` and `lock_expires_at`, and set `last_processed_at` to now.
+8. Register the pipeline in `PipelineManager` and hint fetch from services after commit via `pipeline_hinter.hint_fetch(Model.__name__)`.
+9. Add minimum tests: fetch eligibility/order, successful unlock path, stale lock token path, and related lock contention retry path.
+
+## Typical worker structure
+
+Most workers are easiest to reason about when `process()` is split into three phases:
+
+1. Load/refetch: open a short DB session, refetch the locked main row by `id + lock_token`, lock any required related rows, and gather any extra data needed for processing.
+2. Process: do the heavy work outside DB sessions and build result objects or update maps instead of mutating detached ORM models.
+3. Apply: open a short DB session, guard the main update by `id + lock_token`, resolve time placeholders, apply related updates, emit events, and unlock rows.
+
+A dedicated context object is often useful for the load step when the worker needs multiple loaded models, related lock metadata, or derived values that should be passed cleanly into processing and apply. For very small pipelines, a direct load -> process -> apply flow may still be clearer.
+
+Workers can share one context type and one apply function across all states even if the processing logic differs by state:
+
+```python
+async def process(item):
+ context = await _load_process_context(item)
+ if context is None:
+ return
+ result = await _process_item(context)
+ await _apply_process_result(item, context, result)
+```
+
+Sometimes state-specific helpers are still the cleanest option, but they can still share a common apply phase if all states write results in the same general shape:
+
+```python
+async def process(item):
+ if item.status == Status.PENDING:
+ context = await _load_pending_context(item)
+ elif item.status == Status.RUNNING:
+ context = await _load_running_context(item)
+ else:
+ return
+ if context is None:
+ return
+ result = await _process_item(context)
+ await _apply_process_result(item, context, result)
+```
+
+If different states have materially different write-side behavior, different apply paths are fine as well. This commonly happens when one state does a normal guarded update while another does delete-or-cleanup work with different related updates:
+
+```python
+async def process(item):
+ if item.to_be_deleted:
+ await _process_to_be_deleted_item(item)
+ elif item.status == Status.SUBMITTED:
+ await _process_submitted_item(item)
+```
+
+It's ok not to force all pipelines into one exact shape.
+
+## Implementation patterns
+
+**Guarded apply by lock token**
+
+When writing processing results, update the main row with a filter by both `id` and `lock_token`. This guarantees that only the worker that still owns the lock can apply its results. If the update affects no rows, treat the item as stale and skip applying other changes (status changes, related updates, events). A stale item means another worker or replica already continued processing.
+
+**Locking related resources before refetch**
+
+If you first refetch a main resource and only after lock the related resources, you need to ensure the worker doesn't get the stale view on related resources or works properly even in this case. It's often more robust to first lock related resources and then refetch the main resource with related resources already locked.
+
+**Locking many related resources**
+
+A pipeline may need to lock a potentially big set of related resource, e.g. fleet pipeline locking all fleet's instances. For this, do one SELECT FOR UPDATE of non-locked instances and one SELECT to see how many instances there are, and check if you managed to lock all of them. If fail to lock, release the main lock and try processing on another fetch iteration. You may keep `lock_owner` on the main resource or set `lock_owner` on locked related resource and make other pipelines respect that to guarantee the eventual locking of all related resources and avoid lock starvation.
+
+**Locking a shared related resource**
+
+Multiple main resources may need to lock the same related resource, e.g. multiple jobs may need to change the shared instance. In this case it's not sufficient to set `lock_owner` on the related resource to the pipeline name because workers processing different main resources can still race with each other. To avoid heartbeating the related resource, you may include main resource id in `lock_owner`, e.g. set `lock_owner = f"{Pipeline.__name__}:{item.id}"`.
+
+**Reset-and-retry when related lock is unavailable**
+
+If a worker cannot lock a required related resource, it should release only the main lock state needed for fast retry: unset `lock_token` and `lock_expires_at`, keep `lock_owner`, and set `last_processed_at` to now. This avoids long waiting and lets the same pipeline retry quickly on the next fetch iteration while other pipelines can still respect ownership intent.
+
+**Dealing with side effects**
+
+If processing has side effects and the apply phase fails due to a lock mismatch, there are several options: a) revert side effects b) make processing idempotent, i.e. next processing iteration detects side effects does not perform duplicating actions c) log side effects as errors and warn user about possible issues such as orphaned instances – as a temporary solution.
+
+**Bulk apply with one consistent current time**
+
+When apply needs to update multiple rows (main + related resources), build update maps/update rows first and resolve current-time placeholders once in the apply transaction using `NOW_PLACEHOLDER` + `resolve_now_placeholders()`. This keeps timestamps consistent across all rows and avoids subtle ordering bugs when the same processing pass writes several `*_at` fields.
+
+## Performance analysis
+
+* Pipeline throughput = workers_num / worker_processing_time. So quick tasks easily give high-throughput pipelines, e.g. 1s task with 20 workers is 1200 tasks/min.
+A slow 30s task gives only 40 tasks/min with the same number of workers. We can increase the number of workers but the peak memory usage will grow proportionally.
+In general, workers should be optimized to be as quick as possible to improve throughput.
+* Processing latency (wait) is close to 0 due to fetch hints if the pipeline is not saturated. In general, latency = queue_size / throughput.
+* In-memory queue maxsize provides a cap on memory usage and recovery time after crashes (number of locked items to retry).
+* Fetcher's DB load is proportional to the number of pipelines and is expected to be negligible. Workers can put a considerable read/write DB load as it's proportional to the number of workers. This can be optimized by batching workers' writes. Workers do processing outside of transactions so DB connections won't be a bottleneck.
+* There is a risk of lock starvation if a worker needs to lock all related resources. This is to be mitigated by 1) related pipelines checking `lock_owner` and skip locking to let the parent pipeline acquire all the locks eventually and 2) do the related resource locking only on paths that require it.
diff --git a/contributing/PROXY.md b/contributing/PROXY.md
index bc79c4fbbe..a8dc522cc8 100644
--- a/contributing/PROXY.md
+++ b/contributing/PROXY.md
@@ -127,7 +127,7 @@ There are also similar gateway-specific helper functions to obtain gateway-speci
## Gateway operations
-Gateway instances are managed by the `dstack` server. A gateway is associated with a project and some backend in the project. In `dstack` Sky, there is also a global gateway associated with all projects.
+Gateway instances are managed by the `dstack` server. A gateway is associated with a project and some backend in the project. Gateways can be shared between projects using Exports.
### Creation
@@ -137,7 +137,7 @@ Provisioning happens as follows:
1. Launch a non-GPU instance (usually the smallest) with all ports exposed.
2. Install Nginx, Certbot, and patch configs.
3. Create blue-green virtual environments.
-4. Install the latest `dstack-gateway` package from the S3 bucket. `dstack-gateway` is a thin package that depends on the `dstack` package, which contains the actual gateway implementation.
+4. Install the `dstack[gateway]` Python package.
5. Run the systemd service `dstack.gateway.service`.
### Update
@@ -152,56 +152,18 @@ The update process looks like this:
## Gateway development
-The gateway app needs to interact with Nginx and certbot, so running it locally can be challenging. One way to test your code is to upload your development branch to an existing gateway and run the gateway app from source.
+The gateway app needs to interact with Nginx and certbot, so running it locally can be challenging. You can test your development version by deploying it to a live gateway.
-1. Run `dstack server` with `DSTACK_SKIP_GATEWAY_UPDATE=1` environment variable. This will prevent `dstack` from updating and starting the standard gateway version on each server restart.
+For example, push your version to GitHub and run `dstack server` with the `DSTACK_GATEWAY_PACKAGE_URL` environment variable, which will instruct `dstack` to deploy that version to all gateways.
-1. Provision a gateway through `dstack`:
-
- ```shell
- dstack apply -f my-gateway.dstack.yml
- ```
-
-1. Save the gateway key to a file:
-
- ```shell
- sqlite3 ~/.dstack/server/data/sqlite.db "SELECT ssh_private_key FROM gateway_computes WHERE deleted = 0 AND ip_address = ''" > /tmp/gateway.key
- chmod 600 /tmp/gateway.key
- ```
-
-1. Deliver your code to the gateway. For example, clone it from a remote repo:
-
- ```shell
- ssh -i /tmp/gateway.key ubuntu@gateway.example "git clone https://github.com/dstackai/dstack.git ~/dstack-repo"
- ```
-
- Or push it from your machine:
-
- ```shell
- ssh -i /tmp/gateway.key ubuntu@gateway.example "git init ~/dstack-repo"
- git remote add gateway ubuntu@gateway.example:~/dstack-repo
- GIT_SSH_COMMAND='ssh -i /tmp/gateway.key' git push gateway branch_name
- ```
-
-1. Connect to the gateway:
-
- ```shell
- ssh -i /tmp/gateway.key ubuntu@gateway.example
- ```
-
-1. Prepare an environment with your development branch on the gateway:
-
- ```shell
- cd ~/dstack-repo
- git checkout branch_name
- curl -LsSf https://astral.sh/uv/install.sh | sh
- source ~/.local/bin/env
- uv sync --extra gateway
- ```
+```shell
+DSTACK_GATEWAY_PACKAGE_URL=https://github.com/dstackai/dstack/archive/refs/heads/my_development_branch.zip dstack server
+```
-1. Stop the gateway service and start your development version from source:
+To access logs or troubleshoot, extract the gateway's private key from the database and connect to it via SSH. Logs are available in `journalctl`.
- ```shell
- sudo systemctl stop dstack.gateway.service
- uv run uvicorn dstack._internal.proxy.gateway.main:app
- ```
+```shell
+sqlite3 ~/.dstack/server/data/sqlite.db "SELECT ssh_private_key FROM gateway_computes WHERE deleted = 0 AND ip_address = '$GATEWAY_IP_ADDR'" > /tmp/gateway.key
+chmod 600 /tmp/gateway.key
+ssh -i /tmp/gateway.key ubuntu@$GATEWAY_IP_ADDR sudo journalctl -u dstack.gateway.service
+```
diff --git a/contributing/RELEASE.md b/contributing/RELEASE.md
index 56df59595e..f0798082fc 100644
--- a/contributing/RELEASE.md
+++ b/contributing/RELEASE.md
@@ -8,7 +8,10 @@ This is a `dstack` release guide and checklist for core maintainers.
1. Compare changes to the previous release, e.g. [`https://github.com/dstackai/dstack/compare/0.19.39...master`](https://github.com/dstackai/dstack/compare/0.19.39...master).
2. Test that `master` CLI works with the previous server release. PRs that add new model fields can potentially break client backward compatibility.
3. Test that `master` server works with the previous CLI release.
- 4. Pay special attention to releases with DB migrations. Migrations should work with rolling deployments and avoid locking multiple tables. See [MIGRATIONS.md](MIGRATIONS.md).
+ 4. Pay special attention to releases with DB migrations. See [MIGRATIONS.md](MIGRATIONS.md).
+ * Ensure migrations work with rolling deployments and do not lock multiple tables.
+ * Test applying migrations while old replicas do active processing.
+ * Test migrations can be retried if they fail. For example, concurrent index may fail and stay in invalid state.
2. Create a tag, e.g. `git tag 0.19.40`.
3. Push the tag to trigger the Release `workflow`, i.e. `git push --tags`.
4. Generate GitHub release notes from the tag. Highlight major features, deprecations, breaking changes.
diff --git a/contributing/RUNNER-AND-SHIM.md b/contributing/RUNNER-AND-SHIM.md
index edccdc14aa..bbb09ed4ff 100644
--- a/contributing/RUNNER-AND-SHIM.md
+++ b/contributing/RUNNER-AND-SHIM.md
@@ -31,7 +31,7 @@ A container is started in either `host` or `bridge` network mode depending on th
In `bridge` mode, container ports are mapped to ephemeral host ports. `dstack-shim` stores port mapping as a part of task's state. Currently, the default `bridge` network is used for all containers, but this could be changed in the future to improve container isolation.
-All communication between the `dstack` server and `dstack-shim` happens via REST API through an SSH tunnel. `dstack-shim` doesn't collect logs. Usually, it is run from a `cloud-init` user-data script.
+All communication between the `dstack` server and `dstack-shim` happens via HTTP API through an SSH tunnel. `dstack-shim` doesn't collect logs. Usually, it is run from a `cloud-init` user-data script.
The entrypoint for the container:
- Installs `openssh-server`
@@ -52,10 +52,10 @@ The entrypoint for the container:
- Wait for the signal to terminate the commands
- STEP 5: Wait until all logs are read by the server and the CLI. Or exit after a timeout
-All communication between the `dstack` server and `dstack-runner` happens via REST API through an SSH tunnel. `dstack-runner` collects the job logs and its own logs. Only the job logs are served via WebSocket.
+All communication between the `dstack` server and `dstack-runner` happens via HTTP API through an SSH tunnel. `dstack-runner` collects the job logs and its own logs. Only the job logs are served via WebSocket.
## SSH tunnels
-`dstack` expects a running SSH server right next to the `dstack-runner`. It provides a secure channel for communication with the runner API and forwarding any ports without listening for `0.0.0.0`. The `dstack-gateway` also uses this SSH server for forwarding requests from public endpoints.
+`dstack` expects a running SSH server right next to the `dstack-runner`. It provides a secure channel for communication with the runner API and forwarding any ports without listening for `0.0.0.0`. The gateway also uses this SSH server for forwarding requests from public endpoints.
`dstack-shim` must also be running next to the SSH server. The `dstack` server connects to this SSH server for interacting with both `dstack-shim` and `dstack-runner`. The CLI uses this SSH server as a jump host because the user wants to connect to the container.
diff --git a/contributing/RUNS-AND-JOBS.md b/contributing/RUNS-AND-JOBS.md
index 32725b7353..2f00e751be 100644
--- a/contributing/RUNS-AND-JOBS.md
+++ b/contributing/RUNS-AND-JOBS.md
@@ -17,31 +17,38 @@ A run can spawn one or multiple jobs, depending on the configuration. A task tha
## Run's Lifecycle
-- STEP 1: The user submits the run. `services.runs.submit_run` creates jobs with status `SUBMITTED`. Now the run has status `SUBMITTED`.
-- STEP 2: `background.tasks.process_runs` periodically pulls unfinished runs and processes them:
- - If any job is `RUNNING`, the run becomes `RUNNING`.
- - If any job is `PROVISIONING` or `PULLING`, the run becomes `PROVISIONING`.
- - If any job fails and cannot be retried, the run becomes `TERMINATING`, and after processing, `FAILED`.
- - If all jobs are `DONE`, the run becomes `TERMINATING`, and after processing, `DONE`.
- - If any job fails, can be retried, and there is any other active job, the failed job will be resubmitted in-place.
- - If any jobs in a replica fail and can be retried and there is other active replicas, the jobs of the failed replica are resubmitted in-place (without stopping other replicas). But if some jobs in a replica fail, then all the jobs in a replica are terminated and resubmitted. This include multi-node tasks that represent one replica with multiple jobs.
- - If all jobs fail and can be resubmitted, the run becomes `PENDING`.
-- STEP 3: If the run is `TERMINATING`, the server makes all jobs `TERMINATING`. `background.tasks.process_runs` sets their status to `TERMINATING`, assigns `JobTerminationReason`, and sends a graceful stop command to `dstack-runner`. `process_terminating_jobs` then ensures that jobs are terminated assigns a finished status.
-- STEP 4: Once all jobs are finished, the run becomes `TERMINATED`, `DONE`, or `FAILED` based on `RunTerminationReason`.
-- STEP 0: If the run is `PENDING`, `background.tasks.process_runs` will resubmit jobs. The run becomes `SUBMITTED` again.
-
-> Use `switch_run_status()` for all status transitions. Do not set `RunModel.status` directly.
-
-> No one must assign the finished status to the run, except `services.runs.process_terminating_run`. To terminate the run, assign `TERMINATING` status and `RunTerminationReason`.
+- STEP 1: The user submits the run. `services.runs.submit_run` creates jobs with status `SUBMITTED`. The run starts in `SUBMITTED`.
+- STEP 2: `RunPipeline` continuously processes unfinished runs.
+ - For active runs, it derives the run status from the latest job states in priority order:
+ 1. If any non-retryable failure is present, the run becomes `TERMINATING` with the relevant `RunTerminationReason`.
+ 2. If `stop_criteria == MASTER_DONE` and the master job is done, the run becomes `TERMINATING` with `ALL_JOBS_DONE`.
+ 3. Otherwise, if any job is `RUNNING`, the run becomes `RUNNING`.
+ 4. Otherwise, if any job is `PROVISIONING` or `PULLING`, the run becomes `PROVISIONING`.
+ 5. Otherwise, if jobs are still waiting for placement or provisioning, the run stays `SUBMITTED`.
+ 6. Otherwise, if all contributing jobs are `DONE`, the run becomes `TERMINATING` with `ALL_JOBS_DONE`.
+ 7. Otherwise, if no active replicas remain and the run should be retried, the run becomes `PENDING`.
+ - Retryable replica failures are handled before the final transition is applied:
+ - If a replica fails with a retryable reason while other replicas are still active, `RunPipeline` creates a new `SUBMITTED` submission for that replica and terminates the old jobs in that replica.
+ - If all remaining work is retryable, the run ends up in `PENDING`.
+- STEP 3: If the run is `PENDING`, `RunPipeline` processes it in the pending phase.
+ - For retrying runs, it waits for an exponential backoff before resubmitting.
+ - For scheduled runs, it waits until `next_triggered_at`.
+ - For scaled-to-zero services, it can keep the run in `PENDING` until autoscaling wants replicas again.
+ - Once the run is ready to continue, `RunPipeline` creates new `SUBMITTED` jobs and moves the run back to `SUBMITTED`.
+- STEP 4: If the run is `TERMINATING`, `RunPipeline` marks active jobs as `TERMINATING` and assigns the corresponding `JobTerminationReason`.
+- STEP 5: Once all jobs are finished, the terminating phase of `RunPipeline` either:
+ - assigns the final run status (`TERMINATED`, `DONE`, or `FAILED`), or
+ - for scheduled runs that were not stopped or aborted by the user, returns the run to `PENDING` and computes a new `next_triggered_at`.
### Services
-Services' lifecycle has some modifications:
+Services' run lifecycle has some modifications:
-- During STEP 1, the service is registered on the gateway. If the gateway is not accessible or the domain name is taken, the run submission fails.
-- During STEP 2, downscaled jobs are ignored.
-- During STEP 4, the service is unregistered on the gateway.
-- During STEP 0, the service can stay in `PENDING` status if it was downscaled to zero (WIP).
+- During STEP 1, the service itself is registered on the gateway or the in-server proxy. If the gateway is not accessible or the domain name is taken, submission fails.
+- During STEP 2, active run processing also computes desired replica counts from gateway stats and handles scale-up, scale-down, rolling deployment, and cleanup of removed replica groups.
+- During STEP 2, jobs already marked `SCALED_DOWN` do not contribute to the run status.
+- During STEP 3, a service can stay in `PENDING` when autoscaling currently wants zero replicas.
+- During STEP 5, the terminating phase of `RunPipeline` unregisters the service from the gateway.
### When can the job be retried?
@@ -54,29 +61,27 @@ Services' lifecycle has some modifications:
## Job's Lifecycle
- STEP 1: A newly submitted job has status `SUBMITTED`. It is not assigned to any instance yet.
-- STEP 2: `background.tasks.process_submitted_jobs` tries to assign an existing instance or provision a new one.
- - On success, the job becomes `PROVISIONING`.
- - On failure, the job becomes `TERMINATING`, and after processing, `FAILED` because of `FAILED_TO_START_DUE_TO_NO_CAPACITY`.
-- STEP 3: `background.tasks.process_running_jobs` periodically pulls unfinished jobs and processes them.
- - While `dstack-shim`/`dstack-runner` is not responding, the job stays `PROVISIONING`.
- - Once `dstack-shim` (for VM-featured backends) becomes available, it submits the docker image name, and the job becomes `PULLING`.
- - Once `dstack-runner` inside a docker container becomes available, it submits the code and the job spec, and the job becomes `RUNNING`.
- - If `dstack-shim` or `dstack-runner` don't respond for a long time or fail to respond after successful connection and multiple retries, the job becomes `TERMINATING`, and after processing, `FAILED`.
-- STEP 4: `background.tasks.process_running_jobs` processes `RUNNING` jobs, pulling job logs, runner logs, and job status.
- - If the pulled status is `DONE`, the job becomes `TERMINATING`, and after processing, `DONE`.
- - Otherwise, the job becomes `TERMINATING`, and after processing, `FAILED`.
-- STEP 5: `background.tasks.process_terminating_jobs` processes `TERMINATING` jobs.
- - If the job has `remove_at` in the future, nothing happens. This is to give the job some time for a graceful stop.
- - Once `remove_at` is in the past, it stops the container via `dstack-shim`, detaches instance volumes, and releases the instance. The job becomes `TERMINATED`, `DONE`, `FAILED`, or `ABORTED` based on `JobTerminationReason`.
- - If some volumes fail to detach, it keeps the job `TERMINATING` and checks volumes attachment status.
-
-> Use `switch_job_status()` for all status transitions. Do not set `JobModel.status` directly.
-
-> No one must assign the finished status to the job, except `services.jobs.process_terminating_job`. To terminate the job, assign `TERMINATING` status and `JobTerminationReason`.
+- STEP 2: `JobSubmittedPipeline` assigns the job in two phases:
+ - Assignment: claim an existing instance or reserve a *placeholder* `InstanceModel`. Placeholders are `PENDING` instances that reserve an `instance_num` and a `nodes.max` slot. `InstancePipeline` ignores them.
+ - Provisioning: reuse the existing instance, or cloud-provision and promote the placeholder to `PROVISIONING`.
+ - On success, the job becomes `PROVISIONING`.
+ - On failure, the job becomes `TERMINATING`. `JobTerminatingPipeline` later assigns the final failed status.
+- STEP 3: `JobRunningPipeline` processes `PROVISIONING`, `PULLING`, and `RUNNING` jobs.
+ - While `dstack-shim` / `dstack-runner` is not responding, the job stays `PROVISIONING`.
+ - Once `dstack-shim` (for VM-featured backends) becomes available, the pipeline submits the image and the job becomes `PULLING`.
+ - Once `dstack-runner` inside the container becomes available, the pipeline uploads the code and job spec, and the job becomes `RUNNING`.
+ - While the job is `RUNNING`, the pipeline keeps collecting logs and runner status.
+ - If startup, runner communication, or replica registration fails, the job becomes `TERMINATING`.
+- STEP 4: Once the job is actually ready, `JobRunningPipeline` initializes probes.
+- STEP 5: `JobTerminatingPipeline` processes `TERMINATING` jobs.
+ - If the job has `remove_at` in the future, it waits. This gives the job time for a graceful stop.
+ - Once `remove_at` is in the past, it stops the container, detaches volumes, unregisters service replicas if needed, and releases the instance assignment.
+ - If some volumes are not detached yet, the job stays `TERMINATING` and is retried.
+ - When cleanup is complete, the job becomes `TERMINATED`, `DONE`, `FAILED`, or `ABORTED` based on `JobTerminationReason`.
### Services' Jobs
Services' jobs lifecycle has some modifications:
-- During STEP 3, once the job becomes `RUNNING`, it is registered on the gateway as a replica. If the gateway is not accessible, the job fails.
-- During STEP 5, the job is unregistered on the gateway (WIP).
+- During STEP 3, once the primary job of a replica is `RUNNING` and ready to receive traffic, `JobRunningPipeline` registers that replica on the gateway. If the gateway is not accessible, the job fails with a gateway-related termination reason.
+- During STEP 5, `JobTerminatingPipeline` unregisters the replica from receiving requests before the job is fully cleaned up.
diff --git a/docker/base/Dockerfile b/docker/base/Dockerfile
index 29e92f45ba..36da212b75 100644
--- a/docker/base/Dockerfile
+++ b/docker/base/Dockerfile
@@ -1,17 +1,72 @@
-# syntax = edrevo/dockerfile-plus
ARG UBUNTU_VERSION
-# Build stage
-FROM nvidia/cuda:12.8.1-base-ubuntu${UBUNTU_VERSION}.04 AS builder
+# ============================================================================
+# common: shared base for all flavors. Select a flavor with `--target `
+# (base / devel / devel-efa).
+# ============================================================================
+
+FROM nvidia/cuda:13.0.3-base-ubuntu${UBUNTU_VERSION}.04 AS common
+
+# ARGs before FROM must be redeclared to be used after FROM
+ARG UBUNTU_VERSION
+
+ARG _UV_HOME="/opt/uv"
+
+ENV UV_INSTALL_DIR="${_UV_HOME}/bin"
+ENV UV_MANAGED_PYTHON=1
+ENV LANG=C.UTF-8 LC_ALL=C.UTF-8
+
+ENV PATH="${UV_INSTALL_DIR}:${PATH}"
+
+ENV OMPI_MCA_pml=^cm,ucx
+ENV OMPI_MCA_btl=tcp,self
+ENV OMPI_MCA_btl_tcp_if_exclude=lo,docker0
+ENV NCCL_SOCKET_IFNAME=^docker,lo
+
+RUN export DEBIAN_FRONTEND=noninteractive \
+ && apt-get update --fix-missing \
+ && apt-get upgrade -y \
+ && ln -fs /usr/share/zoneinfo/America/New_York /etc/localtime \
+ && apt-get install -y tzdata \
+ && dpkg-reconfigure --frontend noninteractive tzdata \
+ && apt-get install -y bzip2 ca-certificates curl build-essential git libglib2.0-0 libsm6 libxext6 libxrender1 openssh-server wget \
+ libibverbs1 ibverbs-providers ibverbs-utils libibverbs-dev infiniband-diags \
+ # nvidia/cuda ships nvidia's apt singing key in legacy format (/etc/apt/trusted.gpg).
+ # This lead to warnings, so we install cuda-keyring.
+ && wget https://developer.download.nvidia.com/compute/cuda/repos/ubuntu${UBUNTU_VERSION}04/x86_64/cuda-keyring_1.1-1_all.deb \
+ && dpkg -i cuda-keyring_1.1-1_all.deb \
+ && rm cuda-keyring_1.1-1_all.deb \
+ && rm -f /etc/apt/sources.list.d/cuda.list \
+ && sed -i "s/.*PasswordAuthentication.*/PasswordAuthentication no/g" /etc/ssh/sshd_config \
+ && mkdir /run/sshd \
+ && mkdir -p ~/.ssh && chmod 700 ~/.ssh && touch ~/.ssh/authorized_keys \
+ && chmod 600 ~/.ssh/authorized_keys \
+ && rm /etc/ssh/ssh_host_* \
+ # User: UID/GID 1001 because Ubuntu 24.04 ships a default 'ubuntu' user at 1000.
+ && apt-get install -y sudo \
+ && groupadd -g 1001 dstack \
+ && useradd -u 1001 -g 1001 -G sudo -s /bin/bash -m dstack \
+ && echo 'dstack ALL=(ALL) NOPASSWD: ALL' > /etc/sudoers.d/dstack \
+ # Default working dir
+ && mkdir -p /dstack/run \
+ && chmod a+rwx /dstack/run \
+ # Cleanup
+ && rm -rf /var/lib/apt/lists/*
+
+RUN curl -LsSf https://astral.sh/uv/install.sh | INSTALLER_NO_MODIFY_PATH=1 sh \
+ && uv python install --preview --default
+
+# ============================================================================
+# builder: builds NCCL and nccl-tests from source for the base/devel flavors.
+# ============================================================================
+
+FROM nvidia/cuda:13.0.3-base-ubuntu${UBUNTU_VERSION}.04 AS builder
ENV NCCL_HOME=/opt/nccl
ENV CUDA_HOME=/usr/local/cuda
ENV OPEN_MPI_PATH=/usr/lib/x86_64-linux-gnu/openmpi
-# Prerequisites
-
RUN export DEBIAN_FRONTEND=noninteractive \
- && apt-key adv --fetch-keys https://developer.download.nvidia.com/compute/cuda/repos/ubuntu${UBUNTU_VERSION}04/x86_64/3bf863cc.pub \
&& apt-get update --fix-missing \
&& apt-get upgrade -y \
&& ln -fs /usr/share/zoneinfo/America/New_York /etc/localtime \
@@ -31,17 +86,13 @@ RUN export DEBIAN_FRONTEND=noninteractive \
python3 \
build-essential
-# NCCL
-
-ARG NCCL_VERSION=2.26.2-1
+ARG NCCL_VERSION=2.28.3-1
RUN cd /tmp \
&& git clone https://github.com/NVIDIA/nccl.git -b v${NCCL_VERSION} \
&& cd nccl \
&& make -j$(nproc) src.build BUILDDIR=${NCCL_HOME}
-# NCCL tests
-
RUN cd /opt \
&& git clone https://github.com/NVIDIA/nccl-tests \
&& cd nccl-tests \
@@ -51,31 +102,86 @@ RUN cd /opt \
CUDA_HOME=${CUDA_HOME} \
NCCL_HOME=${NCCL_HOME}
-# Final stage
+# ============================================================================
+# base: common + NCCL (from builder) + OpenMPI.
+# ============================================================================
-INCLUDE+ base/Dockerfile.common
+FROM common AS base
ENV NCCL_HOME=/opt/nccl
COPY --from=builder ${NCCL_HOME} ${NCCL_HOME}
COPY --from=builder /opt/nccl-tests/build /opt/nccl-tests/build
-ARG FLAVOR
-
-# MPI, NVCC, and /etc/ld.so.conf.d
-
RUN apt-get update \
- && apt-get install -y --no-install-recommends \
- openmpi-bin \
- && if [ "$FLAVOR" = "devel" ]; then \
- cuda_version=$(echo ${CUDA_VERSION} | awk -F . '{ print $1"-"$2 }') \
- && apt-get install -y --no-install-recommends \
- cuda-libraries-dev-${cuda_version} \
- cuda-nvcc-${cuda_version} \
- libhwloc-dev; \
- fi \
+ && apt-get install -y --no-install-recommends openmpi-bin \
&& rm -rf /var/lib/apt/lists/* \
&& echo "${NCCL_HOME}/lib" >> /etc/ld.so.conf.d/nccl.conf \
&& ldconfig
WORKDIR /dstack/run
+
+# ============================================================================
+# devel: base + CUDA development libraries and NVCC.
+# ============================================================================
+
+FROM base AS devel
+
+RUN cuda_version=$(echo ${CUDA_VERSION} | awk -F . '{ print $1"-"$2 }') \
+ && apt-get update \
+ && apt-get install -y --no-install-recommends \
+ cuda-libraries-dev-${cuda_version} \
+ cuda-nvcc-${cuda_version} \
+ libhwloc-dev \
+ && rm -rf /var/lib/apt/lists/*
+
+WORKDIR /dstack/run
+
+# ============================================================================
+# devel-efa: common + CUDA dev libraries + AWS EFA + EFA-aware NCCL.
+# ============================================================================
+
+FROM common AS devel-efa
+
+ENV NCCL_HOME=/usr/local
+ENV CUDA_HOME=/usr/local/cuda
+ENV LIBFABRIC_PATH=/opt/amazon/efa
+ENV OPEN_MPI_PATH=/opt/amazon/openmpi
+ENV PATH="${LIBFABRIC_PATH}/bin:${OPEN_MPI_PATH}/bin:${PATH}"
+ENV LD_LIBRARY_PATH="${OPEN_MPI_PATH}/lib:${LD_LIBRARY_PATH}"
+
+RUN cuda_version=$(echo ${CUDA_VERSION} | awk -F . '{ print $1"-"$2 }') \
+ && apt-get update \
+ && apt-get install -y --no-install-recommends \
+ cuda-libraries-dev-${cuda_version} \
+ cuda-nvcc-${cuda_version} \
+ && rm -rf /var/lib/apt/lists/*
+
+ARG EFA_VERSION=1.48.0
+
+RUN cd /tmp \
+ && apt-get update \
+ && curl -O https://s3-us-west-2.amazonaws.com/aws-efa-installer/aws-efa-installer-${EFA_VERSION}.tar.gz \
+ && tar -xf aws-efa-installer-${EFA_VERSION}.tar.gz \
+ && cd aws-efa-installer \
+ && ./efa_installer.sh -y --skip-kmod -g \
+ && rm -rf /tmp/aws-efa-installer /var/lib/apt/lists/*
+
+ARG NCCL_VERSION=2.28.3-1
+
+RUN cd /tmp \
+ && git clone https://github.com/NVIDIA/nccl.git -b v${NCCL_VERSION} \
+ && cd nccl \
+ && make -j$(nproc) src.build BUILDDIR=${NCCL_HOME} \
+ && rm -rf /tmp/nccl
+
+RUN cd /opt \
+ && git clone https://github.com/NVIDIA/nccl-tests \
+ && cd nccl-tests \
+ && make -j$(nproc) \
+ MPI=1 \
+ MPI_HOME=${OPEN_MPI_PATH} \
+ CUDA_HOME=${CUDA_HOME} \
+ NCCL_HOME=${NCCL_HOME}
+
+WORKDIR /dstack/run
diff --git a/docker/base/Dockerfile.common b/docker/base/Dockerfile.common
deleted file mode 100644
index b486c16800..0000000000
--- a/docker/base/Dockerfile.common
+++ /dev/null
@@ -1,44 +0,0 @@
-ARG UBUNTU_VERSION
-
-FROM nvidia/cuda:12.8.1-base-ubuntu${UBUNTU_VERSION}.04
-
-ARG _UV_HOME="/opt/uv"
-
-ENV UV_INSTALL_DIR="${_UV_HOME}/bin"
-ENV UV_MANAGED_PYTHON=1
-ENV LANG=C.UTF-8 LC_ALL=C.UTF-8
-
-ENV PATH="${UV_INSTALL_DIR}:${PATH}"
-
-ENV OMPI_MCA_pml=^cm,ucx
-ENV OMPI_MCA_btl=tcp,self
-ENV OMPI_MCA_btl_tcp_if_exclude=lo,docker0
-ENV NCCL_SOCKET_IFNAME=^docker,lo
-
-RUN export DEBIAN_FRONTEND=noninteractive \
- && apt-key adv --fetch-keys https://developer.download.nvidia.com/compute/cuda/repos/ubuntu${UBUNTU_VERSION}04/x86_64/3bf863cc.pub \
- && apt-get update --fix-missing \
- && apt-get upgrade -y \
- && ln -fs /usr/share/zoneinfo/America/New_York /etc/localtime \
- && apt-get install -y tzdata \
- && dpkg-reconfigure --frontend noninteractive tzdata \
- && apt-get install -y bzip2 ca-certificates curl build-essential git libglib2.0-0 libsm6 libxext6 libxrender1 mercurial openssh-server subversion wget \
- libibverbs1 ibverbs-providers ibverbs-utils libibverbs-dev infiniband-diags \
- && sed -i "s/.*PasswordAuthentication.*/PasswordAuthentication no/g" /etc/ssh/sshd_config \
- && mkdir /run/sshd \
- && mkdir ~/.ssh && chmod 700 ~/.ssh && touch ~/.ssh/authorized_keys \
- && chmod 600 ~/.ssh/authorized_keys \
- && rm /etc/ssh/ssh_host_* \
- # User
- && apt-get install -y sudo \
- && groupadd -g 1000 dstack \
- && useradd -u 1000 -g 1000 -G sudo -s /bin/bash -m dstack \
- && echo 'dstack ALL=(ALL) NOPASSWD: ALL' > /etc/sudoers.d/dstack \
- # Default working dir
- && mkdir -p /dstack/run \
- && chmod a+rwx /dstack/run \
- # Cleanup
- && rm -rf /var/lib/apt/lists/*
-
-RUN curl -LsSf https://astral.sh/uv/install.sh | INSTALLER_NO_MODIFY_PATH=1 sh \
- && uv python install --preview --default
diff --git a/docker/base/README.md b/docker/base/README.md
index 3bbbafa732..5246cbc40b 100644
--- a/docker/base/README.md
+++ b/docker/base/README.md
@@ -1 +1,19 @@
-Image for `dstack` runner instances.
+# dstack base images
+
+Base images for `dstack` runner instances. A single multi-stage `Dockerfile`
+produces all flavors; select one with `docker build --target `:
+
+- **base** — CUDA 12.8, Python (uv-managed), NCCL 2.26.2-1 + NCCL Tests, Open MPI.
+- **devel** — `base` plus the CUDA development libraries and NVCC.
+- **devel-efa** — `base` plus CUDA dev libraries, AWS EFA Installer 1.48.0
+ (Libfabric + Open MPI + AWS OFI NCCL 1.19.0), and an EFA-aware NCCL 2.27.7-1
+ build + NCCL Tests.
+
+Build args: `UBUNTU_VERSION` (e.g. `24`).
+
+Example:
+
+```bash
+docker build --target devel-efa --build-arg UBUNTU_VERSION=24 \
+ -t dstackai/base:local-devel-efa-ubuntu24.04 -f base/Dockerfile .
+```
diff --git a/docker/base/efa/Dockerfile b/docker/base/efa/Dockerfile
deleted file mode 100644
index 105650a836..0000000000
--- a/docker/base/efa/Dockerfile
+++ /dev/null
@@ -1,78 +0,0 @@
-# syntax = edrevo/dockerfile-plus
-
-INCLUDE+ base/Dockerfile.common
-
-ENV NCCL_HOME=/usr/local
-ENV CUDA_HOME=/usr/local/cuda
-ENV LIBFABRIC_PATH=/opt/amazon/efa
-ENV OPEN_MPI_PATH=/opt/amazon/openmpi
-ENV PATH="${LIBFABRIC_PATH}/bin:${OPEN_MPI_PATH}/bin:${PATH}"
-ENV LD_LIBRARY_PATH="${OPEN_MPI_PATH}/lib:${LD_LIBRARY_PATH}"
-
-# Prerequisites
-
-RUN cuda_version=$(echo ${CUDA_VERSION} | awk -F . '{ print $1"-"$2 }') \
- && apt-get update \
- && apt-get install -y --no-install-recommends \
- cuda-libraries-dev-${cuda_version} \
- cuda-nvcc-${cuda_version} \
- libhwloc-dev \
- autoconf \
- automake \
- libtool \
- && rm -rf /var/lib/apt/lists/*
-
-# EFA
-
-ARG EFA_VERSION=1.38.1
-
-RUN cd /tmp \
- && apt-get update \
- && curl -O https://s3-us-west-2.amazonaws.com/aws-efa-installer/aws-efa-installer-${EFA_VERSION}.tar.gz \
- && tar -xf aws-efa-installer-${EFA_VERSION}.tar.gz \
- && cd aws-efa-installer \
- && ./efa_installer.sh -y --skip-kmod -g \
- && rm -rf /tmp/aws-efa-installer /var/lib/apt/lists/*
-
-# NCCL
-
-ARG NCCL_VERSION=2.26.2-1
-
-RUN cd /tmp \
- && git clone https://github.com/NVIDIA/nccl.git -b v${NCCL_VERSION} \
- && cd nccl \
- && make -j$(nproc) src.build BUILDDIR=${NCCL_HOME} \
- && rm -rf /tmp/nccl
-
-# AWS OFI NCCL
-
-ARG OFI_VERSION=1.14.0
-
-RUN cd /tmp \
- && git clone https://github.com/aws/aws-ofi-nccl.git -b v${OFI_VERSION} \
- && cd aws-ofi-nccl \
- && ./autogen.sh \
- && ./configure \
- --with-cuda=${CUDA_HOME} \
- --with-libfabric=${LIBFABRIC_PATH} \
- --with-mpi=${OPEN_MPI_PATH} \
- --with-cuda=${CUDA_HOME} \
- --with-nccl=${NCCL_HOME} \
- --disable-tests \
- --prefix=${NCCL_HOME} \
- && make -j$(nproc) \
- && make install \
- && rm -rf /tmp/aws-ofi-nccl /var/lib/apt/lists/*
-
-# NCCL Tests
-
-RUN cd /opt \
- && git clone https://github.com/NVIDIA/nccl-tests \
- && cd nccl-tests \
- && make -j$(nproc) \
- MPI=1 \
- MPI_HOME=${OPEN_MPI_PATH} \
- CUDA_HOME=${CUDA_HOME} \
- NCCL_HOME=${NCCL_HOME}
-
-WORKDIR /dstack/run
diff --git a/docker/base/efa/README.md b/docker/base/efa/README.md
deleted file mode 100644
index 29ed748213..0000000000
--- a/docker/base/efa/README.md
+++ /dev/null
@@ -1,9 +0,0 @@
-# dstack AWS EFA
-
-This image has the following installed:
-
-* CUDA 12.1
-* AWS EFA Installer 1.38.1 (Libfabric + Open MPI 4 + Open MPI 5)
-* NCCL 2.26.2-1
-* AWS OFI NCCL 1.14.0
-* NCCL Tests
diff --git a/docker/server/README.md b/docker/server/README.md
index 611dbe6cac..2c91a4e152 100644
--- a/docker/server/README.md
+++ b/docker/server/README.md
@@ -22,6 +22,27 @@ The admin user token is 'bbae0f28-d3dd-4820-bf61-8f4bb40815da'
For more details on server configuration options, see the
[server deployment](https://dstack.ai/docs/guides/server-deployment.md) guide.
+### Run with PostgreSQL and the SSH proxy
+
+In production, the `dstack` server is usually run with
+[PostgreSQL](https://dstack.ai/docs/guides/server-deployment#postgresql) instead of the default
+SQLite, and with the [SSH proxy](https://dstack.ai/docs/guides/server-deployment#ssh-proxy). The
+[`docker-compose.yml`](https://github.com/dstackai/dstack/blob/master/docker/server/docker-compose.yml)
+runs that combination locally, so you can try or test a production-like server on your own machine.
+A full production deployment would also configure external
+[logs storage](https://dstack.ai/docs/guides/server-deployment#logs-storage) and
+[file storage](https://dstack.ai/docs/guides/server-deployment#file-storage).
+
+```shell
+docker compose -f docker/server/docker-compose.yml up
+```
+
+This starts PostgreSQL, the `dstack` server at `http://localhost:3000`, and the SSH proxy at
+`localhost:30022`. The admin token is printed to the logs (`docker compose logs server`).
+
+To access the server from the CLI, add it as a project with `dstack project add`, using the
+admin token from the logs (see [Set up the CLI](#set-up-the-cli) below).
+
## Set up the CLI
To point the CLI to the `dstack` server, configure it
diff --git a/docker/server/docker-compose.yml b/docker/server/docker-compose.yml
new file mode 100644
index 0000000000..529271059c
--- /dev/null
+++ b/docker/server/docker-compose.yml
@@ -0,0 +1,73 @@
+name: dstack
+
+services:
+ postgres:
+ image: postgres:16
+ restart: unless-stopped
+ environment:
+ POSTGRES_USER: ${DSTACK_POSTGRES_USER:-dstack}
+ POSTGRES_PASSWORD: ${DSTACK_POSTGRES_PASSWORD:-dstack}
+ POSTGRES_DB: ${DSTACK_POSTGRES_DB:-dstack}
+ volumes:
+ - postgres-data:/var/lib/postgresql/data
+ healthcheck:
+ test: ["CMD-SHELL", "pg_isready -U $$POSTGRES_USER -d $$POSTGRES_DB"]
+ interval: 5s
+ timeout: 5s
+ retries: 10
+
+ server:
+ image: dstackai/dstack:latest # multi-arch — no platform override needed
+ restart: unless-stopped
+ depends_on:
+ postgres:
+ condition: service_healthy
+ environment:
+ DSTACK_DATABASE_URL: postgresql+asyncpg://${DSTACK_POSTGRES_USER:-dstack}:${DSTACK_POSTGRES_PASSWORD:-dstack}@postgres:5432/${DSTACK_POSTGRES_DB:-dstack}
+ DSTACK_SERVER_LOG_FORMAT: rich # human-readable console logs (image defaults to json)
+ # Shared secret between the server and the SSH proxy. The default works locally;
+ # override with a real secret for non-local deployments.
+ DSTACK_SSHPROXY_API_TOKEN: ${DSTACK_SSHPROXY_API_TOKEN:-dstack-sshproxy-token}
+ # Address clients use to reach the SSH proxy. `localhost:30022` is correct for a
+ # client on the same host; use a publicly reachable address for multi-host setups.
+ DSTACK_SERVER_SSHPROXY_ADDRESS: localhost:30022
+ volumes:
+ - server-data:/root/.dstack/server # config.yml + run logs (Postgres holds the rest)
+ ports:
+ - "3000:3000"
+
+ # One-shot init: generates the SSH proxy's host key into a shared volume so no manual
+ # ssh-keygen is needed. The proxy refuses to start without a host key.
+ sshproxy-keygen:
+ image: alpine:3
+ command:
+ - sh
+ - -c
+ - |
+ apk add --no-cache openssh-keygen >/dev/null
+ [ -f /keys/host_key ] || ssh-keygen -t ed25519 -f /keys/host_key -N "" -C dstack-sshproxy
+ volumes:
+ - sshproxy-keys:/keys
+
+ sshproxy:
+ image: dstackai/sshproxy:latest
+ platform: linux/amd64 # image is amd64-only; emulated on Apple Silicon
+ restart: unless-stopped
+ depends_on:
+ sshproxy-keygen:
+ condition: service_completed_successfully
+ server:
+ condition: service_started
+ environment:
+ DSTACK_SSHPROXY_API_URL: http://server:3000
+ DSTACK_SSHPROXY_API_TOKEN: ${DSTACK_SSHPROXY_API_TOKEN:-dstack-sshproxy-token}
+ command: ["--host-key", "/keys/host_key"]
+ volumes:
+ - sshproxy-keys:/keys
+ ports:
+ - "30022:30022"
+
+volumes:
+ postgres-data:
+ server-data:
+ sshproxy-keys:
diff --git a/docker/server/entrypoint.sh b/docker/server/entrypoint.sh
index 6a87468490..8cd67fd260 100644
--- a/docker/server/entrypoint.sh
+++ b/docker/server/entrypoint.sh
@@ -13,15 +13,9 @@ if [[ -z "${LITESTREAM_REPLICA_URL}" ]]; then
exec dstack server --host 0.0.0.0
else
if [[ ! -f "$DB_PATH" ]]; then
- echo "Attempting Litestream restore..."
- if ! output=$(litestream restore -o "$DB_PATH" "$LITESTREAM_REPLICA_URL" 2>&1); then
- if echo "$output" | grep -qiE "cannot calc restore plan"; then
- echo "No replica snapshots found; starting with empty database."
- else
- echo "$output" >&2
- exit 1
- fi
- fi
+ echo "Starting db restore"
+ litestream restore -if-replica-exists -o "$DB_PATH" "$LITESTREAM_REPLICA_URL"
+ echo "Finished db restore"
fi
exec litestream replicate -exec "dstack server --host 0.0.0.0" "$DB_PATH" "$LITESTREAM_REPLICA_URL"
fi
diff --git a/docker/server/release/Dockerfile b/docker/server/release/Dockerfile
index ca94a26f2e..a88439d61e 100644
--- a/docker/server/release/Dockerfile
+++ b/docker/server/release/Dockerfile
@@ -15,8 +15,8 @@ RUN apt-get update && apt-get install -y \
&& rm -rf /var/lib/apt/lists/*
RUN if [ $(uname -m) = "aarch64" ]; then ARCH="arm64"; else ARCH="x86_64"; fi && \
- curl https://github.com/benbjohnson/litestream/releases/download/v0.5.0/litestream-0.5.0-linux-$ARCH.deb -O -L && \
- dpkg -i litestream-0.5.0-linux-$ARCH.deb
+ curl https://github.com/benbjohnson/litestream/releases/download/v0.5.9/litestream-0.5.9-linux-$ARCH.deb -O -L && \
+ dpkg -i litestream-0.5.9-linux-$ARCH.deb
ADD https://astral.sh/uv/install.sh /uv-installer.sh
RUN sh /uv-installer.sh && rm /uv-installer.sh
diff --git a/docker/server/stgn/Dockerfile b/docker/server/stgn/Dockerfile
index 1933ed636c..4fce817787 100644
--- a/docker/server/stgn/Dockerfile
+++ b/docker/server/stgn/Dockerfile
@@ -23,8 +23,8 @@ RUN apt-get update && apt-get install -y \
&& rm -rf /var/lib/apt/lists/*
RUN if [ $(uname -m) = "aarch64" ]; then ARCH="arm64"; else ARCH="x86_64"; fi && \
- curl https://github.com/benbjohnson/litestream/releases/download/v0.5.0/litestream-0.5.0-linux-$ARCH.deb -O -L && \
- dpkg -i litestream-0.5.0-linux-$ARCH.deb
+ curl https://github.com/benbjohnson/litestream/releases/download/v0.5.9/litestream-0.5.9-linux-$ARCH.deb -O -L && \
+ dpkg -i litestream-0.5.9-linux-$ARCH.deb
ADD https://astral.sh/uv/install.sh /uv-installer.sh
RUN sh /uv-installer.sh && rm /uv-installer.sh
@@ -33,6 +33,8 @@ ENV PATH="/root/.local/bin/:$PATH"
COPY pyproject.toml uv.lock README.md ./
COPY src src
COPY examples examples
+# pyproject force-includes skills/*/SKILL.md into the wheel, so uv sync needs them.
+COPY skills skills
# Copy built frontend to statics directory
COPY --from=frontend-builder /frontend/build src/dstack/_internal/server/statics
diff --git a/docker/tt-smi/Dockerfile b/docker/tt-smi/Dockerfile
index b8417e4259..da190db313 100644
--- a/docker/tt-smi/Dockerfile
+++ b/docker/tt-smi/Dockerfile
@@ -1,4 +1,4 @@
-FROM ubuntu:20.04
+FROM ubuntu:22.04
ARG IMAGE_NAME
ARG TT_SMI_VERSION
@@ -10,7 +10,8 @@ RUN \
apt-get update && \
apt-get install -y curl git python3 python3-pip && \
curl --proto '=https' --tlsv1.2 -sSf https://sh.rustup.rs | sh -s -- -y && \
- pip3 install --no-cache-dir git+https://github.com/tenstorrent/tt-smi@v${TT_SMI_VERSION} && \
+ pip3 install --no-cache-dir --upgrade pip setuptools wheel tomli && \
+ pip3 install --no-cache-dir --no-build-isolation git+https://github.com/tenstorrent/tt-smi@v${TT_SMI_VERSION} && \
apt-get clean && \
rm -rf /var/lib/apt/lists/*
diff --git a/docs/assets/javascripts/extra.js b/docs/assets/javascripts/extra.js
deleted file mode 100644
index 30bdcd5fd6..0000000000
--- a/docs/assets/javascripts/extra.js
+++ /dev/null
@@ -1,165 +0,0 @@
-controller = (function () {
- let setupEventListeners = function () {
- document.addEventListener('keydown', function (event) {
- if (event.keyCode === 75 && (event.metaKey || event.ctrlKey)) {
- document.querySelector('.md-search__input').focus()
- }
- });
- };
- return {
- init: function () {
- setupEventListeners();
- }
- };
-})();
-
-controller.init();
-
-function setupTermynal() {
- document.querySelectorAll(".use-termynal").forEach(node => {
- node.style.display = "block";
- new Termynal(node, {
- lineDelay: 500
- });
- });
- const progressLiteralStart = "---> 100%";
- const promptLiteralStart = "$ ";
- const customPromptLiteralStart = "# ";
- const termynalActivateClass = "termy";
- let termynals = [];
-
- function createTermynals() {
- document
- .querySelectorAll(`.${termynalActivateClass} .highlight`)
- .forEach(node => {
- const text = node.textContent;
- const lines = text.split(/(? {
- if (line) {
- isBlankSpace = false;
- }
- });
- dataValue = {};
- if (isBlankSpace) {
- dataValue["delay"] = 0;
- }
- if (buffer[buffer.length - 1] === "") {
- // A last single won't have effect
- // so put an additional one
- buffer.push("");
- }
- const bufferValue = buffer.join(" ");
- dataValue["value"] = bufferValue;
- useLines.push(dataValue);
- buffer = [];
- }
- }
- for (let line of lines) {
- if (line === progressLiteralStart) {
- saveBuffer();
- useLines.push({
- type: "progress"
- });
- } else if (line.startsWith(promptLiteralStart)) {
- saveBuffer();
- const value = line.replace(promptLiteralStart, "").trimEnd();
- useLines.push({
- type: "input",
- value: value
- });
- } else if (line.startsWith("// ")) {
- saveBuffer();
- const value = "💬 " + line.replace("// ", "").trimEnd();
- useLines.push({
- value: value,
- class: "termynal-comment",
- delay: 0
- });
- } else if (line.startsWith(customPromptLiteralStart)) {
- saveBuffer();
- const promptStart = line.indexOf(promptLiteralStart);
- if (promptStart === -1) {
- console.error("Custom prompt found but no end delimiter", line)
- }
- const prompt = line.slice(0, promptStart).replace(customPromptLiteralStart, "")
- let value = line.slice(promptStart + promptLiteralStart.length);
- useLines.push({
- type: "input",
- value: value,
- prompt: prompt
- });
- } else {
- buffer.push(line);
- }
- }
- saveBuffer();
- const div = document.createElement("div");
- node.replaceWith(div);
- const termynal = new Termynal(div, {
- lineData: useLines,
- noInit: true,
- lineDelay: 500,
- typeDelay: 20
- });
- termynals.push(termynal);
- });
- }
-
- function loadVisibleTermynals() {
- termynals = termynals.filter(termynal => {
- if (termynal.container.getBoundingClientRect().top - innerHeight <= 0) {
- termynal.init();
- return false;
- }
- return true;
- });
- }
- window.addEventListener("scroll", loadVisibleTermynals);
- createTermynals();
- loadVisibleTermynals();
-}
-
-function setupCustomCodeTitles() {
- document.querySelectorAll("div[editor-title]").forEach(div => {
- let code = div.getElementsByTagName('code')[0];
- // code.setAttribute("editor-title", div.getAttribute("editor-title"))
- let editorTitle = document.createElement("span")
- editorTitle.className = "editor-title"
- editorTitle.innerHTML = div.getAttribute("editor-title")
- code.appendChild(editorTitle)
- });
-}
-
-window.addEventListener("DOMContentLoaded", function() {
- let tabs = document.querySelector(".md-tabs")
- let header = document.querySelector(".md-header")
- let search = document.querySelector(".md-search")
- search.parentNode.insertBefore(tabs, search)
- header.classList.add("ready")
- setupTermynal()
- setupCustomCodeTitles()
-});
-
-(function () {
- document.querySelectorAll('.tx-faq__item').forEach(function (faqItem) {
- faqItem.querySelector('.tx-faq__item-title').addEventListener('click', function () {
- if (faqItem.classList.contains('_open')) {
- faqItem.classList.remove('_open')
- } else {
- faqItem.classList.add('_open')
- }
- });
- })
-
- document.querySelectorAll('a[href^="http"]').forEach(link => {
- if (!link.href.includes(location.hostname)) {
- link.setAttribute('target', '_blank');
- link.setAttribute('rel', 'noopener noreferrer');
- }
- });
-})()
diff --git a/docs/assets/stylesheets/termynal.css b/docs/assets/stylesheets/termynal.css
deleted file mode 100644
index 436db2b65b..0000000000
--- a/docs/assets/stylesheets/termynal.css
+++ /dev/null
@@ -1,125 +0,0 @@
-/**
- * termynal.js
- *
- * @author Ines Montani
- * @version 0.0.1
- * @license MIT
- */
-
-:root {
- --color-bg: rgb(21, 22, 29);
- --color-text: #eee;
- --color-text-subtle: #a2a2a2;
-}
-
-[data-termynal] span {
- white-space: pre;
-}
-
-.small > [data-termynal] {
- font-size: 14px;
- line-height: 1.4;
-}
-
-[data-termynal] {
- margin-block-start: 1em;
- margin-block-end: 1em;
- overflow-x: scroll;
- /*white-space: pre;*/
- /*width: 750px;*/
- max-width: 100%;
- background: var(--color-bg);
- color: var(--color-text);
- /* font-size: 18px; */
- font-size: 14px;
- /* font-family: 'Fira Mono', Consolas, Menlo, Monaco, 'Courier New', Courier, monospace; */
- font-family: var(--md-code-font-family) !important;
- border-radius: 3px;
- padding: 45px 25px 25px;
- /*padding: 75px 45px 35px;*/
- position: relative;
- -webkit-box-sizing: border-box;
- box-sizing: border-box;
-}
-
-[data-termynal]:before {
- content: '';
- position: absolute;
- top: 15px;
- left: 15px;
- display: inline-block;
- width: 12px;
- height: 12px;
- border-radius: 50%;
- /* A little hack to display the window buttons in one pseudo element. */
- background: #d9515d;
- /*-webkit-box-shadow: 25px 0 0 #f4c025, 50px 0 0 #3ec930;*/
- /* box-shadow: 25px 0 0 #f4c025, 50px 0 0 #3ec930;*/
- -webkit-box-shadow: 20px 0 0 #f4c025, 40px 0 0 #3ec930;
- box-shadow: 20px 0 0 #f4c025, 40px 0 0 #3ec930;
-}
-
-[data-termynal]:after {
- content: '';
- position: absolute;
- color: var(--color-text-subtle);
- top: 7px;
- left: 0;
- width: 100%;
- text-align: center;
-}
-
-a[data-terminal-control] {
- text-align: right;
- display: block;
- color: #aebbff;
-}
-
-[data-ty] {
- display: block;
- line-height: 2;
-}
-
-[data-ty]:before {
- /* Set up defaults and ensure empty lines are displayed. */
- content: '';
- display: inline-block;
- vertical-align: middle;
-}
-
-[data-ty="input"]:before,
-[data-ty-prompt]:before {
- margin-right: 0.75em;
- color: var(--color-text-subtle);
-}
-
-[data-ty="input"]:before {
- content: '$';
-}
-
-[data-ty][data-ty-prompt]:before {
- content: attr(data-ty-prompt);
-}
-
-[data-ty-cursor]:after {
- content: attr(data-ty-cursor);
- font-family: monospace;
- margin-left: 0.5em;
- -webkit-animation: blink 1s infinite;
- animation: blink 1s infinite;
-}
-
-
-/* Cursor animation */
-
-@-webkit-keyframes blink {
- 50% {
- opacity: 0;
- }
-}
-
-@keyframes blink {
- 50% {
- opacity: 0;
- }
-}
diff --git a/docs/docs/concepts/fleets.md b/docs/docs/concepts/fleets.md
deleted file mode 100644
index 99912cd75b..0000000000
--- a/docs/docs/concepts/fleets.md
+++ /dev/null
@@ -1,516 +0,0 @@
-# Fleets
-
-Fleets act both as pools of instances and as templates for how those instances are provisioned.
-
-`dstack` supports two kinds of fleets:
-
-* [Backend fleets](#backend-fleets) – dynamically provisioned through configured backends; they are supported with any type of backends: [VM-based](backends.md#vm-based) and [container-based](backends.md#container-based) (incl. [Kubernetes](backends.md#kubernetes))
-* [SSH fleets](#ssh-fleets) – created using on-prem servers; do not require backends
-
-When you submit a dev environment, task, or service, `dstack` reuses idle instances or provisions new ones based on the fleet configuration.
-
-> You must create a fleet before submitting runs.
-
-## Backend fleets
-
-Backend fleets allow provisioning compute across cloud providers or Kubernetes clusters.
-
-??? info "Prerequisites"
- Before creating a backend fleet, make sure to configure the corresponding [backends](backends.md).
-
-### Apply the configuration
-
-To create a backend fleet, define a configuration as a YAML file. The file must have a
-`.dstack.yml` extension (e.g. `.dstack.yml` or `fleet.dstack.yml`).
-
-
-
- ```yaml
- type: fleet
- # The name is optional, if not specified, generated randomly
- name: default
-
- # Can be a range or a fixed number
- # Allow to provision of up to 2 instances
- nodes: 0..2
-
- # Uncomment to ensure instances are inter-connected
- #placement: cluster
-
- # Deprovision instances above the minimum if they remain idle
- idle_duration: 1h
-
- resources:
- # Allow to provision up to 8 GPUs
- gpu: 0..8
- ```
-
-
-
-To create or update the fleet, pass the fleet configuration to [`dstack apply`](../reference/cli/dstack/apply.md):
-
-
-
-If `nodes` is a range that starts above `0`, `dstack` pre-creates the initial number of instances up front, while any additional ones are created on demand.
-
-> Setting the `nodes` range to start above `0` is supported only for [VM-based backends](backends.md#vm-based).
-
-??? info "Target number of nodes"
-
- If `nodes` is defined as a range, you can start with more than the minimum number of instances by using the `target` parameter when creating the fleet.
-
-
-
-By default, when you submit a [dev environment](dev-environments.md), [task](tasks.md), or [service](services.md), `dstack` tries all available fleets. However, you can explicitly specify the [`fleets`](../reference/dstack.yml/dev-environment.md#fleets) in your run configuration
-or via [`--fleet`](../reference/cli/dstack/apply.md#fleet) with `dstack apply`.
-
-### Configuration options
-
-#### Placement { #backend-placement }
-
-To ensure instances are interconnected (e.g., for
-[distributed tasks](tasks.md#distributed-tasks)), set `placement` to `cluster`.
-This ensures all instances are provisioned with optimal inter-node connectivity.
-
-??? info "AWS"
- When you create a fleet with AWS, [Elastic Fabric Adapter networking](https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/efa.html) is automatically configured if it’s supported for the corresponding instance type.
- Note, EFA requires the `public_ips` to be set to `false` in the `aws` backend configuration.
- Otherwise, instances are only connected by the default VPC subnet.
-
- Refer to the [AWS](../../examples/clusters/aws/index.md) example for more details.
-
-??? info "GCP"
- When you create a fleet with GCP, `dstack` automatically configures [GPUDirect-TCPXO and GPUDirect-TCPX](https://cloud.google.com/kubernetes-engine/docs/how-to/gpu-bandwidth-gpudirect-tcpx-autopilot) networking for the A3 Mega and A3 High instance types, as well as RoCE networking for the A4 instance type.
-
- !!! info "Backend configuration"
- You may need to configure `extra_vpcs` and `roce_vpcs` in the `gcp` backend configuration.
- Refer to the [GCP](../../examples/clusters/gcp/index.md) examples for more details.
-
-??? info "Nebius"
- When you create a fleet with Nebius, [InfiniBand networking](https://docs.nebius.com/compute/clusters/gpu) is automatically configured if it’s supported for the corresponding instance type.
- Otherwise, instances are only connected by the default VPC subnet.
-
- An InfiniBand fabric for the cluster is selected automatically. If you prefer to use some specific fabrics, configure them in the
- [backend settings](../reference/server/config.yml.md#nebius).
-
-The `cluster` placement is supported for `aws`, `azure`, `gcp`, `nebius`, `oci`, and `vultr`
-backends.
-
-> For more details on optimal inter-node connectivity, read the [Clusters](../guides/clusters.md) guide.
-
-
-
-#### Resources
-
-When you specify a resource value like `cpu` or `memory`,
-you can either use an exact value (e.g. `24GB`) or a
-range (e.g. `24GB..`, or `24GB..80GB`, or `..80GB`).
-
-
-
-```yaml
-type: fleet
-# The name is optional, if not specified, generated randomly
-name: my-fleet
-
-nodes: 2
-
-resources:
- # 200GB or more RAM
- memory: 200GB..
- # 4 GPUs from 40GB to 80GB
- gpu: 40GB..80GB:4
- # Disk size
- disk: 500GB
-```
-
-
-
-The `gpu` property allows specifying not only memory size but also GPU vendor, names
-and their quantity. Examples: `nvidia` (one NVIDIA GPU), `A100` (one A100), `A10G,A100` (either A10G or A100),
-`A100:80GB` (one A100 of 80GB), `A100:2` (two A100), `24GB..40GB:2` (two GPUs between 24GB and 40GB),
-`A100:40GB:2` (two A100 GPUs of 40GB).
-
-??? info "Google Cloud TPU"
- To use TPUs, specify its architecture via the `gpu` property.
-
- ```yaml
- type: fleet
- # The name is optional, if not specified, generated randomly
- name: my-fleet
-
- nodes: 2
-
- resources:
- gpu: v2-8
- ```
-
- Currently, only 8 TPU cores can be specified, supporting single TPU device workloads. Multi-TPU support is coming soon.
-
-> If you’re unsure which offers (hardware configurations) are available from the configured backends, use the
-> [`dstack offer`](../reference/cli/dstack/offer.md#list-gpu-offers) command to list them.
-
-#### Blocks { #backend-blocks }
-
-For backend fleets, `blocks` function the same way as in SSH fleets.
-See the [`Blocks`](#ssh-blocks) section under SSH fleets for details on the blocks concept.
-
-
-
-```yaml
-type: fleet
-
-name: my-fleet
-
-resources:
- gpu: NVIDIA:80GB:8
-
-# Split into 4 blocks, each with 2 GPUs
-blocks: 4
-```
-
-
-
-#### Idle duration
-
-By default, fleet instances stay `idle` for 3 days and can be reused within that time.
-If an instance is not reused within this period, it is automatically terminated.
-
-To change the default idle duration, set
-[`idle_duration`](../reference/dstack.yml/fleet.md#idle_duration) in the fleet configuration (e.g., `0s`, `1m`, or `off` for
-unlimited).
-
-
-
- ```yaml
- type: fleet
- # The name is optional, if not specified, generated randomly
- name: my-fleet
-
- nodes: 2
-
- # Terminate instances idle for more than 1 hour
- idle_duration: 1h
-
- resources:
- gpu: 24GB
- ```
-
-
-
-#### Spot policy
-
-By default, `dstack` uses on-demand instances. However, you can change that
-via the [`spot_policy`](../reference/dstack.yml/fleet.md#spot_policy) property. It accepts `spot`, `on-demand`, and `auto`.
-
-#### Retry policy
-
-By default, if `dstack` fails to provision an instance or an instance is interrupted, no retry is attempted.
-
-If you'd like `dstack` to do it, configure the
-[retry](../reference/dstack.yml/fleet.md#retry) property accordingly:
-
-
-
-```yaml
-type: fleet
-# The name is optional, if not specified, generated randomly
-name: my-fleet
-
-nodes: 1
-
-resources:
- gpu: 24GB
-
-retry:
- # Retry on specific events
- on_events: [no-capacity, interruption]
- # Retry for up to 1 hour
- duration: 1h
-```
-
-
-
-!!! info "Reference"
- Backend fleets support many more configuration options,
- incl. [`backends`](../reference/dstack.yml/fleet.md#backends),
- [`regions`](../reference/dstack.yml/fleet.md#regions),
- [`max_price`](../reference/dstack.yml/fleet.md#max_price), and
- among [others](../reference/dstack.yml/fleet.md).
-
-## SSH fleets
-
-If you have a group of on-prem servers accessible via SSH, you can create an SSH fleet.
-
-### Apply a configuration
-
-Define a fleet configuration as a YAML file in your project directory. The file must have a
-`.dstack.yml` extension (e.g. `.dstack.yml` or `fleet.dstack.yml`).
-
-
-
- ```yaml
- type: fleet
- # The name is optional, if not specified, generated randomly
- name: my-fleet
-
- # Uncomment if instances are interconnected
- #placement: cluster
-
- # SSH credentials for the on-prem servers
- ssh_config:
- user: ubuntu
- identity_file: ~/.ssh/id_rsa
- hosts:
- - 3.255.177.51
- - 3.255.177.52
- ```
-
-
-
-??? info "Requirements"
- 1. Hosts must be pre-installed with Docker.
-
- === "NVIDIA"
- 2. Hosts with NVIDIA GPUs must also be pre-installed with CUDA 12.1 and
- [NVIDIA Container Toolkit](https://docs.nvidia.com/datacenter/cloud-native/container-toolkit/latest/install-guide.html).
-
- === "AMD"
- 2. Hosts with AMD GPUs must also be pre-installed with AMDGPU-DKMS kernel driver (e.g. via
- [native package manager](https://rocm.docs.amd.com/projects/install-on-linux/en/latest/install/native-install/index.html)
- or [AMDGPU installer](https://rocm.docs.amd.com/projects/install-on-linux/en/latest/install/amdgpu-install.html).)
-
- === "Intel Gaudi"
- 2. Hosts with Intel Gaudi accelerators must be pre-installed with [Gaudi software and drivers](https://docs.habana.ai/en/latest/Installation_Guide/Driver_Installation.html#driver-installation).
- This must include the drivers, `hl-smi`, and Habana Container Runtime.
-
- === "Tenstorrent"
- 2. Hosts with Tenstorrent accelerators must be pre-installed with [Tenstorrent software](https://docs.tenstorrent.com/getting-started/README.html#software-installation).
- This must include the drivers, `tt-smi`, and HugePages.
-
- 3. The user specified must have passwordless `sudo` access.
-
- 4. The SSH server must be running and configured with `AllowTcpForwarding yes` in `/etc/ssh/sshd_config`.
-
- 5. The firewall must allow SSH and should forbid any other connections from external networks. For `placement: cluster` fleets, it should also allow any communication between fleet nodes.
-
-To create or update the fleet, pass the fleet configuration to [`dstack apply`](../reference/cli/dstack/apply.md):
-
-
-
-```shell
-$ dstack apply -f examples/misc/fleets/.dstack.yml
-
-Provisioning...
----> 100%
-
- FLEET INSTANCE GPU PRICE STATUS CREATED
- my-fleet 0 L4:24GB (spot) $0 idle 3 mins ago
- 1 L4:24GB (spot) $0 idle 3 mins ago
-```
-
-
-
-When you apply, `dstack` connects to the specified hosts using the provided SSH credentials,
-installs the dependencies, and configures these hosts as a fleet.
-
-Once the status of instances changes to `idle`, they can be used by dev environments, tasks, and services.
-
-### Configuration options
-
-#### Placement { #ssh-placement }
-
-If the hosts are interconnected (i.e. share the same network), set `placement` to `cluster`.
-This is required if you'd like to use the fleet for [distributed tasks](tasks.md#distributed-tasks).
-
-??? info "Network"
- By default, `dstack` automatically detects the network shared by the hosts.
- However, it's possible to configure it explicitly via
- the [`network`](../reference/dstack.yml/fleet.md#network) property.
-
- [//]: # (TODO: Provide an example and more detail)
-
-> For more details on optimal inter-node connectivity, read the [Clusters](../guides/clusters.md) guide.
-
-#### Blocks { #ssh-blocks }
-
-By default, a job uses the entire instance—e.g., all 8 GPUs. To allow multiple jobs on the same instance, set the `blocks` property to divide the instance. Each job can then use one or more blocks, up to the full instance.
-
-
-
- ```yaml
- type: fleet
- name: my-fleet
-
- ssh_config:
- user: ubuntu
- identity_file: ~/.ssh/id_rsa
- hosts:
- - hostname: 3.255.177.51
- blocks: 4
- - hostname: 3.255.177.52
- # As many as possible, according to numbers of GPUs and CPUs
- blocks: auto
- - hostname: 3.255.177.53
- # Do not slice. This is the default value, may be omitted
- blocks: 1
- ```
-
-
-
-All resources (GPU, CPU, memory) are split evenly across blocks, while disk is shared.
-
-For example, with 8 GPUs, 128 CPUs, and 2TB RAM, setting `blocks` to `8` gives each block 1 GPU, 16 CPUs, and 256 GB RAM.
-
-Set `blocks` to `auto` to match the number of blocks to the number of GPUs.
-
-!!! info "Distributed tasks"
- Distributed tasks require exclusive access to all host resources and therefore must use all blocks on each node.
-
-#### Environment variables
-
-If needed, you can specify environment variables that will be used by `dstack-shim` and passed to containers.
-
-[//]: # (TODO: Explain what dstack-shim is)
-
-For example, these variables can be used to configure a proxy:
-
-```yaml
-type: fleet
-name: my-fleet
-
-env:
- - HTTP_PROXY=http://proxy.example.com:80
- - HTTPS_PROXY=http://proxy.example.com:80
- - NO_PROXY=localhost,127.0.0.1
-
-ssh_config:
- user: ubuntu
- identity_file: ~/.ssh/id_rsa
- hosts:
- - 3.255.177.51
- - 3.255.177.52
-```
-
-#### Proxy jump
-
-If fleet hosts are behind a head node (aka "login node"), configure [`proxy_jump`](../reference/dstack.yml/fleet.md#proxy_jump):
-
-
-
-To be able to attach to runs, both explicitly with `dstack attach` and implicitly with `dstack apply`, you must either
-add a front node key (`~/.ssh/head_node_key`) to an SSH agent or configure a key path in `~/.ssh/config`:
-
-
-
-where `Host` must match `ssh_config.proxy_jump.hostname` or `ssh_config.hosts[n].proxy_jump.hostname` if you configure head nodes
-on a per-worker basis.
-
-!!! info "Reference"
- For all SSH fleet configuration options, refer to the [reference](../reference/dstack.yml/fleet.md).
-
-#### Troubleshooting
-
-!!! info "Resources"
- Once the fleet is created, double-check that the GPU, memory, and disk are detected correctly.
-
-If the status does not change to `idle` after a few minutes or the resources are not displayed correctly, ensure that
-all host requirements are satisfied.
-
-If the requirements are met but the fleet still fails to be created correctly, check the logs at
-`/root/.dstack/shim.log` on the hosts for error details.
-
-## Manage fleets
-
-### List fleets
-
-The [`dstack fleet`](../reference/cli/dstack/fleet.md#dstack-fleet-list) command lists fleet instances and their status:
-
-
-
-```shell
-$ dstack fleet
-
- FLEET INSTANCE BACKEND GPU PRICE STATUS CREATED
- my-fleet 0 gcp (europe-west-1) L4:24GB (spot) $0.1624 idle 3 mins ago
- 1 gcp (europe-west-1) L4:24GB (spot) $0.1624 idle 3 mins ago
-```
-
-
-
-### Delete fleets
-
-When a fleet isn't used by a run, you can delete it by passing the fleet configuration to `dstack delete`:
-
-
-
-```shell
-$ dstack delete -f cluster.dstack.yaml
-Delete the fleet my-gcp-fleet? [y/n]: y
-Fleet my-gcp-fleet deleted
-```
-
-
-
-Alternatively, you can delete a fleet by passing the fleet name to `dstack fleet delete`.
-To terminate and delete specific instances from a fleet, pass `-i INSTANCE_NUM`.
-
-!!! info "What's next?"
- 1. Check [dev environments](dev-environments.md), [tasks](tasks.md), and
- [services](services.md)
- 2. Read the [Clusters](../guides/clusters.md) guide
diff --git a/docs/docs/concepts/gateways.md b/docs/docs/concepts/gateways.md
deleted file mode 100644
index 7402bc5762..0000000000
--- a/docs/docs/concepts/gateways.md
+++ /dev/null
@@ -1,162 +0,0 @@
-# Gateways
-
-Gateways manage ingress traffic for running [services](services.md), handle auto-scaling and rate limits, enable HTTPS, and allow you to configure a custom domain. They also support custom routers, such as the [SGLang Model Gateway](https://docs.sglang.ai/advanced_features/router.html#).
-
-
-
-## Apply a configuration
-
-First, define a gateway configuration as a YAML file in your project folder.
-The filename must end with `.dstack.yml` (e.g. `.dstack.yml` or `gateway.dstack.yml` are both acceptable).
-
-
-
-```yaml
-type: gateway
-# A name of the gateway
-name: example-gateway
-
-# Gateways are bound to a specific backend and region
-backend: aws
-region: eu-west-1
-
-# This domain will be used to access the endpoint
-domain: example.com
-```
-
-
-
-A domain name is required to create a gateway.
-
-To create or update the gateway, simply call the [`dstack apply`](../reference/cli/dstack/apply.md) command:
-
-
-
-```shell
-$ dstack apply -f gateway.dstack.yml
-The example-gateway doesn't exist. Create it? [y/n]: y
-
-Provisioning...
----> 100%
-
- BACKEND REGION NAME HOSTNAME DOMAIN DEFAULT STATUS
- aws eu-west-1 example-gateway example.com ✓ submitted
-```
-
-
-
-## Configuration options
-
-### Backend
-
-You can create gateways with the `aws`, `azure`, `gcp`, or `kubernetes` backends, but that does not limit where services run. A gateway can use one backend while services run on any other backend supported by dstack, including backends where gateways themselves cannot be created.
-
-??? info "Kubernetes"
- Gateways in `kubernetes` backend require an external load balancer. Managed Kubernetes solutions usually include a load balancer.
- For self-hosted Kubernetes, you must provide a load balancer by yourself.
-
-### Instance type
-
-By default, `dstack` provisions a small, low-cost instance for the gateway. If you expect to run high-traffic services, you can configure a larger instance type using the `instance_type` property.
-
-
-
-### Router
-
-By default, the gateway uses its own load balancer to route traffic between replicas. However, you can delegate this responsibility to a specific router by setting the `router` property. Currently, the only supported external router is `sglang`.
-
-#### SGLang
-
-The `sglang` router delegates routing logic to the [SGLang Model Gateway](https://docs.sglang.ai/advanced_features/router.html#).
-
-To enable it, set `type` field under `router` to `sglang`:
-
-
-
-!!! info "Policy"
- The `policy` property allows you to configure the routing policy:
-
- * `cache_aware` — Default policy; combines cache locality with load balancing, falling back to shortest queue.
- * `power_of_two` — Samples two workers and picks the lighter one.
- * `random` — Uniform random selection.
- * `round_robin` — Cycles through workers in order.
-
-
-> Currently, services using this type of gateway must run standard SGLang workers. See the [example](../../examples/inference/sglang/index.md).
->
-> Support for prefill/decode disaggregation and auto-scaling based on inter-token latency is coming soon.
-
-### Public IP
-
-If you don't need/want a public IP for the gateway, you can set the `public_ip` to `false` (the default value is `true`), making the gateway private.
-Private gateways are currently supported in `aws` and `gcp` backends.
-
-!!! info "Reference"
- For all gateway configuration options, refer to the [reference](../reference/dstack.yml/gateway.md).
-
-## Update DNS records
-
-Once the gateway is assigned a hostname, go to your domain's DNS settings
-and add a DNS record for `*.`, e.g. `*.example.com`.
-The record should point to the gateway's hostname shown in `dstack`
-and should be of type `A` if the hostname is an IP address (most cases),
-or of type `CNAME` if the hostname is another domain (some private gateways and Kubernetes).
-
-## Manage gateways
-
-### List gateways
-
-The [`dstack gateway list`](../reference/cli/dstack/gateway.md#dstack-gateway-list) command lists existing gateways and their status.
-
-### Delete a gateway
-
-To delete a gateway, pass the gateway configuration to [`dstack delete`](../reference/cli/dstack/delete.md):
-
-
-
-Alternatively, you can delete a gateway by passing the gateway name to `dstack gateway delete`.
-
-[//]: # (TODO: Elaborate on default)
-
-[//]: # (TODO: ## Accessing endpoints)
-
-!!! info "What's next?"
- 1. See [services](services.md) on how to run services
diff --git a/docs/docs/concepts/snippets/manage-fleets.ext b/docs/docs/concepts/snippets/manage-fleets.ext
deleted file mode 100644
index 414aab91ab..0000000000
--- a/docs/docs/concepts/snippets/manage-fleets.ext
+++ /dev/null
@@ -1,25 +0,0 @@
-### Creation policy
-
-By default, when you run `dstack apply` with a dev environment, task, or service,
-if no `idle` instances from the available fleets meet the requirements, `dstack` provisions a new instance
-using configured backends.
-
-To ensure `dstack apply` doesn't provision a new instance but reuses an existing one,
-pass `-R` (or `--reuse`) to `dstack apply`.
-
-
-
-Or, set [`creation_policy`](../reference/dstack.yml/dev-environment.md#creation_policy) to `reuse` in the run configuration.
-
-### Idle duration
-
-If a run provisions a new instance, the instance stays `idle` for 5 minutes by default and can be reused within that time.
-If the instance is not reused within this period, it is automatically terminated.
-To change the default idle duration, set
-[`idle_duration`](../reference/dstack.yml/fleet.md#idle_duration) in the run configuration (e.g., `0s`, `1m`, or `off` for unlimited).
diff --git a/docs/docs/guides/clusters.md b/docs/docs/guides/clusters.md
deleted file mode 100644
index 30bfbee6ea..0000000000
--- a/docs/docs/guides/clusters.md
+++ /dev/null
@@ -1,82 +0,0 @@
-# Clusters
-
-A cluster is a [fleet](../concepts/fleets.md) with its `placement` set to `cluster`. This configuration ensures that the instances within the fleet are interconnected, enabling fast inter-node communication—crucial for tasks such as efficient distributed training.
-
-## Fleets
-
-Ensure a fleet is created before you run any distributed task. This can be either an SSH fleet or a cloud fleet.
-
-### SSH fleets
-
-[SSH fleets](../concepts/fleets.md#ssh-fleets) can be used to create a fleet out of existing baremetals or VMs, e.g. if they are already pre-provisioned, or set up on-premises.
-
-> For SSH fleets, fast interconnect is supported provided that the hosts are pre-configured with the appropriate interconnect drivers.
-
-### Cloud fleets
-
-[Cloud fleets](../concepts/fleets.md#backend-fleets) allow to provision interconnected clusters across supported backends.
-For cloud fleets, fast interconnect is currently supported only on the `aws`, `gcp`, `nebius`, and `runpod` backends.
-
-=== "AWS"
- When you create a cloud fleet with AWS, [Elastic Fabric Adapter](https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/efa.html) networking is automatically configured if it’s supported for the corresponding instance type.
-
- !!! info "Backend configuration"
- Note, EFA requires the `public_ips` to be set to `false` in the `aws` backend configuration.
- Refer to the [AWS](../../examples/clusters/aws/index.md) example for more details.
-
-=== "GCP"
- When you create a cloud fleet with GCP, `dstack` automatically configures [GPUDirect-TCPXO and GPUDirect-TCPX](https://cloud.google.com/kubernetes-engine/docs/how-to/gpu-bandwidth-gpudirect-tcpx-autopilot) networking for the A3 Mega and A3 High instance types, as well as RoCE networking for the A4 instance type.
-
- !!! info "Backend configuration"
- You may need to configure `extra_vpcs` and `roce_vpcs` in the `gcp` backend configuration.
- Refer to the [GCP](../../examples/clusters/gcp/index.md) examples for more details.
-
-=== "Nebius"
- When you create a cloud fleet with Nebius, [InfiniBand](https://docs.nebius.com/compute/clusters/gpu) networking is automatically configured if it’s supported for the corresponding instance type.
-
-=== "Runpod"
- When you run multinode tasks in a cluster cloud fleet with Runpod, `dstack` provisions [Runpod Instant Clusters](https://docs.runpod.io/instant-clusters) with InfiniBand networking configured.
-
-> To request fast interconnect support for other backends,
-file an [issue](https://github.com/dstackai/dstack/issues){:target="_ blank"}.
-
-## Distributed tasks
-
-A distributed task is a task with `nodes` set to a value greater than `2`. In this case, `dstack` first ensures a
-suitable fleet is available, then selects the master node (to obtain its IP) and finally runs jobs on each node.
-
-Within the task's `commands`, it's possible to use `DSTACK_MASTER_NODE_IP`, `DSTACK_NODES_IPS`, `DSTACK_NODE_RANK`, and other
-[system environment variables](../concepts/tasks.md#system-environment-variables) for inter-node communication.
-
-??? info "MPI"
- If want to use MPI, you can set `startup_order` to `workers-first` and `stop_criteria` to `master-done`, and use `DSTACK_MPI_HOSTFILE`.
- See the [NCCL/RCCL tests](../../examples/clusters/nccl-rccl-tests/index.md) examples.
-
-!!! info "Retry policy"
- By default, if any of the nodes fails, `dstack` terminates the entire run. Configure a [retry policy](../concepts/tasks.md#retry-policy) to restart the run if any node fails.
-
-Refer to [distributed tasks](../concepts/tasks.md#distributed-tasks) for an example.
-
-## NCCL/RCCL tests
-
-To test the interconnect of a created fleet, ensure you run [NCCL/RCCL tests](../../examples/clusters/nccl-rccl-tests/index.md) tests using MPI.
-
-## Volumes
-
-### Instance volumes
-
-[Instance volumes](../concepts/volumes.md#instance-volumes) enable mounting any folder from the host into the container, allowing data persistence during distributed tasks.
-
-Instance volumes can be used to mount:
-
-* Regular folders (data persists only while the fleet exists)
-* Folders that are mounts of shared filesystems (e.g., manually mounted shared filesystems).
-
-### Network volumes
-
-Currently, no backend supports multi-attach [network volumes](../concepts/volumes.md#network-volumes) for distributed tasks. However, single-attach volumes can be used by leveraging volume name [interpolation syntax](../concepts/volumes.md#distributed-tasks). This approach mounts a separate single-attach volume to each node.
-
-!!! info "What's next?"
- 1. Read about [distributed tasks](../concepts/tasks.md#distributed-tasks), [fleets](../concepts/fleets.md), and [volumes](../concepts/volumes.md)
- 2. Browse the [Clusters](../../examples.md#clusters) and [Distributed training](../../examples.md#distributed-training) examples
-
diff --git a/docs/docs/guides/dstack-sky.md b/docs/docs/guides/dstack-sky.md
deleted file mode 100644
index e12f1ccef3..0000000000
--- a/docs/docs/guides/dstack-sky.md
+++ /dev/null
@@ -1,44 +0,0 @@
-# dstack Sky
-
-If you don't want to host the `dstack` server or would like to access GPU from the `dstack` marketplace,
-sign up with [dstack Sky](../guides/dstack-sky.md).
-
-### Set up the CLI
-
-If you've signed up, open your project settings, and copy the `dstack project add` command to point the CLI to the project.
-
-{ width=800 }
-
-Then, install the CLI on your machine and use the copied command.
-
-
-
-### Configure clouds
-
-By default, [dstack Sky](https://sky.dstack.ai)
-uses the GPU from its marketplace, which requires a credit card to be attached in your account
-settings.
-
-To use your own cloud accounts, click the settings icon of the corresponding backend and specify credentials:
-
-{ width=800 }
-
-For more details on how to configure your own cloud accounts, check
-the [server/config.yml reference](../reference/server/config.yml.md).
-
-## What's next?
-
-1. Follow [quickstart](../quickstart.md)
-2. Browse [examples](https://dstack.ai/examples)
-3. Join the community via [Discord](https://discord.gg/u8SmfwPpMd)
diff --git a/docs/docs/guides/kubernetes.md b/docs/docs/guides/kubernetes.md
deleted file mode 100644
index 85dc22a80f..0000000000
--- a/docs/docs/guides/kubernetes.md
+++ /dev/null
@@ -1,114 +0,0 @@
-# Kubernetes
-
-The [kubernetes](../concepts/backends.md#kubernetes) backend enables `dstack` to run [dev environments](/docs/concepts/dev-environments), [tasks](/docs/concepts/tasks), and [services](/docs/concepts/services) directly on existing Kubernetes clusters.
-
-If your GPUs are already deployed on Kubernetes and your team relies on its ecosystem and tooling, use this backend to integrate `dstack` with your clusters.
-
-> If Kubernetes is not required, you can run `dstack` on clouds or on-prem clusters without Kubernetes by using [VM-based](../concepts/backends.md#vm-based), [container-based](../concepts/backends.md#container-based), or [on-prem](../concepts/backends.md#on-prem) backends.
-
-## Setting up the backend
-
-To use the `kubernetes` backend with `dstack`, you need to configure it with the path to the kubeconfig file, the IP address of any node in the cluster, and the port that `dstack` will use for proxying SSH traffic.
-This configuration is defined in the `~/.dstack/server/config.yml` file:
-
-
-
-### Proxy jump
-
-To allow the `dstack` server and CLI to access runs via SSH, `dstack` requires a node that acts as a jump host to proxy SSH traffic into containers.
-
-To configure this node, specify `hostname` and `port` under the `proxy_jump` property:
-
-- `hostname` — the IP address of any cluster node selected as the jump host. Both the `dstack` server and CLI must be able to reach it. This node can be either a GPU node or a CPU-only node — it makes no difference.
-- `port` — any accessible port on that node, which `dstack` uses to forward SSH traffic.
-
-No additional setup is required — `dstack` configures and manages the proxy automatically.
-
-### NVIDIA GPU Operator
-
-> For `dstack` to correctly detect GPUs in your Kubernetes cluster, the cluster must have the
-[NVIDIA GPU Operator](https://docs.nvidia.com/datacenter/cloud-native/gpu-operator/latest/index.html) pre-installed.
-
-After the backend is set up, you interact with `dstack` just as you would with other backends or SSH fleets. You can run dev environments, tasks, and services.
-
-## Fleets
-
-### Clusters
-
-If you’d like to run [distributed tasks](../concepts/tasks.md#distributed-tasks) with the `kubernetes` backend, you first need to create a fleet with `placement` set to `cluster`:
-
-
-
- ```yaml
- type: fleet
- # The name is optional; if not specified, one is generated automatically
- name: my-k8s-fleet
-
- # For `kubernetes`, `min` should be set to `0` since it can't pre-provision VMs.
- # Optionally, you can set the maximum number of nodes to limit scaling.
- nodes: 0..
-
- placement: cluster
-
- backends: [kubernetes]
-
- resources:
- # Specify requirements to filter nodes
- gpu: 1..8
- ```
-
-
-
-Then, create the fleet using the `dstack apply` command:
-
-
-
-Once the fleet is created, you can run [distributed tasks](../concepts/tasks.md#distributed-tasks). `dstack` takes care of orchestration automatically.
-
-For more details on clusters, see the [corresponding guide](clusters.md).
-
-> Fleets with `placement` set to `cluster` can be used not only for distributed tasks, but also for dev environments, single-node tasks, and services.
-> Since Kubernetes clusters are interconnected by default, you can always set `placement` to `cluster`.
-
-!!! info "Fleets"
- It’s generally recommended to create [fleets](../concepts/fleets.md) even if you don’t plan to run distributed tasks.
-
-## FAQ
-
-??? info "Is managed Kubernetes with auto-scaling supported?"
- Managed Kubernetes is supported. However, the `kubernetes` backend can only run on pre-provisioned nodes.
- Support for auto-scalable Kubernetes clusters is coming soon—you can track progress in the corresponding [issue](https://github.com/dstackai/dstack/issues/3126).
-
- If on-demand provisioning is important, we recommend using [VM-based](../concepts/backends.md#vm-based) backends as they already support auto-scaling.
-
-??? info "When should I use the Kubernetes backend?"
- Choose the `kubernetes` backend if your GPUs already run on Kubernetes and your team depends on its ecosystem and tooling.
-
- If your priority is orchestrating cloud GPUs and Kubernetes isn’t a must, [VM-based](../concepts/backends.md#vm-based) backends are a better fit thanks to their native cloud integration.
-
- For on-prem GPUs where Kubernetes is optional, [SSH fleets](../concepts/fleets.md#ssh-fleets) provide a simpler and more lightweight alternative.
diff --git a/docs/docs/guides/upgrade.md b/docs/docs/guides/upgrade.md
deleted file mode 100644
index aacf473fd8..0000000000
--- a/docs/docs/guides/upgrade.md
+++ /dev/null
@@ -1,49 +0,0 @@
-# Upgrade guide
-
-
-
-## 0.20.* { #0_20 }
-
-### CLI compatibility
-
-- CLI versions `0.19.*` and earlier remain backward compatible with the `0.20.*` `dstack` server.
-- CLI versions `0.20.` are not compatible with server versions prior to `0.20.*`.
-
-> Do not upgrade the CLI to `0.20.*` until the server has been upgraded.
-
-### Fleets
-
-* Prior to `0.20`, `dstack` automatically provisioned a fleet if one did not exist at run time.
- Beginning with `0.20`, `dstack` will only use existing fleets.
-
-> Create fleets before submitting runs. To enable on-demand instance provisioning, configure `nodes` as a range in the [backend fleet](../concepts/fleets.md#backend-fleets) configuration.
-
-### Working directory
-
-- Previously, when `working_dir` was not specified, `dstack` defaulted to `/workflow`. As of `0.20`, `dstack` uses the working directory defined in the Docker image. If the image does not define a working directory, `dstack` falls back to `/`.
-- The default image introduced in `0.20` uses `/dstack/run` as its default working directory.
-
-> To override the directory defined in the Docker image, specify [`working_dir`](../concepts/dev-environments.md#working-directory) explicitly.
-
-### Repo directory
-
-- Previously, if no [repo directory](../concepts/dev-environments.md#repos) was specified, `dstack` cloned the repository into `/workflow`. With `0.20`, the working directory becomes the default repo directory.
-- In earlier versions, cloning was skipped if the repo directory was non-empty. Starting with `0.20`, this results in a `runner error` unless `if_exists` is set to `skip` in the repo configuration.
-
-> Ensure repo directories are empty, or explicitly set `if_exists` to `skip`.
-
-### Deprecated feature removal
-
-The following deprecated commands have been removed in **0.20**:
-
-- `dstack config`
-- `dstack stats`
-- `dstack gateway create`
-
-Use the corresponding replacements:
-
-- `dstack project`
-- `dstack metrics`
-- `dstack apply`
-
-> For more details on the changes, see the [release notes](https://github.com/dstackai/dstack/releases).
diff --git a/docs/docs/index.md b/docs/docs/index.md
deleted file mode 100644
index b0228fb2c9..0000000000
--- a/docs/docs/index.md
+++ /dev/null
@@ -1,43 +0,0 @@
-# What is dstack?
-
-`dstack` is a unified control plane for GPU provisioning and orchestration that works with any GPU cloud, Kubernetes, or on-prem clusters.
-
-It streamlines development, training, and inference, and is compatible with any hardware, open-source tools, and frameworks.
-
-#### Hardware
-
-`dstack` supports `NVIDIA`, `AMD`, `TPU`, `Intel Gaudi`, and `Tenstorrent` accelerators out of the box.
-
-## How does it work?
-
-
-
-#### 1. Set up the server
-
-> Before using `dstack`, ensure you've [installed](installation/index.md) the server, or signed up for [dstack Sky](https://sky.dstack.ai).
-
-#### 2. Define configurations
-
-`dstack` supports the following configurations:
-
-* [Dev environments](concepts/dev-environments.md) — for interactive development using a desktop IDE
-* [Tasks](concepts/tasks.md) — for scheduling jobs, incl. distributed ones (or running web apps)
-* [Services](concepts/services.md) — for deploying models (or web apps)
-* [Fleets](concepts/fleets.md) — for managing cloud and on-prem clusters
-* [Volumes](concepts/volumes.md) — for managing network volumes (to persist data)
-* [Gateways](concepts/gateways.md) — for publishing services with a custom domain and HTTPS
-
-Configuration can be defined as YAML files within your repo.
-
-#### 3. Apply configurations
-
-Apply the configuration either via the `dstack apply` CLI command (or through a programmatic API.)
-
-`dstack` automatically manages infrastructure provisioning and job scheduling, while also handling auto-scaling,
-port-forwarding, ingress, and more.
-
-!!! info "Where do I start?"
- 1. Proceed to [installation](installation/index.md)
- 2. See [quickstart](quickstart.md)
- 3. Browse [examples](/examples)
- 4. Join [Discord](https://discord.gg/u8SmfwPpMd)
diff --git a/docs/docs/reference/dstack.yml/fleet.md b/docs/docs/reference/dstack.yml/fleet.md
deleted file mode 100644
index b6d0553853..0000000000
--- a/docs/docs/reference/dstack.yml/fleet.md
+++ /dev/null
@@ -1,77 +0,0 @@
-# `fleet`
-
-The `fleet` configuration type allows creating and updating fleets.
-
-## Root reference
-
-#SCHEMA# dstack._internal.core.models.fleets.FleetConfiguration
- overrides:
- show_root_heading: false
- type:
- required: true
-
-### `ssh_config` { data-toc-label="ssh_config" }
-
-#SCHEMA# dstack._internal.core.models.fleets.SSHParams
- overrides:
- show_root_heading: false
- item_id_prefix: ssh_config-
-
-#### `ssh_config.proxy_jump` { #ssh_config-proxy_jump data-toc-label="proxy_jump" }
-
-#SCHEMA# dstack._internal.core.models.fleets.SSHProxyParams
- overrides:
- show_root_heading: false
- item_id_prefix: proxy_jump-
-
-#### `ssh_config.hosts[n]` { #ssh_config-hosts data-toc-label="hosts" }
-
-#SCHEMA# dstack._internal.core.models.fleets.SSHHostParams
- overrides:
- show_root_heading: false
-
-##### `ssh_config.hosts[n].proxy_jump` { #proxy_jump data-toc-label="hosts[n].proxy_jump" }
-
-#SCHEMA# dstack._internal.core.models.fleets.SSHProxyParams
- overrides:
- show_root_heading: false
- item_id_prefix: hosts-proxy_jump-
-
-### `resources`
-
-#SCHEMA# dstack._internal.core.models.resources.ResourcesSpec
- overrides:
- show_root_heading: false
- type:
- required: true
- item_id_prefix: resources-
-
-#### `resources.cpu` { #resources-cpu data-toc-label="cpu" }
-
-#SCHEMA# dstack._internal.core.models.resources.CPUSpec
- overrides:
- show_root_heading: false
- type:
- required: true
-
-#### `resources.gpu` { #resources-gpu data-toc-label="gpu" }
-
-#SCHEMA# dstack._internal.core.models.resources.GPUSpec
- overrides:
- show_root_heading: false
- type:
- required: true
-
-#### `resources.disk` { #resources-disk data-toc-label="disk" }
-
-#SCHEMA# dstack._internal.core.models.resources.DiskSpec
- overrides:
- show_root_heading: false
- type:
- required: true
-
-### `retry`
-
-#SCHEMA# dstack._internal.core.models.profiles.ProfileRetry
- overrides:
- show_root_heading: false
diff --git a/docs/docs/reference/dstack.yml/volume.md b/docs/docs/reference/dstack.yml/volume.md
deleted file mode 100644
index af34a166a1..0000000000
--- a/docs/docs/reference/dstack.yml/volume.md
+++ /dev/null
@@ -1,11 +0,0 @@
-# `volume`
-
-The `volume` configuration type allows creating, registering, and updating [volumes](../../concepts/volumes.md).
-
-## Root reference
-
-#SCHEMA# dstack._internal.core.models.volumes.VolumeConfiguration
- overrides:
- show_root_heading: false
- type:
- required: true
diff --git a/docs/docs/reference/environment-variables.md b/docs/docs/reference/environment-variables.md
deleted file mode 100644
index 4575f1b8f8..0000000000
--- a/docs/docs/reference/environment-variables.md
+++ /dev/null
@@ -1,181 +0,0 @@
-# Environment variables
-
-## .dstack.yml
-
-The following read-only environment variables are automatically propagated to configurations for dev environments,
-tasks, and services:
-
-- `DSTACK_RUN_NAME`{ #DSTACK_RUN_NAME } – The name of the run.
-
- The example below simply prints `vscode` to the output.
-
- ```yaml
- type: task
- name: vscode
-
- commands:
- - echo $DSTACK_RUN_NAME
- ```
-
- If `name` is not set in the configuration, it is assigned a random name (e.g. `wet-mangust-1`).
-
-- `DSTACK_RUN_ID`{ #DSTACK_RUN_ID } – The UUID of the run.
-- `DSTACK_JOB_ID`{ #DSTACK_JOB_ID } – The UUID of the job submission.
-- `DSTACK_REPO_ID`{ #DSTACK_REPO_ID } – The ID of the repo.
-- `DSTACK_GPUS_NUM`{ #DSTACK_GPUS_NUM } – The total number of GPUs in the run.
-
- Example:
-
- ```yaml
- type: service
- name: llama31
-
- env:
- - HF_TOKEN
- commands:
- - pip install vllm
- - vllm serve meta-llama/Meta-Llama-3.1-8B-Instruct
- --max-model-len 4096
- --tensor-parallel-size $DSTACK_GPUS_NUM
- port: 8000
- model: meta-llama/Meta-Llama-3.1-8B-Instruct
-
- resources:
- gpu: 24GB
- ```
-
-- `DSTACK_NODES_NUM`{ #DSTACK_NODES_NUM } – The number of nodes in the run
-- `DSTACK_GPUS_PER_NODE`{ #DSTACK_GPUS_PER_NODE } – The number of GPUs per node
-- `DSTACK_NODE_RANK`{ #DSTACK_NODE_RANK } – The rank of the node
-- `DSTACK_MASTER_NODE_IP`{ #DSTACK_NODE_RANK } – The internal IP address of the master node.
-
- Below is an example of using `DSTACK_NODES_NUM`, `DSTACK_GPUS_PER_NODE`, `DSTACK_NODE_RANK`, and `DSTACK_MASTER_NODE_IP`
- for distributed training:
-
- ```yaml
- type: task
- name: train-distrib
-
- # The size of the cluster
- nodes: 2
-
- python: 3.12
- env:
- - NCCL_DEBUG=INFO
- commands:
- - git clone https://github.com/pytorch/examples.git pytorch-examples
- - cd pytorch-examples/distributed/ddp-tutorial-series
- - uv pip install -r requirements.txt
- - |
- torchrun \
- --nproc-per-node=$DSTACK_GPUS_PER_NODE \
- --node-rank=$DSTACK_NODE_RANK \
- --nnodes=$DSTACK_NODES_NUM \
- --master-addr=$DSTACK_MASTER_NODE_IP \
- --master-port=12345 \
- multinode.py 50 10
-
- resources:
- gpu: 24GB:1..2
- # Uncomment if using multiple GPUs
- #shm_size: 24GB
- ```
-
-- `DSTACK_NODES_IPS`{ #DSTACK_NODES_IPS } – The list of internal IP addresses of all nodes delimited by `"\n"`.
-- `DSTACK_MPI_HOSTFILE`{ #DSTACK_MPI_HOSTFILE } – The path to a pre-populated MPI hostfile that can be used directly as `mpirun --hostfile $DSTACK_MPI_HOSTFILE`.
-
-## Server
-
-The following environment variables are supported by the `dstack` server and can be specified whether the server is run
-via `dstack server` or deployed using Docker.
-
-For more details on the options below, refer to the [server deployment](../guides/server-deployment.md) guide.
-
-- `DSTACK_SERVER_LOG_LEVEL`{ #DSTACK_SERVER_LOG_LEVEL } – Has the same effect as `--log-level`. Defaults to `INFO`.
-
- Example:
-
-
-
-- `DSTACK_SERVER_LOG_FORMAT`{ #DSTACK_SERVER_LOG_FORMAT } – Sets format of log output. Can be `rich`, `standard`, `json`. Defaults to `rich`.
-- `DSTACK_SERVER_HOST`{ #DSTACK_SERVER_HOST } – Has the same effect as `--host`. Defaults to `127.0.0.1`.
-- `DSTACK_SERVER_PORT`{ #DSTACK_SERVER_PORT } – Has the same effect as `--port`. Defaults to `3000`.
-- `DSTACK_SERVER_URL`{ #DSTACK_SERVER_URL } – The URL that the server is running on, e.g. `https://my-server.dstack.ai` Defaults to `http://{DSTACK_SERVER_HOST}:{DSTACK_SERVER_PORT}`.
-- `DSTACK_SERVER_ADMIN_TOKEN`{ #DSTACK_SERVER_ADMIN_TOKEN } – Has the same effect as `--token`. Defaults to `None`.
-- `DSTACK_SERVER_DIR`{ #DSTACK_SERVER_DIR } – Sets path to store data and server configs. Defaults to `~/.dstack/server`.
-- `DSTACK_DATABASE_URL`{ #DSTACK_DATABASE_URL } – The database URL to use instead of default SQLite. Currently `dstack` supports Postgres. Example: `postgresql+asyncpg://myuser:mypassword@localhost:5432/mydatabase`. Defaults to `None`.
-- `DSTACK_SERVER_CLOUDWATCH_LOG_GROUP`{ #DSTACK_SERVER_CLOUDWATCH_LOG_GROUP } – The CloudWatch Logs group for storing workloads logs. If not set, the default file-based log storage is used.
-- `DSTACK_SERVER_CLOUDWATCH_LOG_REGION`{ #DSTACK_SERVER_CLOUDWATCH_LOG_REGION } – The CloudWatch Logs region. Defaults to `None`.
-- `DSTACK_SERVER_GCP_LOGGING_PROJECT`{ #DSTACK_SERVER_GCP_LOGGING_PROJECT } – The GCP Logging project for storing workloads logs. If not set, the default file-based log storage is used.
-- `DSTACK_ENABLE_PROMETHEUS_METRICS`{ #DSTACK_ENABLE_PROMETHEUS_METRICS } — Enables Prometheus metrics collection and export.
-- `DSTACK_DEFAULT_SERVICE_CLIENT_MAX_BODY_SIZE`{ #DSTACK_DEFAULT_SERVICE_CLIENT_MAX_BODY_SIZE } – Request body size limit for services running with a gateway, in bytes. Defaults to 64 MiB.
-- `DSTACK_SERVICE_CLIENT_TIMEOUT`{ #DSTACK_SERVICE_CLIENT_TIMEOUT } – Timeout in seconds for HTTP requests sent from the in-server proxy and gateways to service replicas. Defaults to 60.
-- `DSTACK_FORBID_SERVICES_WITHOUT_GATEWAY`{ #DSTACK_FORBID_SERVICES_WITHOUT_GATEWAY } – Forbids registering new services without a gateway if set to any value.
-- `DSTACK_SERVER_CODE_UPLOAD_LIMIT`{ #DSTACK_SERVER_CODE_UPLOAD_LIMIT } - The repo size limit when uploading diffs or local repos, in bytes. Set to `0` to disable size limits. Defaults to `2MiB`.
-- `DSTACK_SERVER_S3_BUCKET`{ #DSTACK_SERVER_S3_BUCKET } - The bucket that repo diffs will be uploaded to if set. If unset, diffs are uploaded to the database.
-- `DSTACK_SERVER_S3_BUCKET_REGION`{ #DSTACK_SERVER_S3_BUCKET_REGION } - The region of the S3 Bucket.
-- `DSTACK_SERVER_GCS_BUCKET`{ #DSTACK_SERVER_GCS_BUCKET } - The bucket that repo diffs will be uploaded to if set. If unset, diffs are uploaded to the database.
-- `DSTACK_DB_POOL_SIZE`{ #DSTACK_DB_POOL_SIZE } - The client DB connections pool size. Defaults to `20`,
-- `DSTACK_DB_MAX_OVERFLOW`{ #DSTACK_DB_MAX_OVERFLOW } - The client DB connections pool allowed overflow. Defaults to `20`.
-- `DSTACK_SERVER_BACKGROUND_PROCESSING_FACTOR`{ #DSTACK_SERVER_BACKGROUND_PROCESSING_FACTOR } - The number of background jobs for processing server resources. Increase if you need to process more resources per server replica quickly. Defaults to `1`.
-- `DSTACK_SERVER_BACKGROUND_PROCESSING_DISABLED`{ #DSTACK_SERVER_BACKGROUND_PROCESSING_DISABLED } - Disables background processing if set to any value. Useful to run only web frontend and API server.
-- `DSTACK_SERVER_MAX_PROBES_PER_JOB`{ #DSTACK_SERVER_MAX_PROBES_PER_JOB } - Maximum number of probes allowed in a run configuration. Validated at apply time.
-- `DSTACK_SERVER_MAX_PROBE_TIMEOUT`{ #DSTACK_SERVER_MAX_PROBE_TIMEOUT } - Maximum allowed timeout for a probe. Validated at apply time.
-- `DSTACK_SERVER_METRICS_RUNNING_TTL_SECONDS`{ #DSTACK_SERVER_METRICS_RUNNING_TTL_SECONDS } – Maximum age of metrics samples for running jobs.
-- `DSTACK_SERVER_METRICS_FINISHED_TTL_SECONDS`{ #DSTACK_SERVER_METRICS_FINISHED_TTL_SECONDS } – Maximum age of metrics samples for finished jobs.
-- `DSTACK_SERVER_INSTANCE_HEALTH_TTL_SECONDS`{ #DSTACK_SERVER_INSTANCE_HEALTH_TTL_SECONDS } – Maximum age of instance health checks.
-- `DSTACK_SERVER_INSTANCE_HEALTH_MIN_COLLECT_INTERVAL_SECONDS`{ #DSTACK_SERVER_INSTANCE_HEALTH_MIN_COLLECT_INTERVAL_SECONDS } – Minimum time interval between consecutive health checks of the same instance.
-- `DSTACK_SERVER_EVENTS_TTL_SECONDS`{ #DSTACK_SERVER_EVENTS_TTL_SECONDS } - Maximum age of event records. Set to `0` to disable event storage. Defaults to 30 days.
-
-??? info "Internal environment variables"
- The following environment variables are intended for development purposes:
-
- * `DSTACK_SERVER_ROOT_LOG_LEVEL` – Sets root logger log level. Defaults to `ERROR`.
- * `DSTACK_SERVER_UVICORN_LOG_LEVEL` – Sets uvicorn logger log level. Defaults to `ERROR`.
- * `DSTACK_SERVER_MAX_OFFERS_TRIED` - Sets how many instance offers to try when starting a job.
- Setting a high value can degrade server performance.
- * `DSTACK_RUNNER_VERSION` – Sets exact runner version for debug. Defaults to `latest`. Ignored if `DSTACK_RUNNER_DOWNLOAD_URL` is set.
- * `DSTACK_RUNNER_DOWNLOAD_URL` – Overrides `dstack-runner` binary download URL. The URL can contain `{version}` and/or `{arch}` placeholders,
- where `{version}` is `dstack` version in the `X.Y.Z` format or `latest`, and `{arch}` is either `amd64` or `arm64`, for example,
- `https://dstack.example.com/{arch}/{version}/dstack-runner`.
- * `DSTACK_SHIM_DOWNLOAD_URL` – Overrides `dstack-shim` binary download URL. The URL can contain `{version}` and/or `{arch}` placeholders,
- see `DSTACK_RUNNER_DOWNLOAD_URL` for the details.
- * `DSTACK_DEFAULT_CREDS_DISABLED` – Disables default credentials detection if set. Defaults to `None`.
- * `DSTACK_LOCAL_BACKEND_ENABLED` – Enables local backend for debug if set. Defaults to `None`.
-
-## CLI
-
-The following environment variables are supported by the CLI.
-
-- `DSTACK_CLI_LOG_LEVEL`{ #DSTACK_CLI_LOG_LEVEL } – Sets the logging level for CLI output to stdout. Defaults to `INFO`.
-
-Example:
-
-
-
-- `DSTACK_PROJECT`{ #DSTACK_PROJECT } – Has the same effect as `--project`. Defaults to `None`.
diff --git a/docs/examples/single-node-training/axolotl/index.md b/docs/examples/single-node-training/axolotl/index.md
deleted file mode 100644
index e69de29bb2..0000000000
diff --git a/docs/examples/single-node-training/trl/index.md b/docs/examples/single-node-training/trl/index.md
deleted file mode 100644
index e69de29bb2..0000000000
diff --git a/docs/index.md b/docs/index.md
deleted file mode 100644
index 53b5aaa461..0000000000
--- a/docs/index.md
+++ /dev/null
@@ -1,8 +0,0 @@
----
-template: home.html
-title: AI container orchestration for AI teams
-hide:
- - navigation
- - toc
- - footer
----
diff --git a/docs/overrides/assets/images/quotes/cudopete.png b/docs/overrides/assets/images/quotes/cudopete.png
deleted file mode 100644
index dd447d0f3d..0000000000
Binary files a/docs/overrides/assets/images/quotes/cudopete.png and /dev/null differ
diff --git a/docs/overrides/assets/images/quotes/spott.jpg b/docs/overrides/assets/images/quotes/spott.jpg
deleted file mode 100644
index cc9e0ae625..0000000000
Binary files a/docs/overrides/assets/images/quotes/spott.jpg and /dev/null differ
diff --git a/docs/overrides/header-2.html b/docs/overrides/header-2.html
deleted file mode 100644
index dbcb7ad9ae..0000000000
--- a/docs/overrides/header-2.html
+++ /dev/null
@@ -1,73 +0,0 @@
-{#-
- This file was automatically generated - do not edit
--#}
-{% set class = "md-header" %}
-{% if "navigation.tabs.sticky" in features %}
- {% set class = class ~ " md-header--shadow md-header--lifted" %}
-{% elif "navigation.tabs" not in features %}
- {% set class = class ~ " md-header--shadow" %}
-{% endif %}
-
-
- {% if "navigation.tabs.sticky" in features %}
- {% if "navigation.tabs" in features %}
- {% include "partials/tabs.html" %}
- {% endif %}
- {% endif %}
-
diff --git a/docs/overrides/home.html b/docs/overrides/home.html
deleted file mode 100644
index ced53fb1e8..0000000000
--- a/docs/overrides/home.html
+++ /dev/null
@@ -1,664 +0,0 @@
-{% extends "landing.html" %}
-
-{% block scripts %}
-{{ super() }}
-
-
-
-
-{% endblock %}
-
-{% block content %}
-
-
-
-
-
The orchestration layer for modern ML teams
-
-
- dstack provides ML teams with a unified control plane for GPU provisioning and orchestration
- across cloud, Kubernetes, and on-prem. It streamlines development, training, and inference — reducing costs 3–7x and
- preventing lock-in.
-
- One control plane for GPUs across cloud, Kubernetes, and on-prem.
-
-
-
-
-
-
-
An open platform for GPU orchestration
-
- Managing AI infrastructure requires efficient GPU orchestration, whether workloads run
- on a single GPU cloud, across multiple GPU providers, or on-prem clusters.
-
-
-
- dstack provides an open stack for GPU orchestration that streamlines development, training,
- and inference, and can be used with any hardware, open-source tools, and frameworks.
-
- dstack natively integrates with top GPU clouds—automating cluster provisioning and
- workload orchestration to maximize efficiency and minimize overhead.
-
-
-
- It can provision and manage VM clusters through native integrations or via Kubernetes.
-
- For provisioned Kubernetes clusters, connect them to dstack using the Kubernetes backend.
- If you run vanilla bare-metal servers or VMs without Kubernetes, use SSH fleets
- instead.
-
- Move from single-instance experiments to multi-node distributed training without friction. dstack lets you define complex jobs with a simple configuration,
- handling the scheduling and orchestration for you.
-
-
-
This allows your team to focus on research while ensuring that expensive cluster resources are utilized efficiently.
- With dstack, you can easily deploy any model as a secure,
- auto-scaling OpenAI-compatible endpoint, all while using your custom code, Docker image, and
- serving framework.
-
- With dstack, AI researchers at EA can spin up and scale experiments without touching
- infrastructure. It supports everything from quick prototyping to multi-node training on any cloud.
-
-
-
-
-
-
-
-
Aleksandr Movchan
-
-
ML Engineer @Mobius Labs
-
-
- Thanks to dstack, my team can quickly tap into affordable
- GPUs and streamline our workflows
- from testing and development to full-scale application deployment.
-
-
-
-
-
-
-
-
Alvaro Bartolome
-
-
ML Engineer @Argilla
-
-
- With dstack it's incredibly easy to define a configuration
- within a
- repository
- and run it without worrying about GPU availability. It lets you focus on
- data and your research.
-
-
-
-
-
-
-
-
Park Chansung
-
-
ML Researcher @ETRI
-
-
- Thanks to dstack, I can effortlessly access the top GPU
- options across
- different clouds,
- saving me time and money while pushing my AI work forward.
-
-
-
-
-
-
-
-
Eckart Burgwedel
-
-
CEO @Uberchord
-
-
- With dstack, running LLMs on a cloud GPU is as
- easy as running a local Docker container.
- It combines the ease of Docker with the auto-scaling capabilities of K8S.
-
-
-
-
-
-
-
-
Peter Hill
-
-
Co-Founder @CUDO Compute
-
-
- dstack simplifies infrastructure provisioning and AI
- development.
- If your team is on the lookout for an AI platform, I
- wholeheartedly recommend dstack.
-
-
-
-
-
-
-
-
-
FAQ
-
-
-
-
-
- How does dstack differ from Slurm?
-
-
-
-
-
-
- Slurm is a battle-tested system with decades of production use in HPC environments.
- dstack by contrast, is built for modern ML/AI workloads with cloud-native provisioning and a container-first architecture.
- While both support distributed training and batch jobs, dstack
- also natively supports development and production-grade inference.
-
- Kubernetes is a general-purpose container orchestrator. dstack also
- orchestrates containers, but it provides a lightweight and streamlined interface that is purpose
- built for ML.
-
-
-
- You declare
- dev environments,
- tasks,
- services, and
- fleets
- with simple configuration. dstack provisions GPUs, manages clusters via fleets with fine-grained
- controls, and optimizes cost and utilization, while keeping a simple UI and CLI.
-
-
-
- If you already use Kubernetes, you can run dstack on it via the Kubernetes backend.
-
-
-
-
-
-
- Can I use dstack with Kubernetes?
-
-
-
-
-
-
- Yes. You can connect existing Kubernetes clusters using the Kubernetes backend and run
- dev environments,
- tasks, and
- services on it.
- Choose the Kubernetes backend if your GPUs already run on Kubernetes and your team depends on its
- ecosystem and tooling.
- See the
- Kubernetes guide for setup and best practices.
-
-
- If your priority is orchestrating cloud GPUs and Kubernetes isn’t a must, VM-based backends are a better fit
- thanks to their native cloud integration.
- For on-prem GPUs where Kubernetes is optional, SSH fleets provide a simpler and more lightweight alternative.
-
-
-
-
-
-
- When should I use dstack?
-
-
-
-
-
-
- dstack accelerates ML development with a simple, ML‑native interface.
- Spin up dev environments, run
- single‑node or distributed tasks, and deploy services without infrastructure overhead.
-
-
-
- It radically reduces GPU costs via smart orchestration and fine‑grained fleet controls, including efficient reuse,
- right‑sizing, and support for spot, on‑demand, and reserved capacity.
-
-
-
- It is 100% interoperable with your stack and works with any open‑source frameworks and tools, as
- well as your own Docker images and code, across cloud, Kubernetes, and on‑prem GPUs.
-
 +
 +
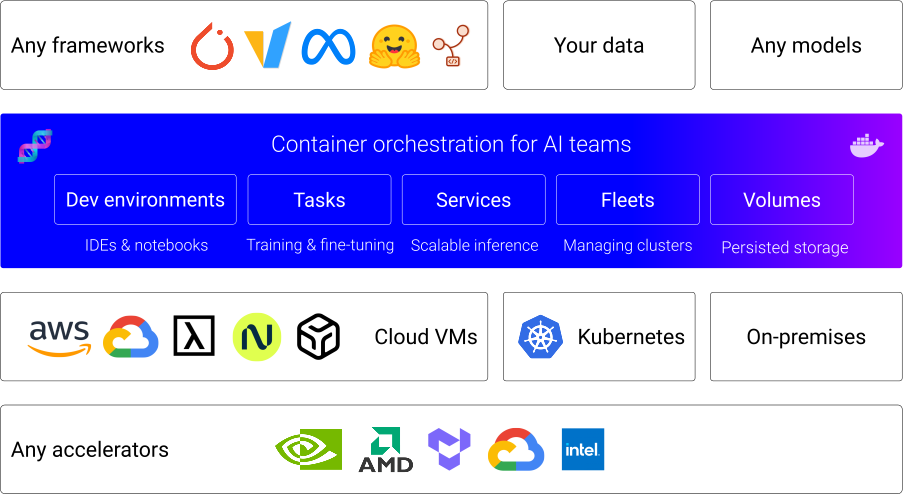 -
-#### 1. Set up the server
-
-> Before using `dstack`, ensure you've [installed](installation/index.md) the server, or signed up for [dstack Sky](https://sky.dstack.ai).
-
-#### 2. Define configurations
-
-`dstack` supports the following configurations:
-
-* [Dev environments](concepts/dev-environments.md) — for interactive development using a desktop IDE
-* [Tasks](concepts/tasks.md) — for scheduling jobs, incl. distributed ones (or running web apps)
-* [Services](concepts/services.md) — for deploying models (or web apps)
-* [Fleets](concepts/fleets.md) — for managing cloud and on-prem clusters
-* [Volumes](concepts/volumes.md) — for managing network volumes (to persist data)
-* [Gateways](concepts/gateways.md) — for publishing services with a custom domain and HTTPS
-
-Configuration can be defined as YAML files within your repo.
-
-#### 3. Apply configurations
-
-Apply the configuration either via the `dstack apply` CLI command (or through a programmatic API.)
-
-`dstack` automatically manages infrastructure provisioning and job scheduling, while also handling auto-scaling,
-port-forwarding, ingress, and more.
-
-!!! info "Where do I start?"
- 1. Proceed to [installation](installation/index.md)
- 2. See [quickstart](quickstart.md)
- 3. Browse [examples](/examples)
- 4. Join [Discord](https://discord.gg/u8SmfwPpMd)
diff --git a/docs/docs/reference/dstack.yml/fleet.md b/docs/docs/reference/dstack.yml/fleet.md
deleted file mode 100644
index b6d0553853..0000000000
--- a/docs/docs/reference/dstack.yml/fleet.md
+++ /dev/null
@@ -1,77 +0,0 @@
-# `fleet`
-
-The `fleet` configuration type allows creating and updating fleets.
-
-## Root reference
-
-#SCHEMA# dstack._internal.core.models.fleets.FleetConfiguration
- overrides:
- show_root_heading: false
- type:
- required: true
-
-### `ssh_config` { data-toc-label="ssh_config" }
-
-#SCHEMA# dstack._internal.core.models.fleets.SSHParams
- overrides:
- show_root_heading: false
- item_id_prefix: ssh_config-
-
-#### `ssh_config.proxy_jump` { #ssh_config-proxy_jump data-toc-label="proxy_jump" }
-
-#SCHEMA# dstack._internal.core.models.fleets.SSHProxyParams
- overrides:
- show_root_heading: false
- item_id_prefix: proxy_jump-
-
-#### `ssh_config.hosts[n]` { #ssh_config-hosts data-toc-label="hosts" }
-
-#SCHEMA# dstack._internal.core.models.fleets.SSHHostParams
- overrides:
- show_root_heading: false
-
-##### `ssh_config.hosts[n].proxy_jump` { #proxy_jump data-toc-label="hosts[n].proxy_jump" }
-
-#SCHEMA# dstack._internal.core.models.fleets.SSHProxyParams
- overrides:
- show_root_heading: false
- item_id_prefix: hosts-proxy_jump-
-
-### `resources`
-
-#SCHEMA# dstack._internal.core.models.resources.ResourcesSpec
- overrides:
- show_root_heading: false
- type:
- required: true
- item_id_prefix: resources-
-
-#### `resources.cpu` { #resources-cpu data-toc-label="cpu" }
-
-#SCHEMA# dstack._internal.core.models.resources.CPUSpec
- overrides:
- show_root_heading: false
- type:
- required: true
-
-#### `resources.gpu` { #resources-gpu data-toc-label="gpu" }
-
-#SCHEMA# dstack._internal.core.models.resources.GPUSpec
- overrides:
- show_root_heading: false
- type:
- required: true
-
-#### `resources.disk` { #resources-disk data-toc-label="disk" }
-
-#SCHEMA# dstack._internal.core.models.resources.DiskSpec
- overrides:
- show_root_heading: false
- type:
- required: true
-
-### `retry`
-
-#SCHEMA# dstack._internal.core.models.profiles.ProfileRetry
- overrides:
- show_root_heading: false
diff --git a/docs/docs/reference/dstack.yml/volume.md b/docs/docs/reference/dstack.yml/volume.md
deleted file mode 100644
index af34a166a1..0000000000
--- a/docs/docs/reference/dstack.yml/volume.md
+++ /dev/null
@@ -1,11 +0,0 @@
-# `volume`
-
-The `volume` configuration type allows creating, registering, and updating [volumes](../../concepts/volumes.md).
-
-## Root reference
-
-#SCHEMA# dstack._internal.core.models.volumes.VolumeConfiguration
- overrides:
- show_root_heading: false
- type:
- required: true
diff --git a/docs/docs/reference/environment-variables.md b/docs/docs/reference/environment-variables.md
deleted file mode 100644
index 4575f1b8f8..0000000000
--- a/docs/docs/reference/environment-variables.md
+++ /dev/null
@@ -1,181 +0,0 @@
-# Environment variables
-
-## .dstack.yml
-
-The following read-only environment variables are automatically propagated to configurations for dev environments,
-tasks, and services:
-
-- `DSTACK_RUN_NAME`{ #DSTACK_RUN_NAME } – The name of the run.
-
- The example below simply prints `vscode` to the output.
-
- ```yaml
- type: task
- name: vscode
-
- commands:
- - echo $DSTACK_RUN_NAME
- ```
-
- If `name` is not set in the configuration, it is assigned a random name (e.g. `wet-mangust-1`).
-
-- `DSTACK_RUN_ID`{ #DSTACK_RUN_ID } – The UUID of the run.
-- `DSTACK_JOB_ID`{ #DSTACK_JOB_ID } – The UUID of the job submission.
-- `DSTACK_REPO_ID`{ #DSTACK_REPO_ID } – The ID of the repo.
-- `DSTACK_GPUS_NUM`{ #DSTACK_GPUS_NUM } – The total number of GPUs in the run.
-
- Example:
-
- ```yaml
- type: service
- name: llama31
-
- env:
- - HF_TOKEN
- commands:
- - pip install vllm
- - vllm serve meta-llama/Meta-Llama-3.1-8B-Instruct
- --max-model-len 4096
- --tensor-parallel-size $DSTACK_GPUS_NUM
- port: 8000
- model: meta-llama/Meta-Llama-3.1-8B-Instruct
-
- resources:
- gpu: 24GB
- ```
-
-- `DSTACK_NODES_NUM`{ #DSTACK_NODES_NUM } – The number of nodes in the run
-- `DSTACK_GPUS_PER_NODE`{ #DSTACK_GPUS_PER_NODE } – The number of GPUs per node
-- `DSTACK_NODE_RANK`{ #DSTACK_NODE_RANK } – The rank of the node
-- `DSTACK_MASTER_NODE_IP`{ #DSTACK_NODE_RANK } – The internal IP address of the master node.
-
- Below is an example of using `DSTACK_NODES_NUM`, `DSTACK_GPUS_PER_NODE`, `DSTACK_NODE_RANK`, and `DSTACK_MASTER_NODE_IP`
- for distributed training:
-
- ```yaml
- type: task
- name: train-distrib
-
- # The size of the cluster
- nodes: 2
-
- python: 3.12
- env:
- - NCCL_DEBUG=INFO
- commands:
- - git clone https://github.com/pytorch/examples.git pytorch-examples
- - cd pytorch-examples/distributed/ddp-tutorial-series
- - uv pip install -r requirements.txt
- - |
- torchrun \
- --nproc-per-node=$DSTACK_GPUS_PER_NODE \
- --node-rank=$DSTACK_NODE_RANK \
- --nnodes=$DSTACK_NODES_NUM \
- --master-addr=$DSTACK_MASTER_NODE_IP \
- --master-port=12345 \
- multinode.py 50 10
-
- resources:
- gpu: 24GB:1..2
- # Uncomment if using multiple GPUs
- #shm_size: 24GB
- ```
-
-- `DSTACK_NODES_IPS`{ #DSTACK_NODES_IPS } – The list of internal IP addresses of all nodes delimited by `"\n"`.
-- `DSTACK_MPI_HOSTFILE`{ #DSTACK_MPI_HOSTFILE } – The path to a pre-populated MPI hostfile that can be used directly as `mpirun --hostfile $DSTACK_MPI_HOSTFILE`.
-
-## Server
-
-The following environment variables are supported by the `dstack` server and can be specified whether the server is run
-via `dstack server` or deployed using Docker.
-
-For more details on the options below, refer to the [server deployment](../guides/server-deployment.md) guide.
-
-- `DSTACK_SERVER_LOG_LEVEL`{ #DSTACK_SERVER_LOG_LEVEL } – Has the same effect as `--log-level`. Defaults to `INFO`.
-
- Example:
-
-
 -
 -
 -
 -
 -
 -
 -
 -
 -
 -
 -
 -
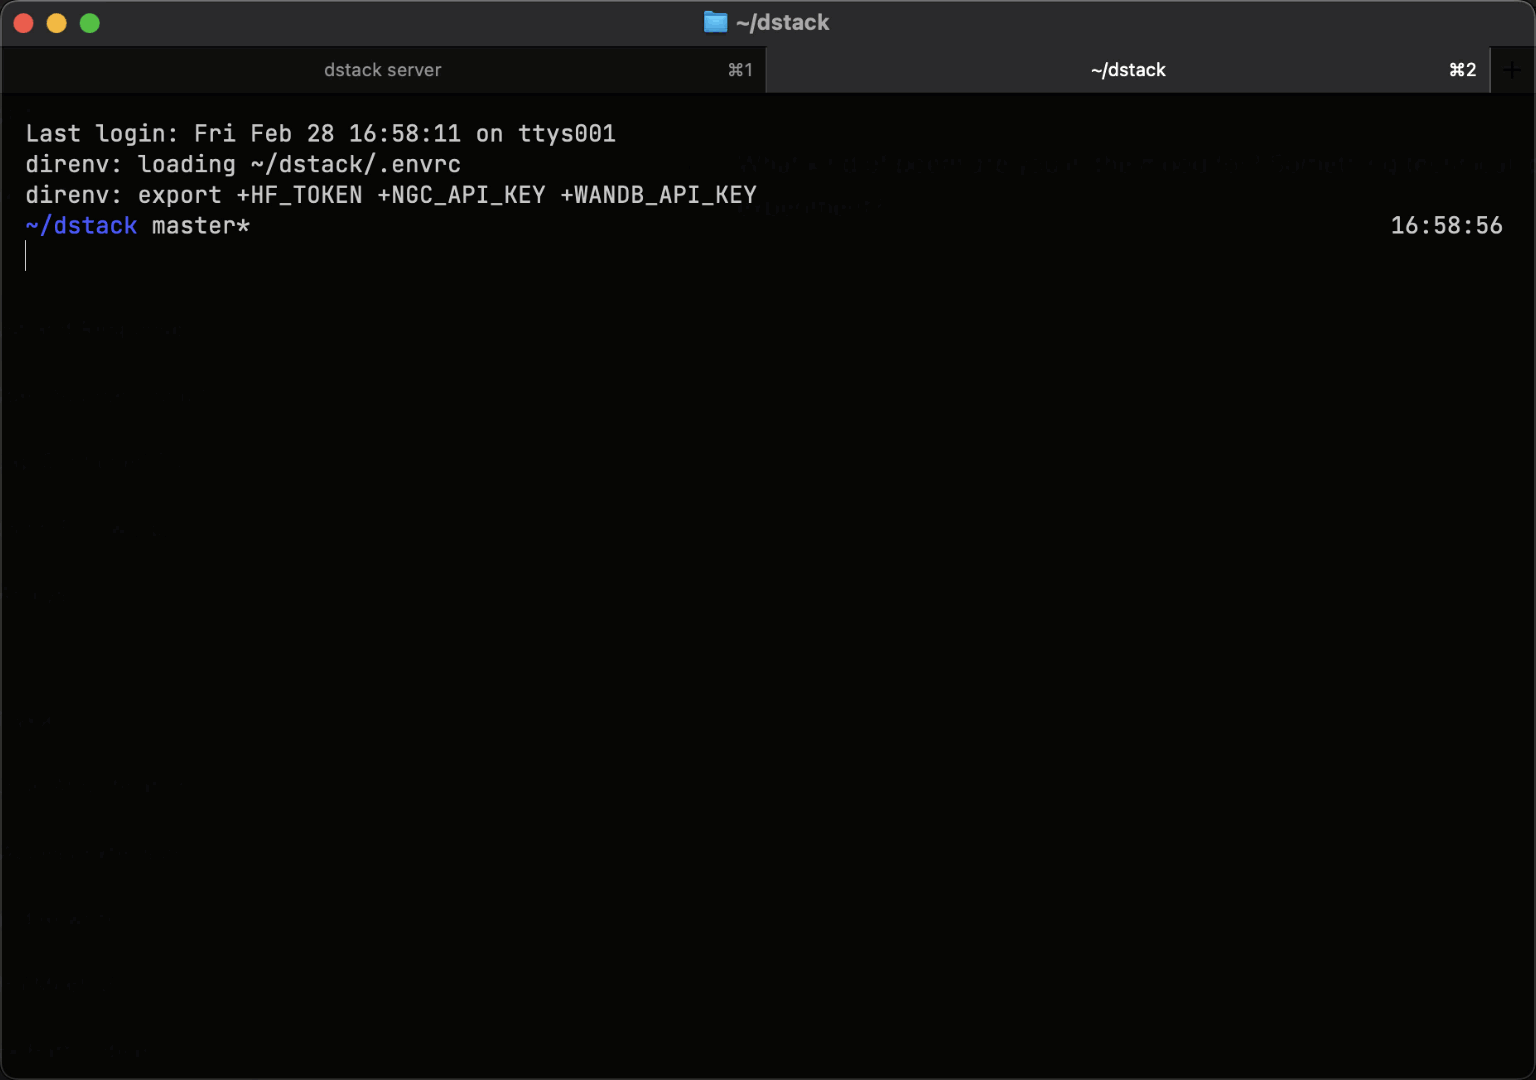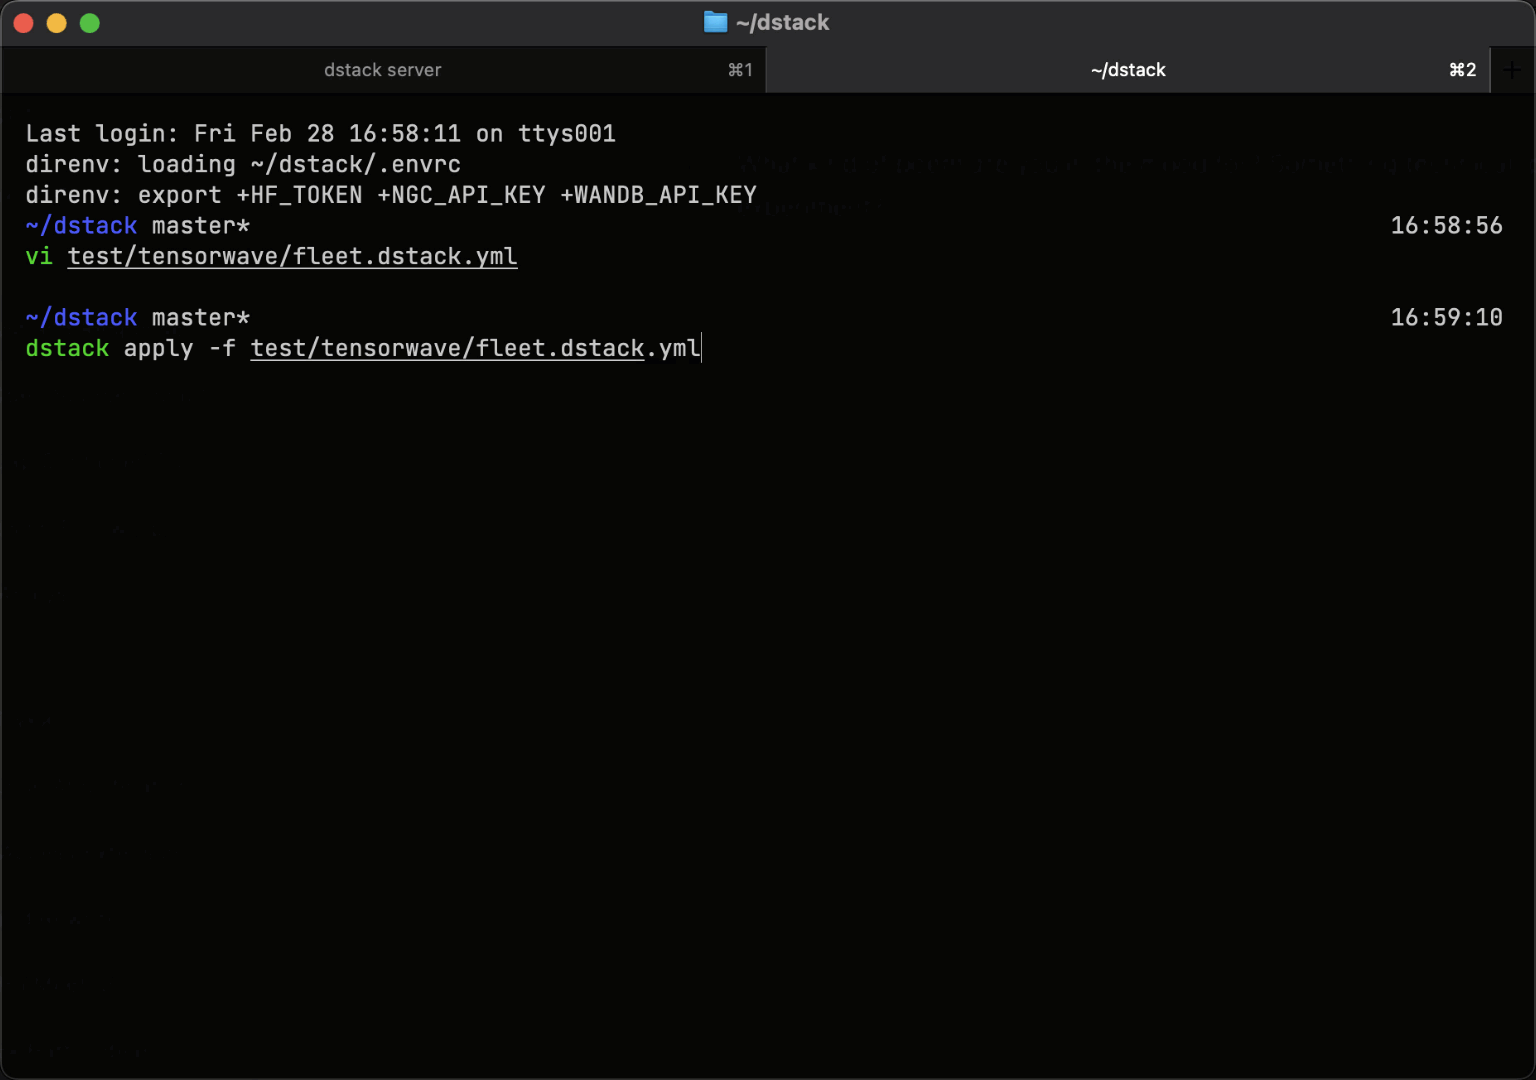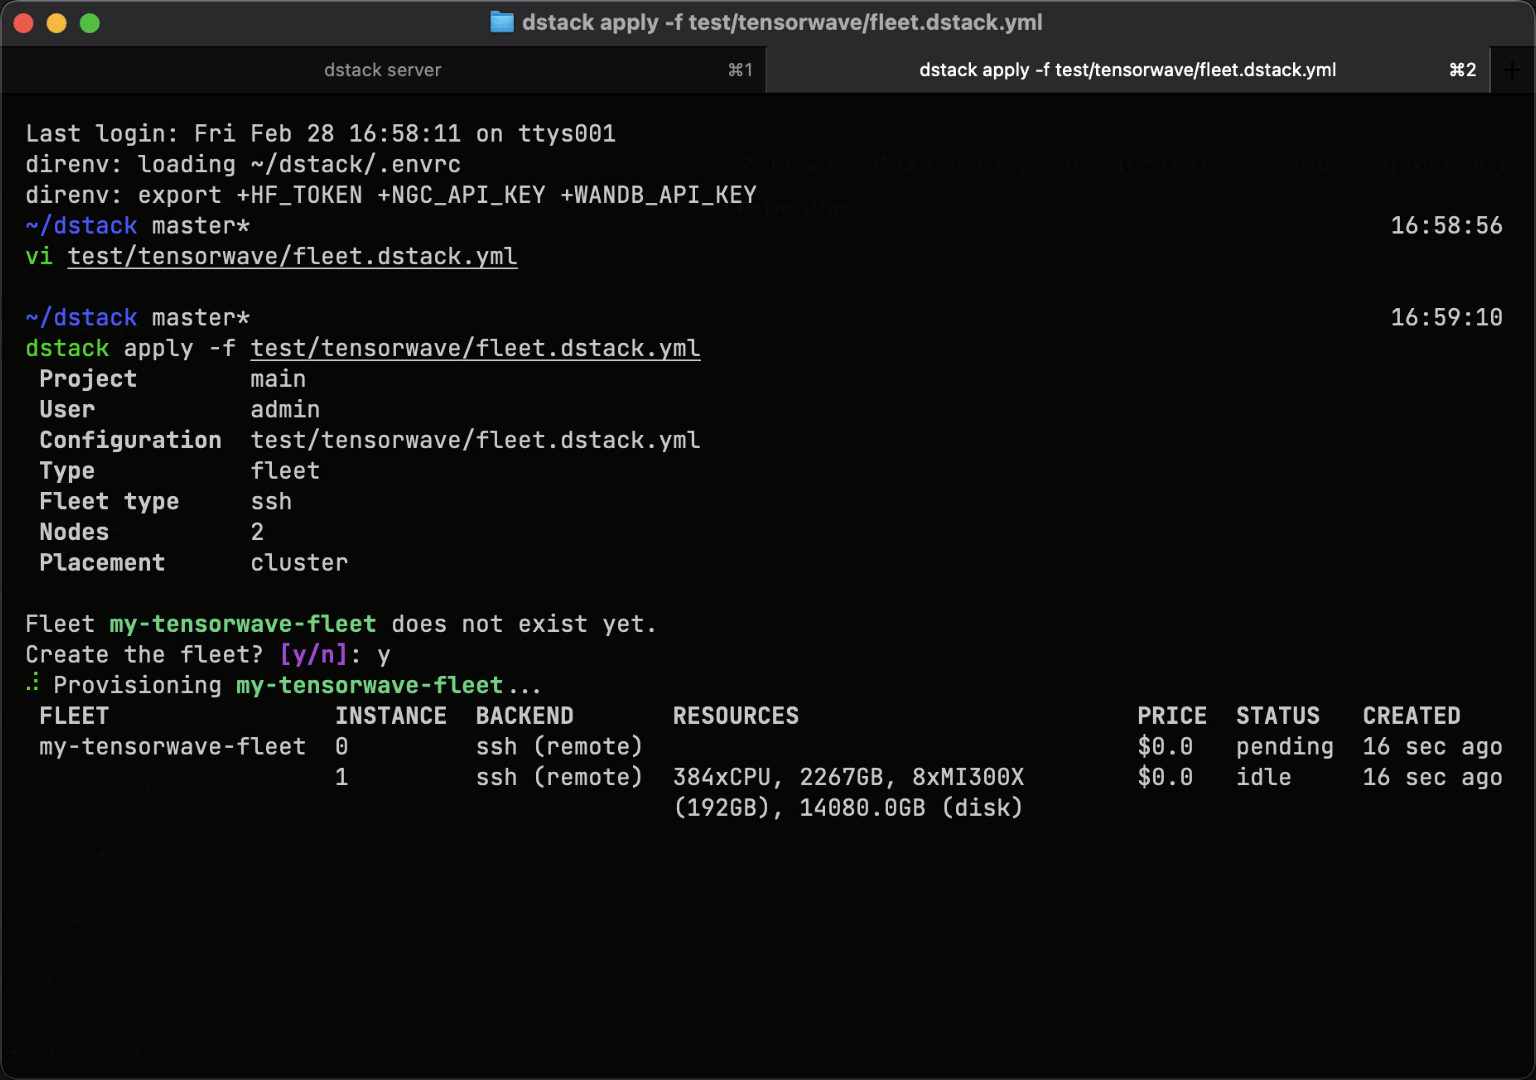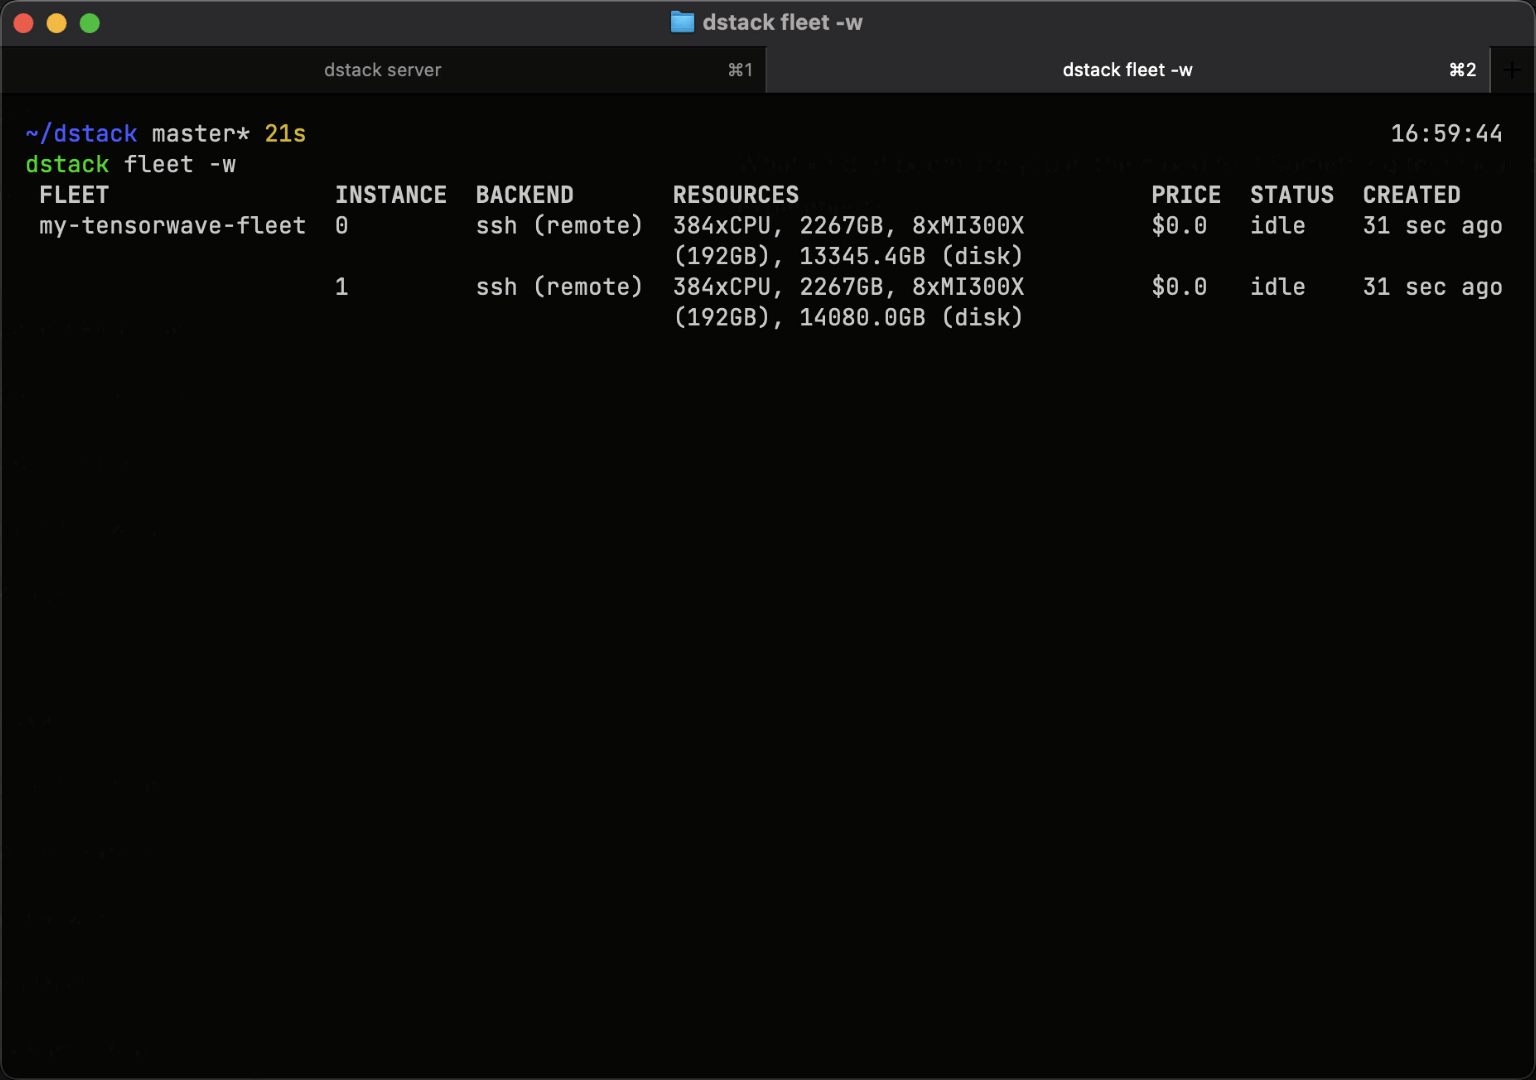 -
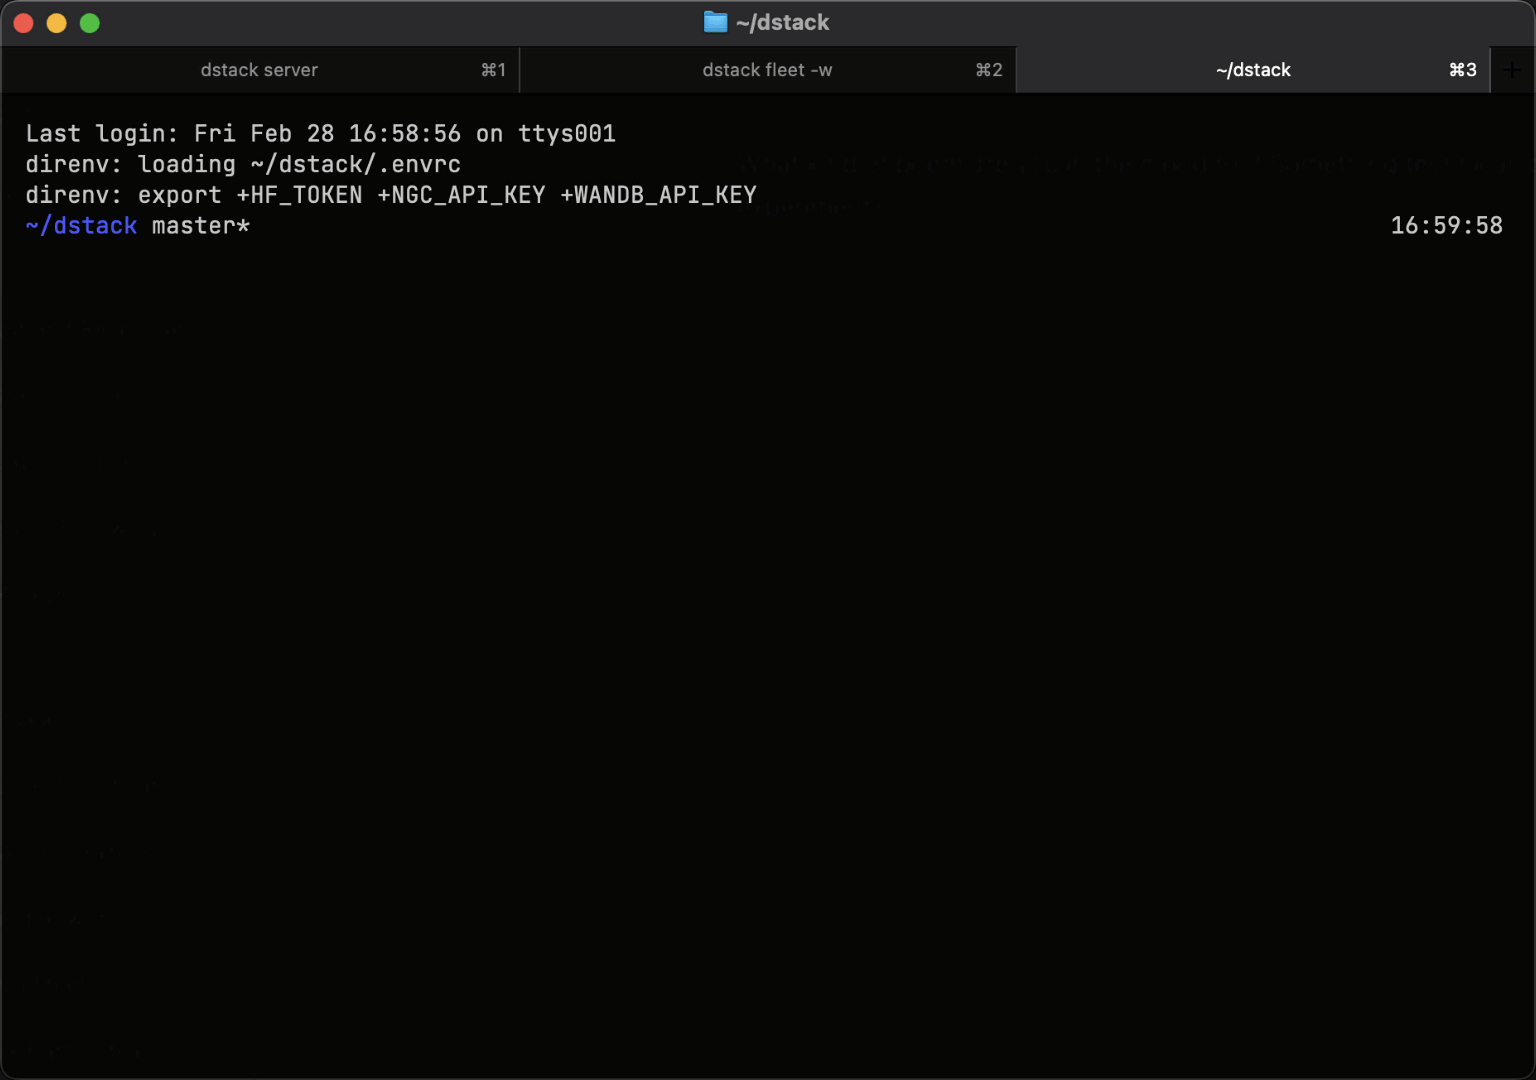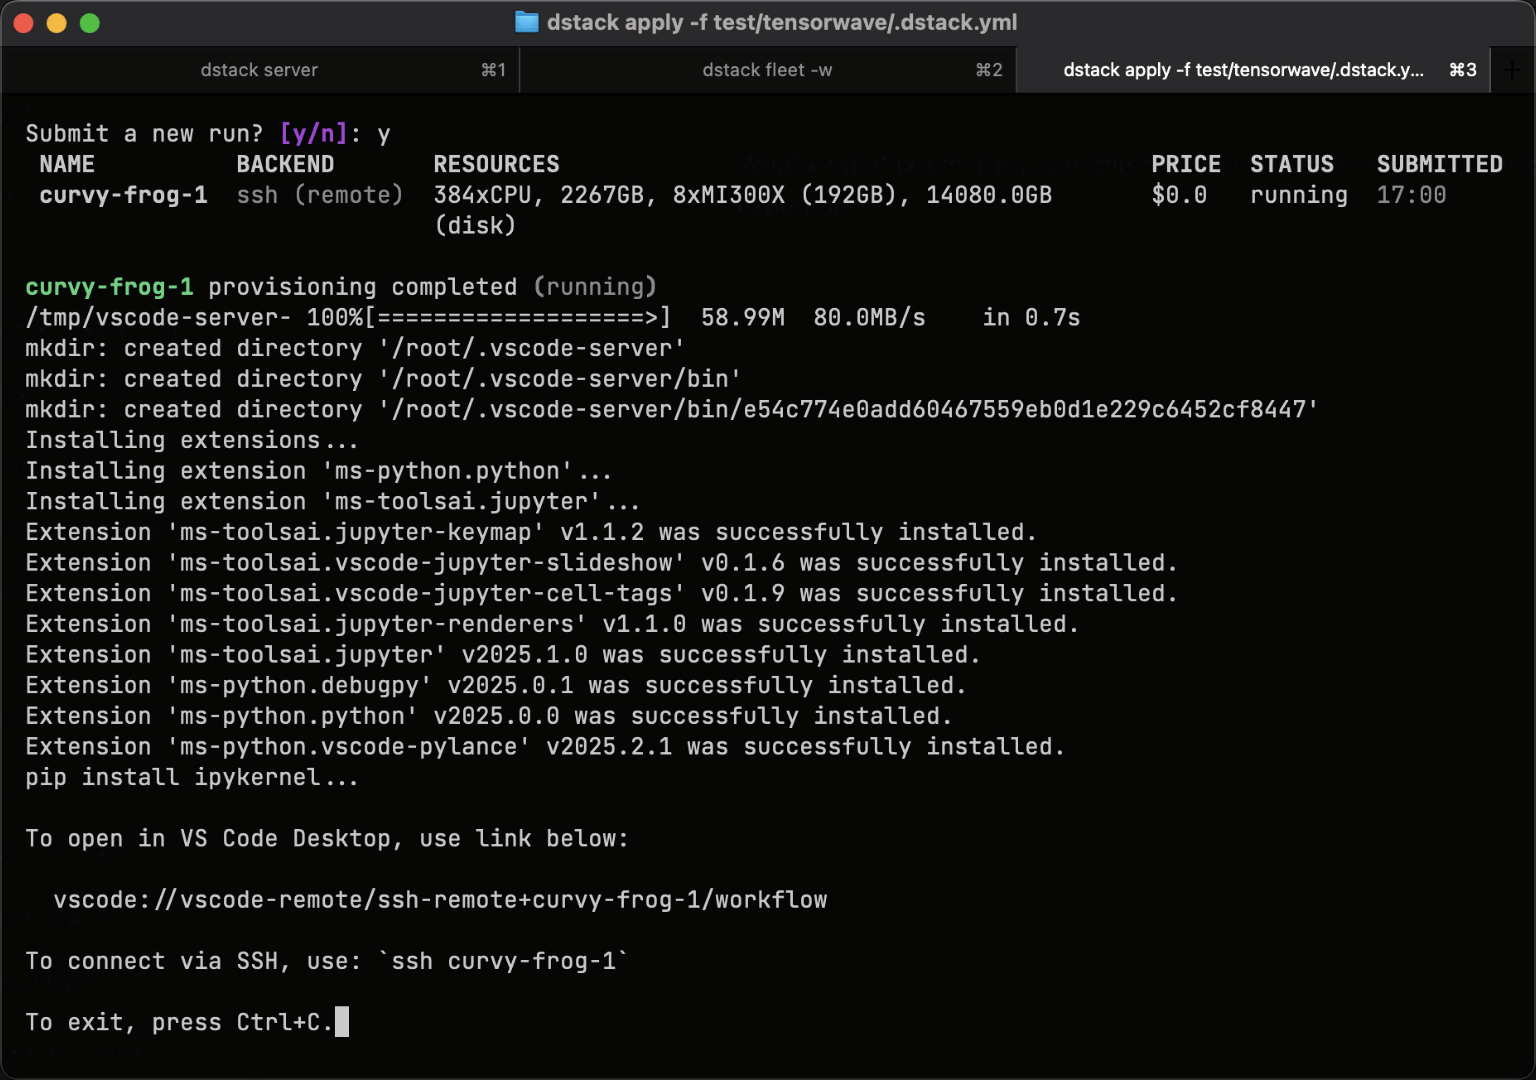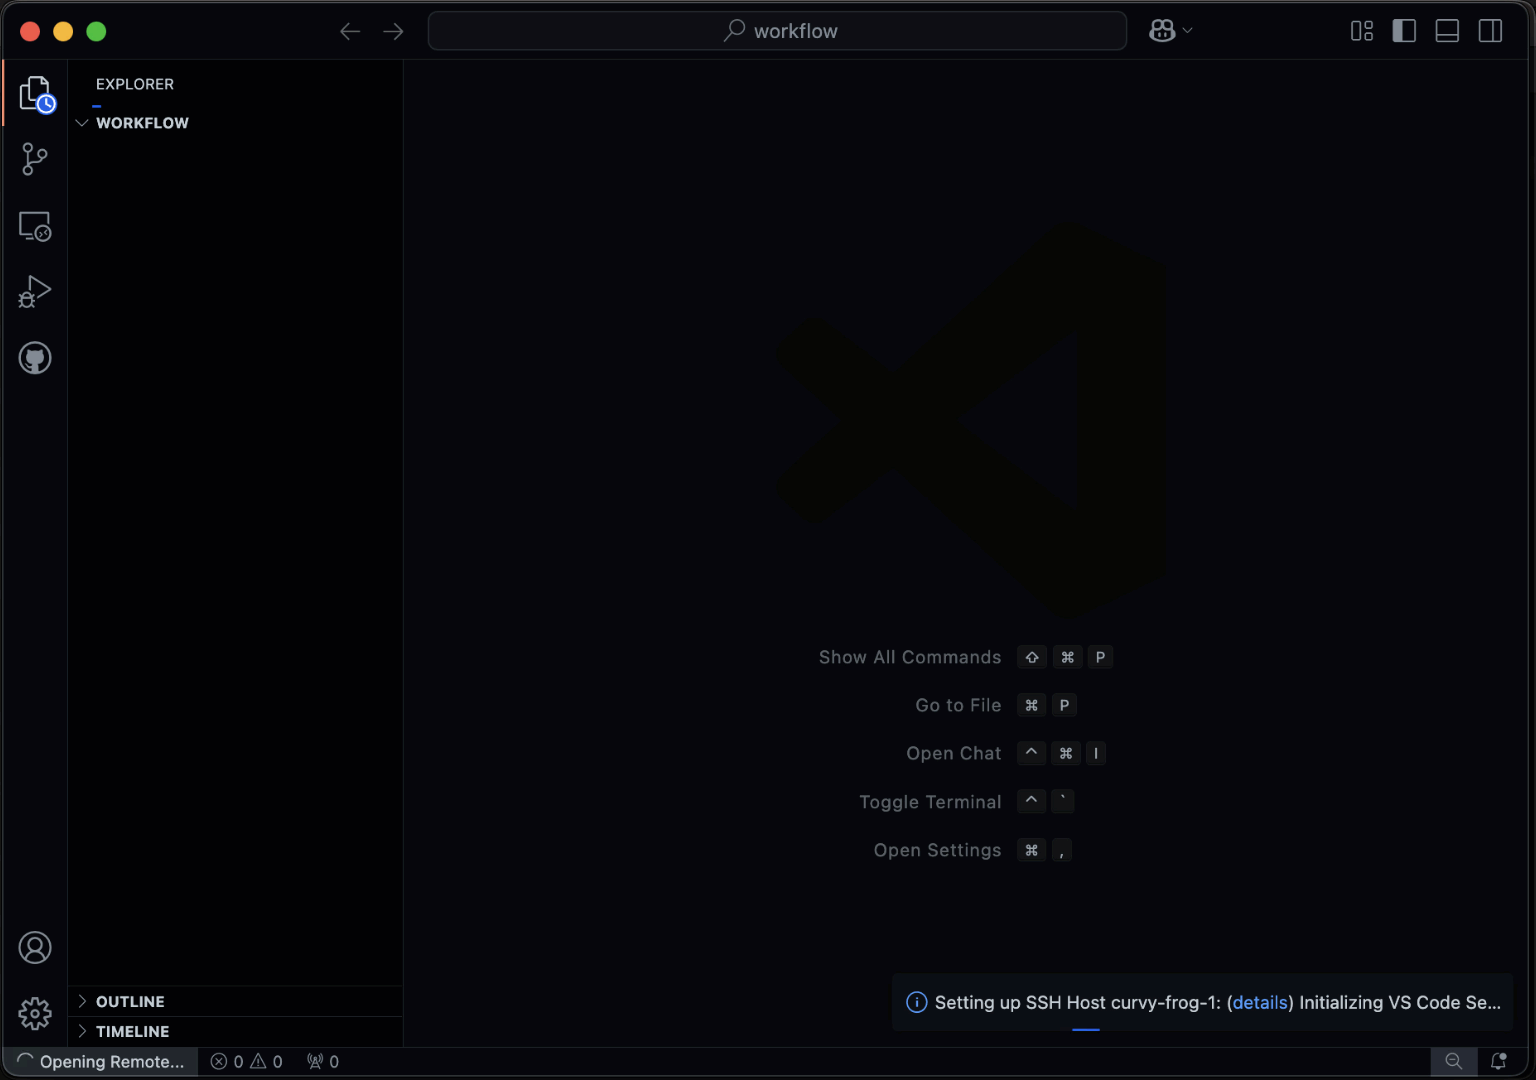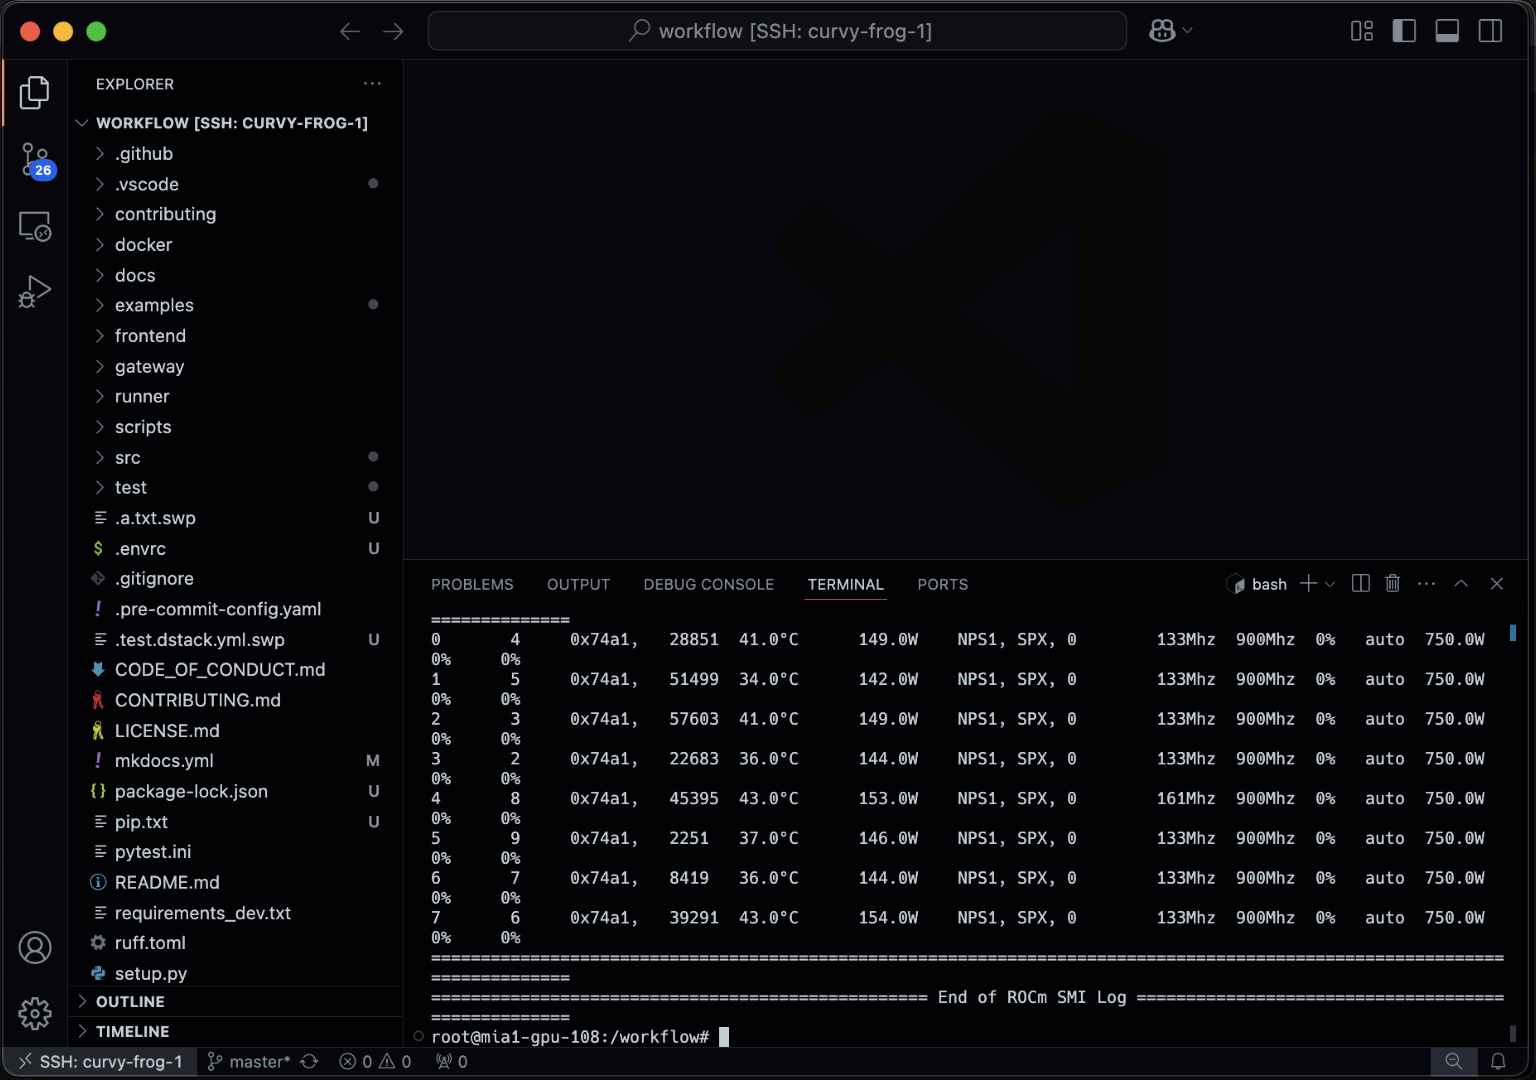 -
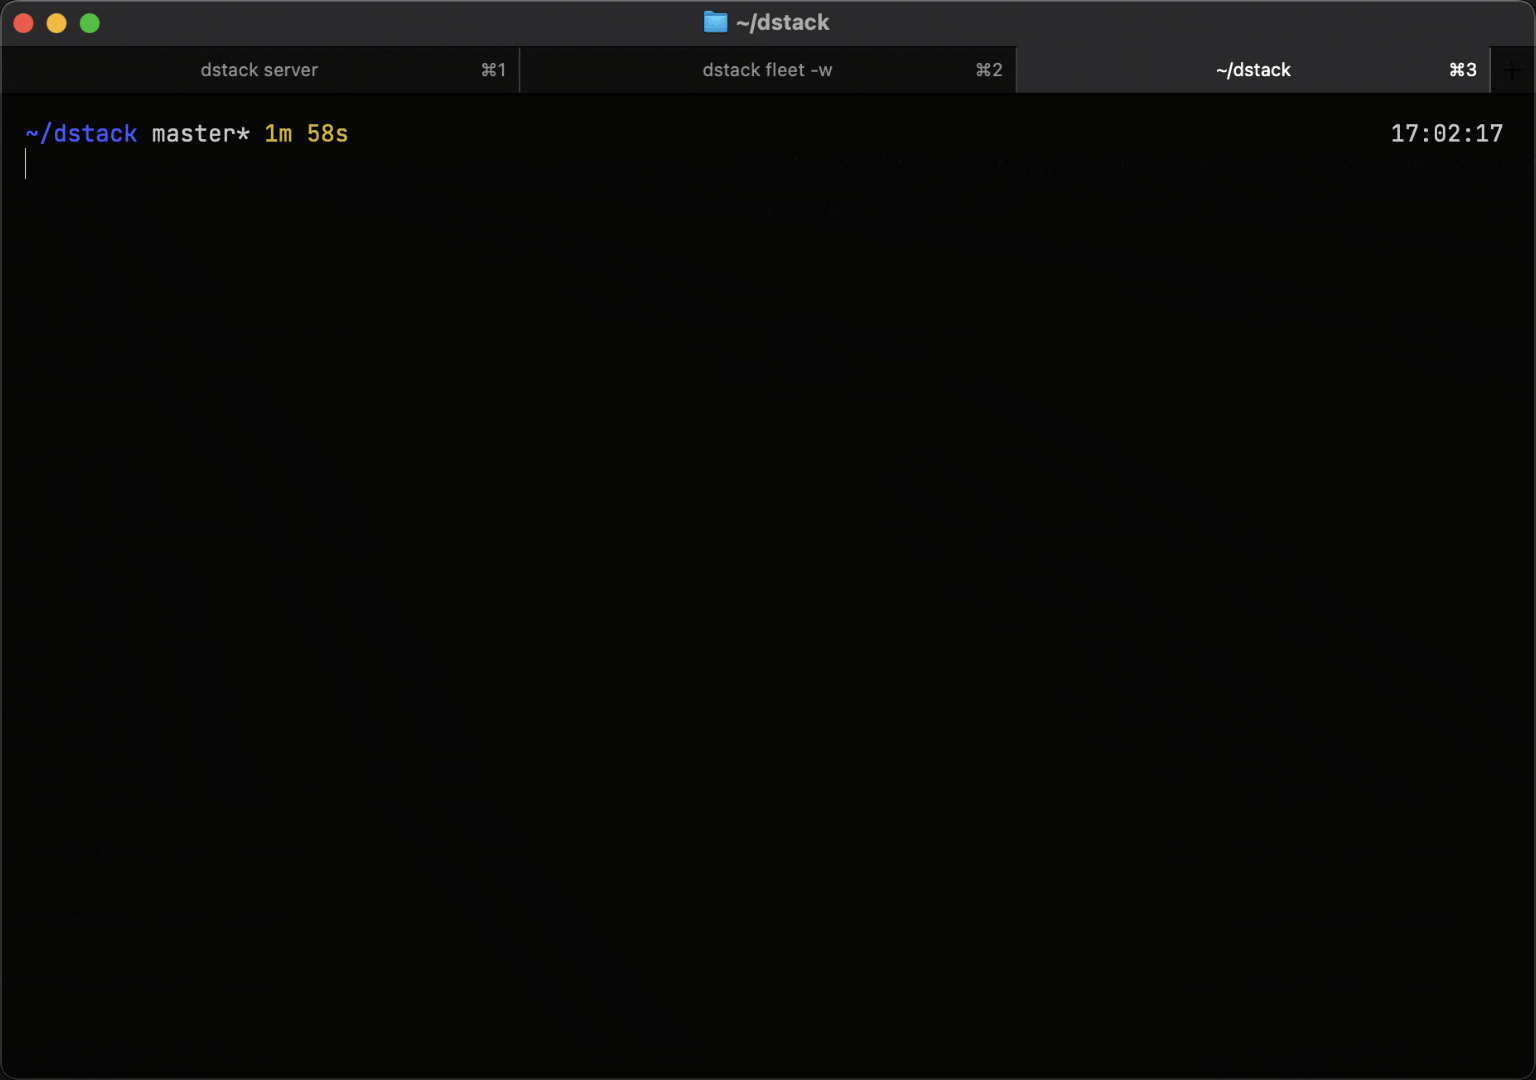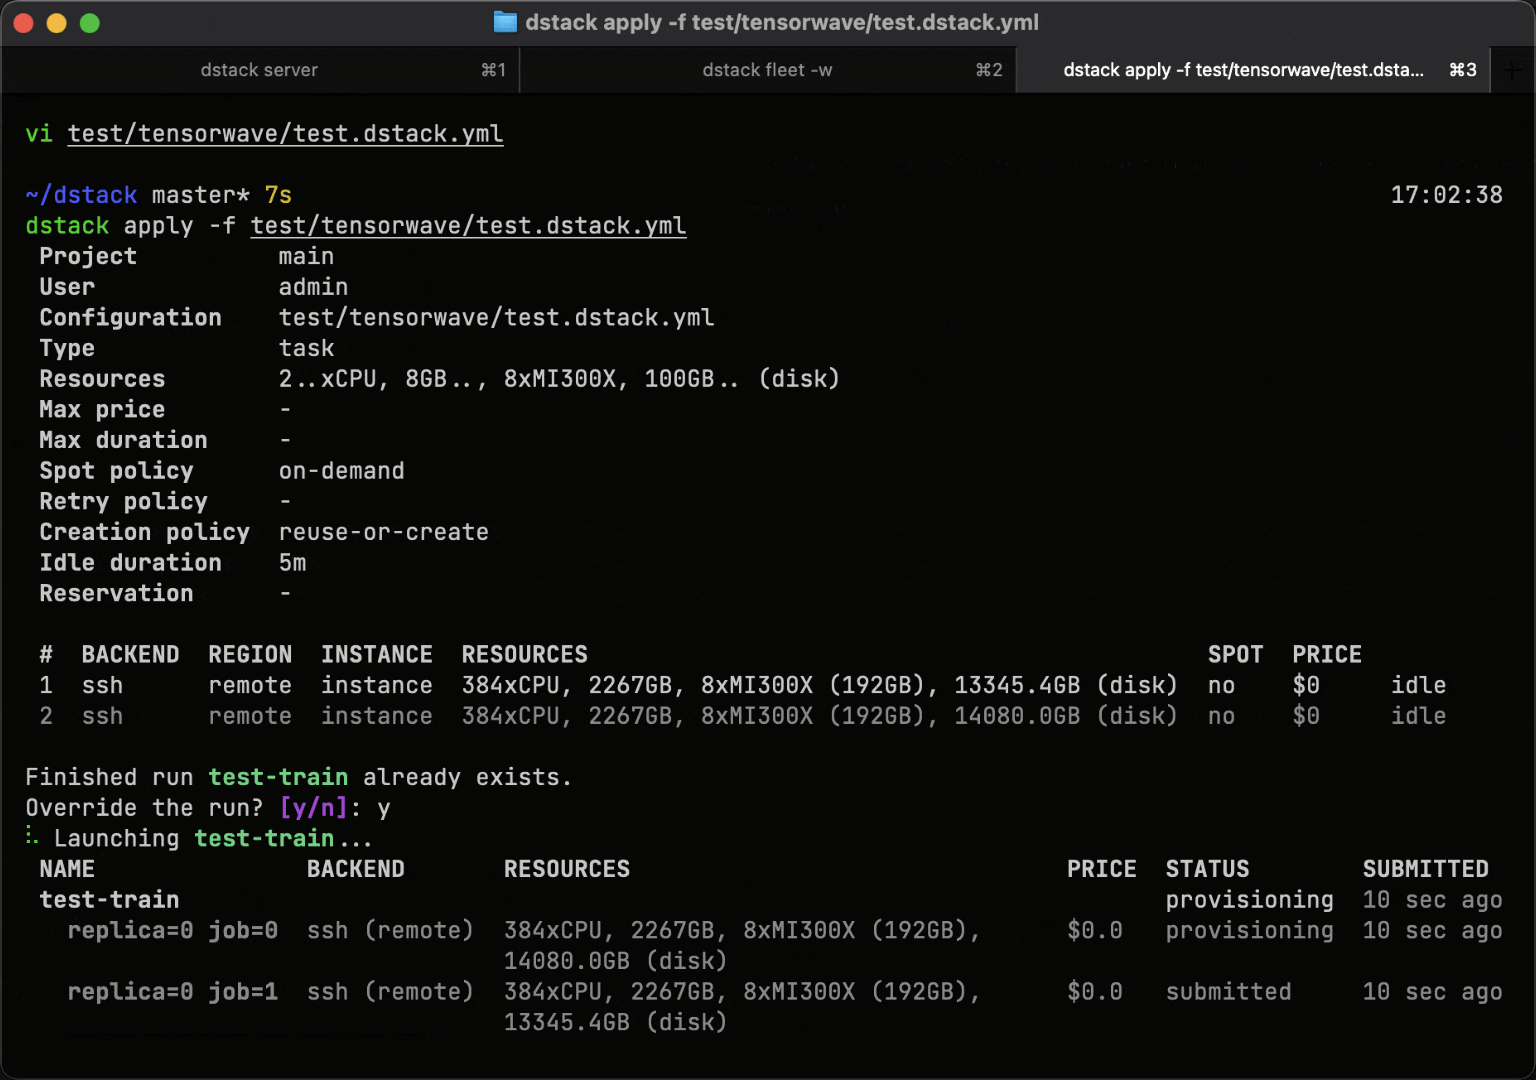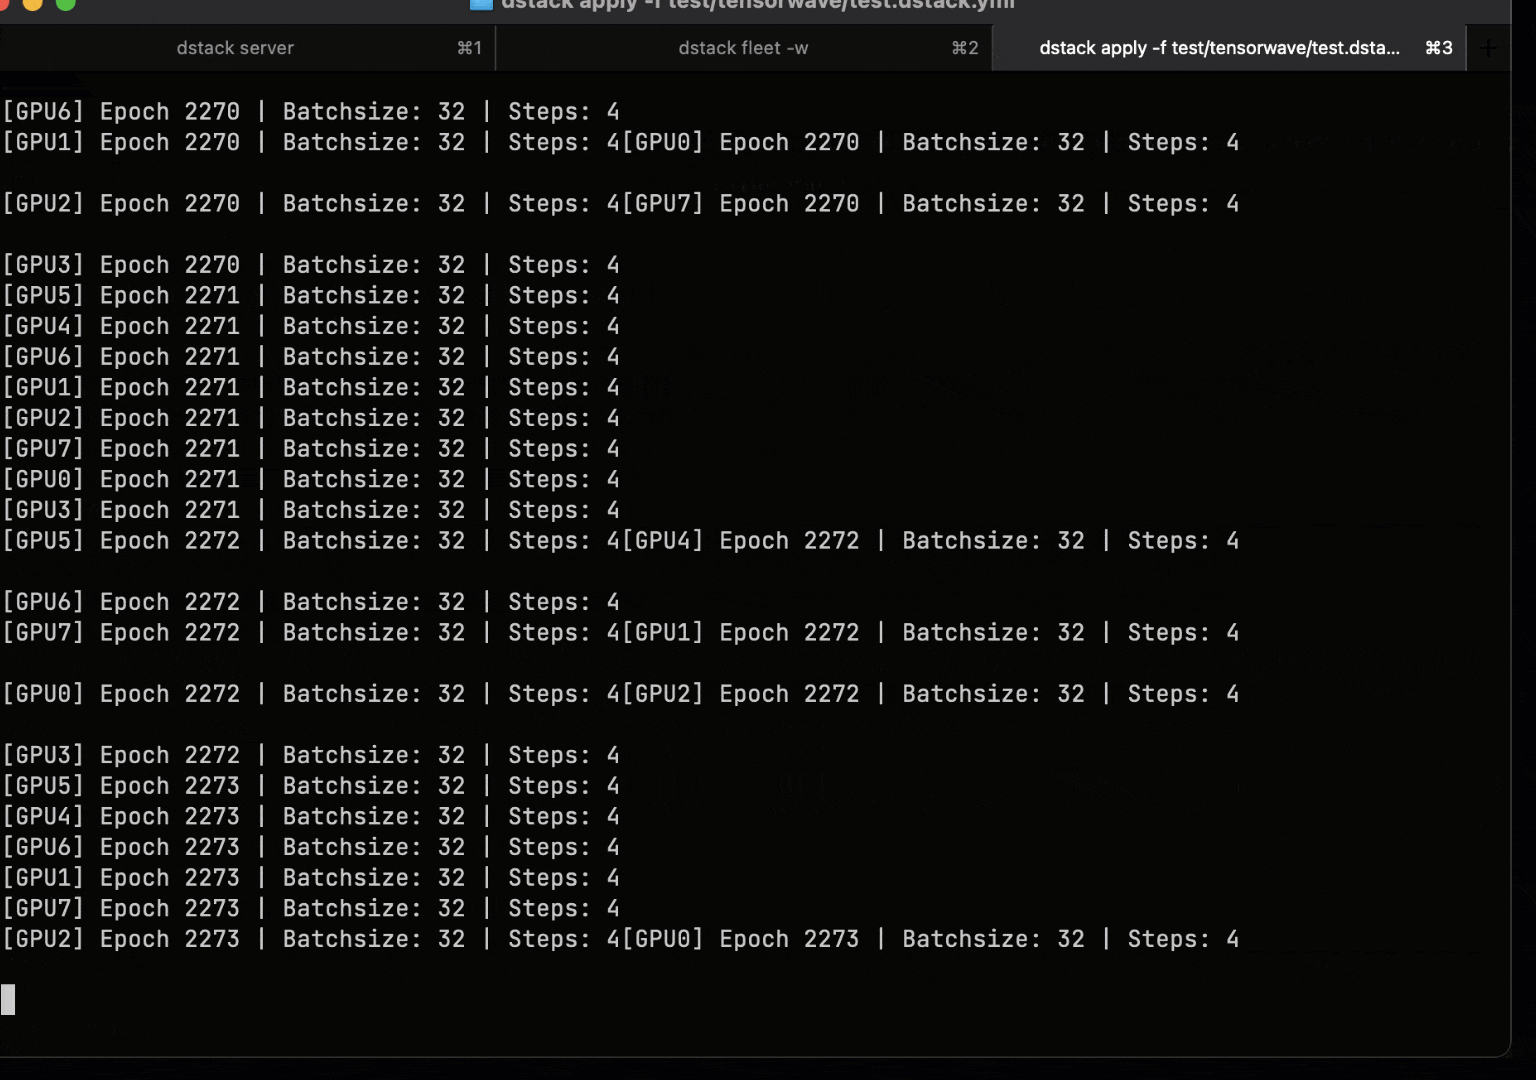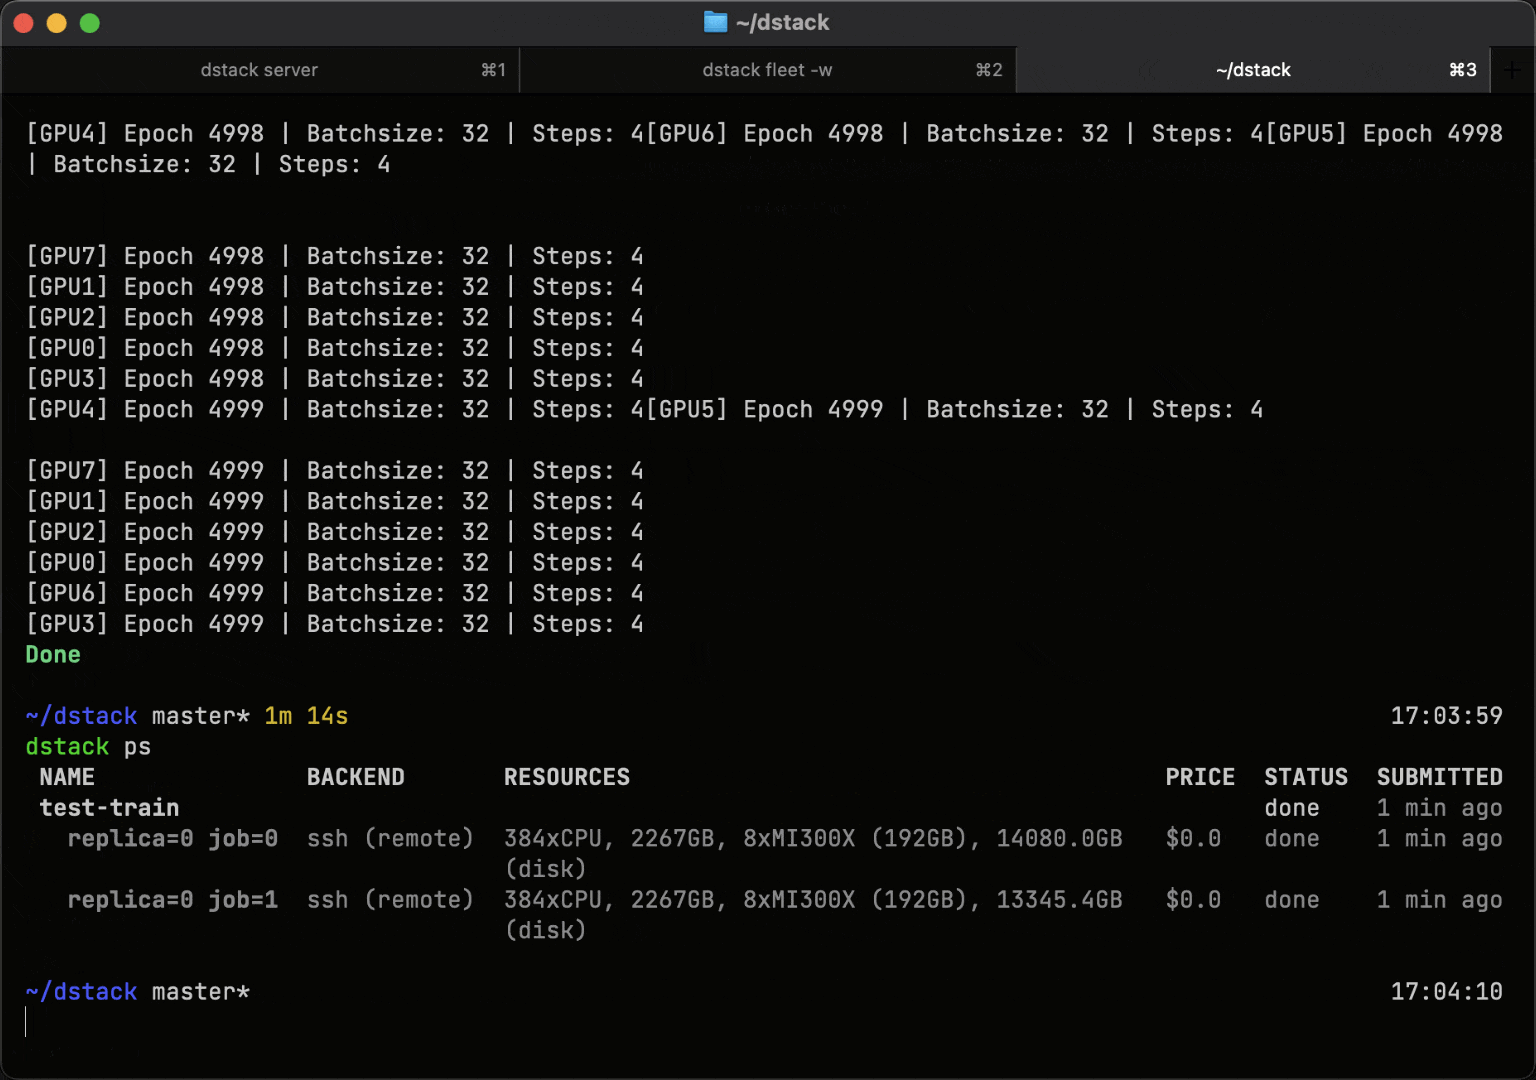 -
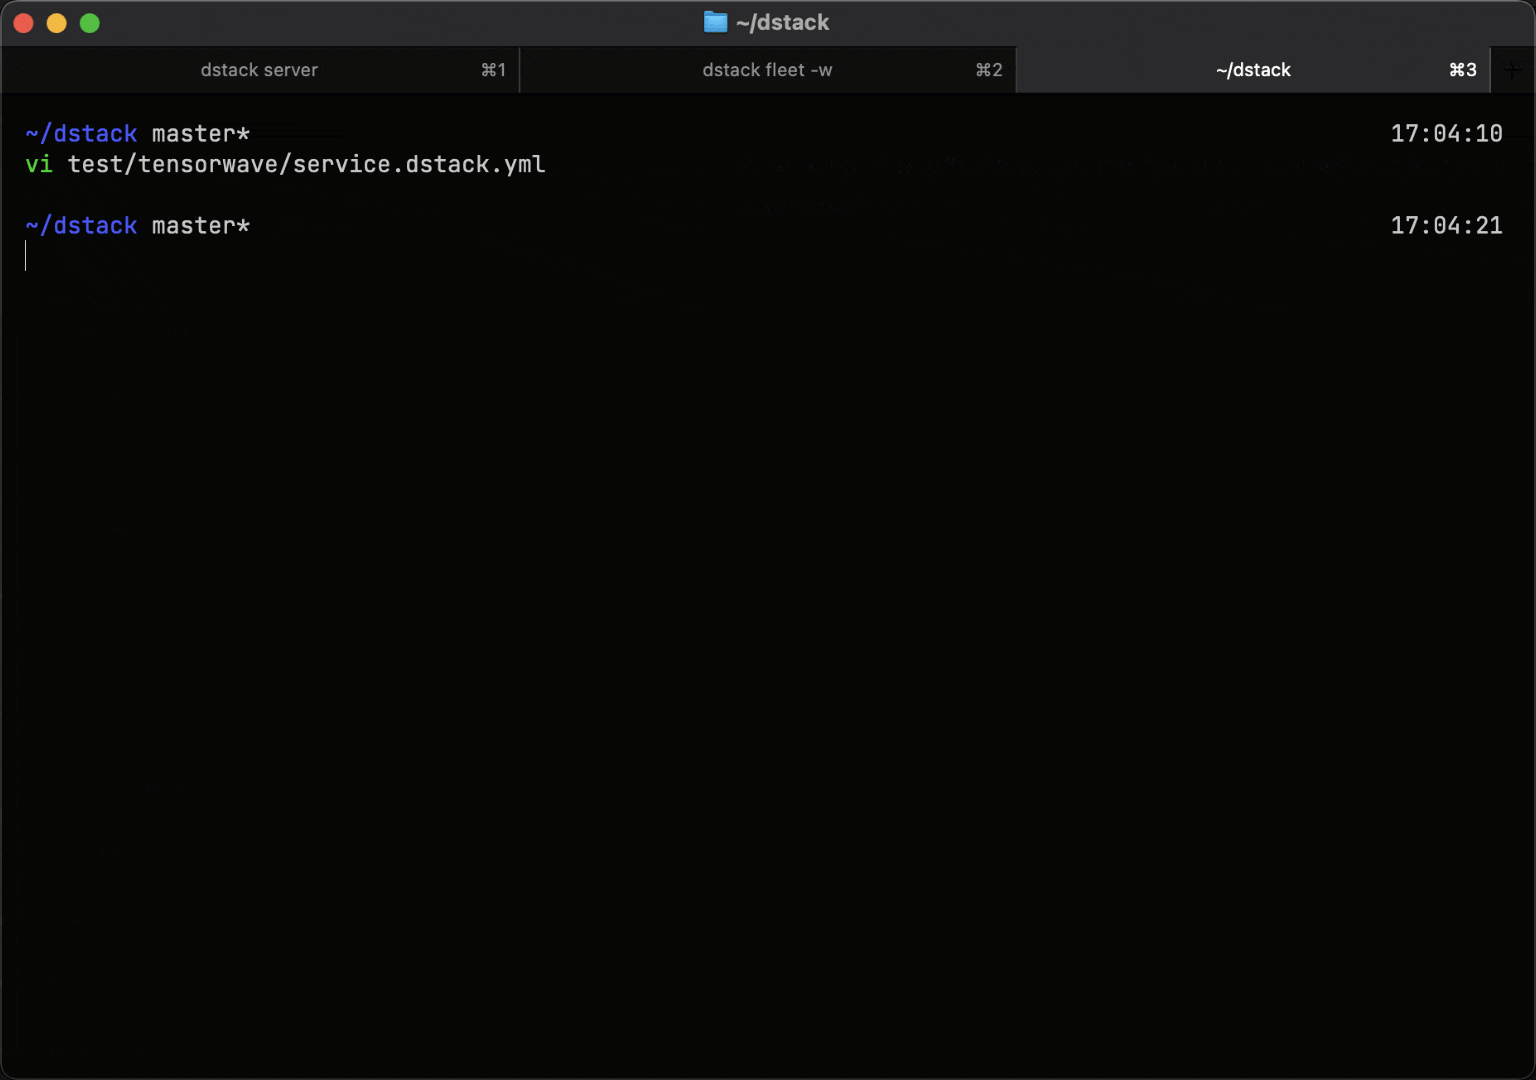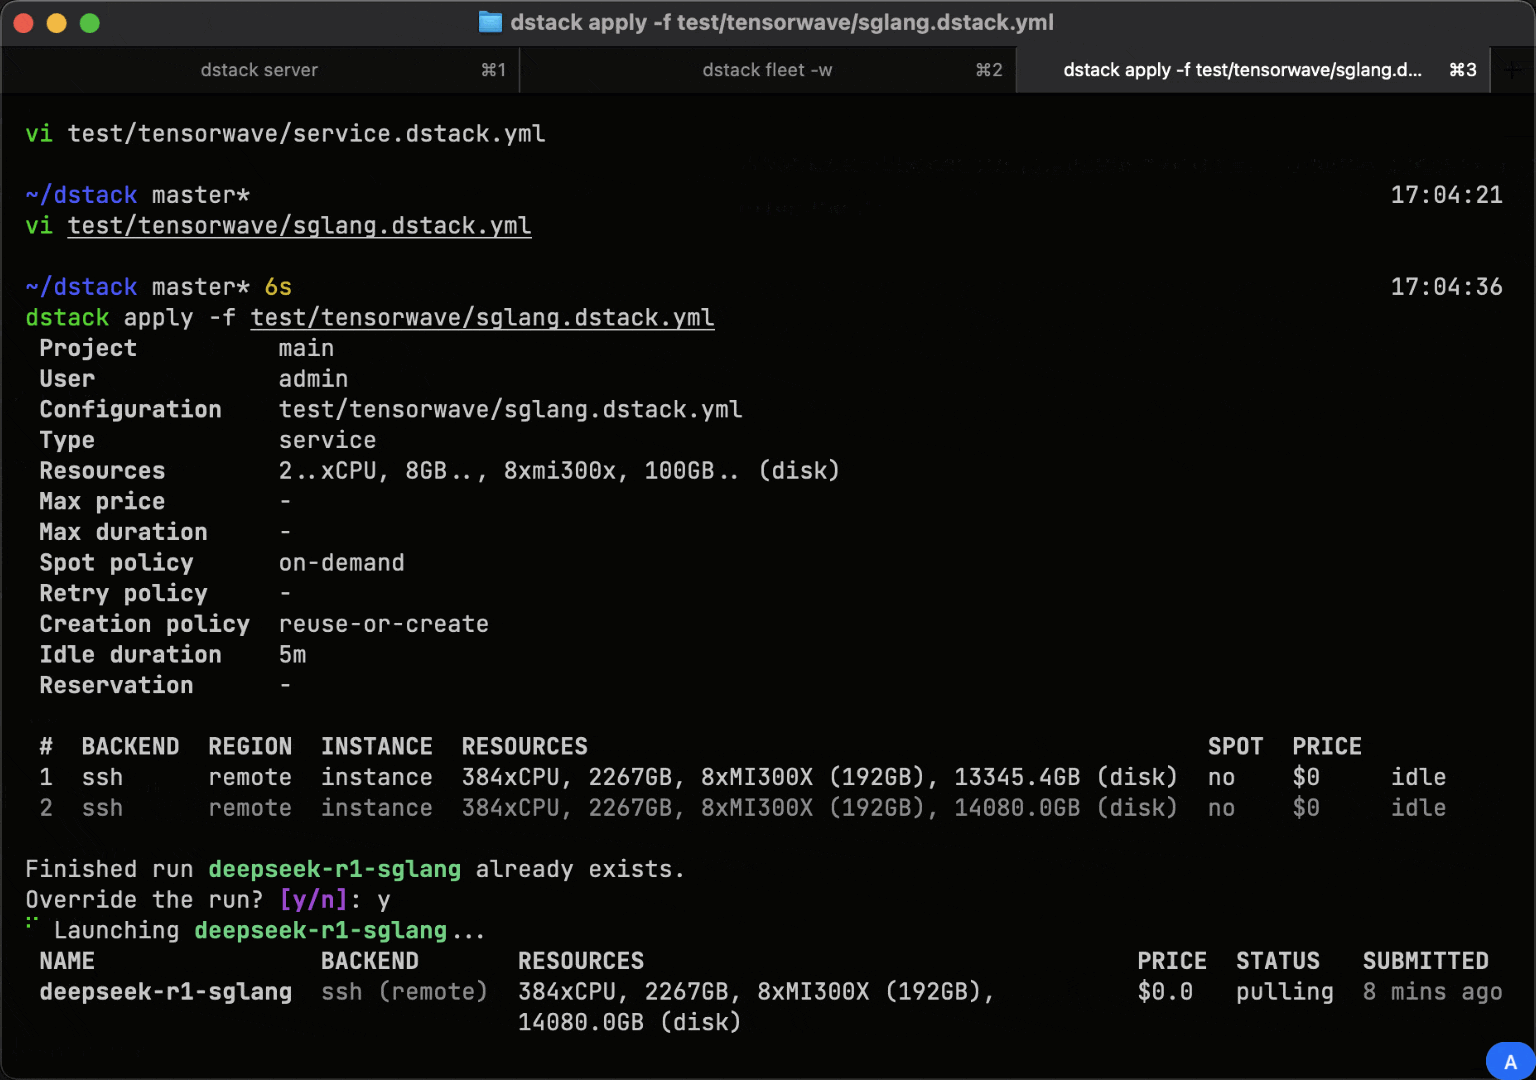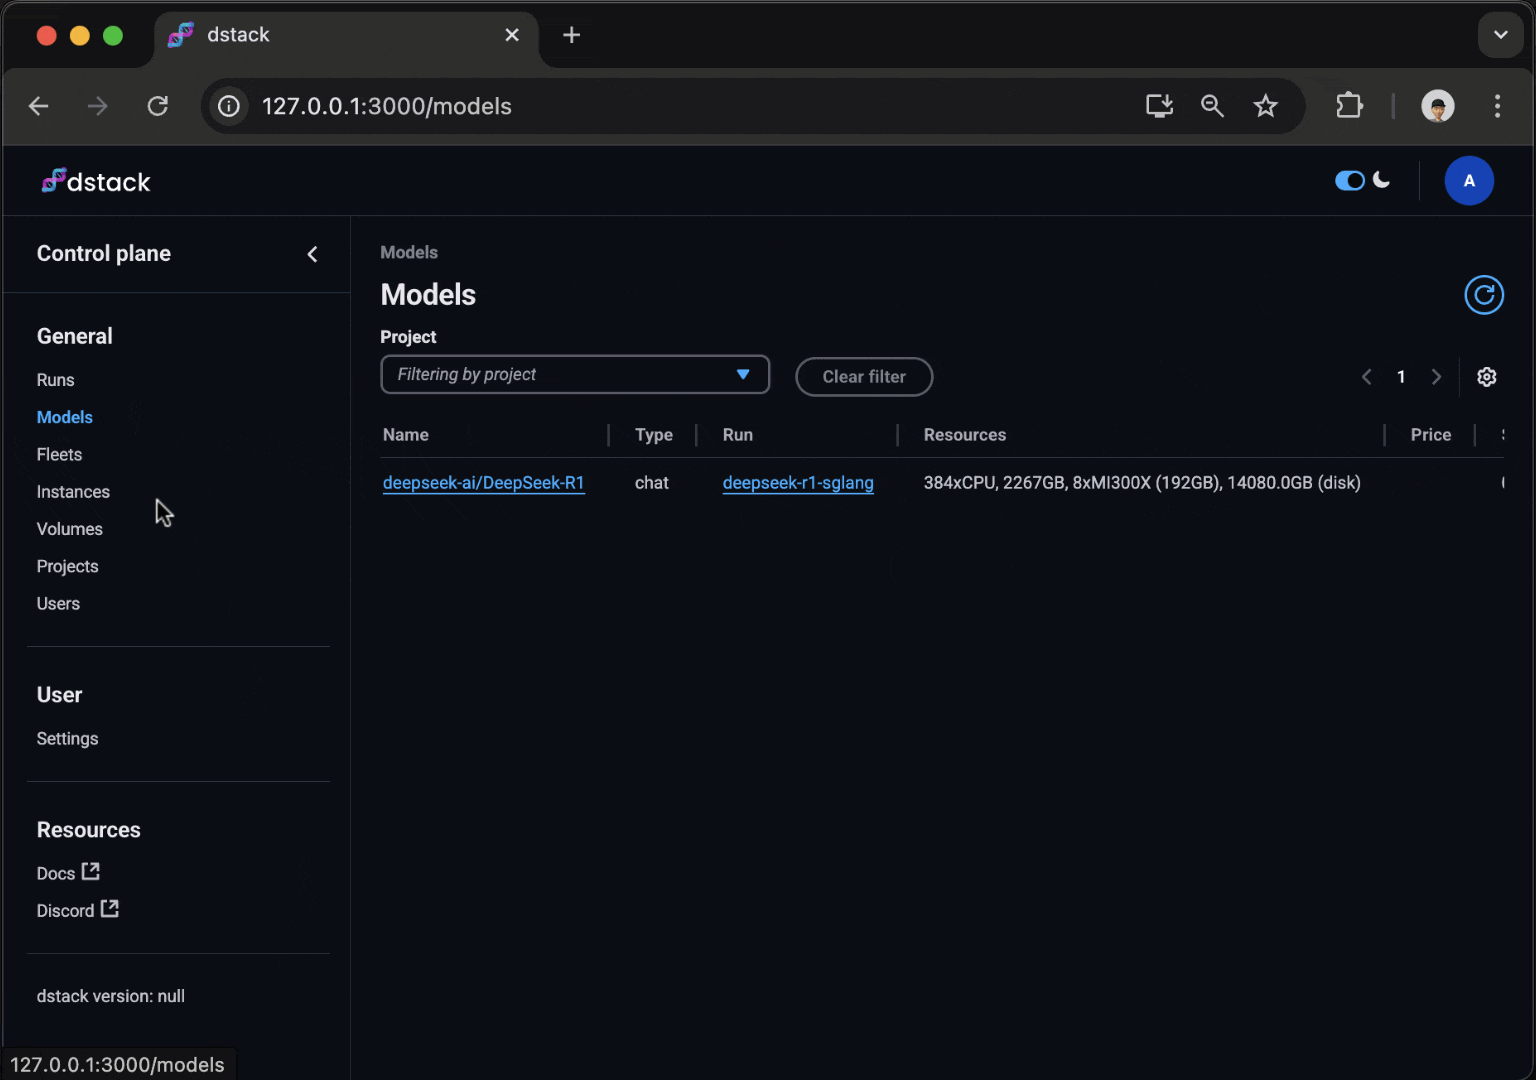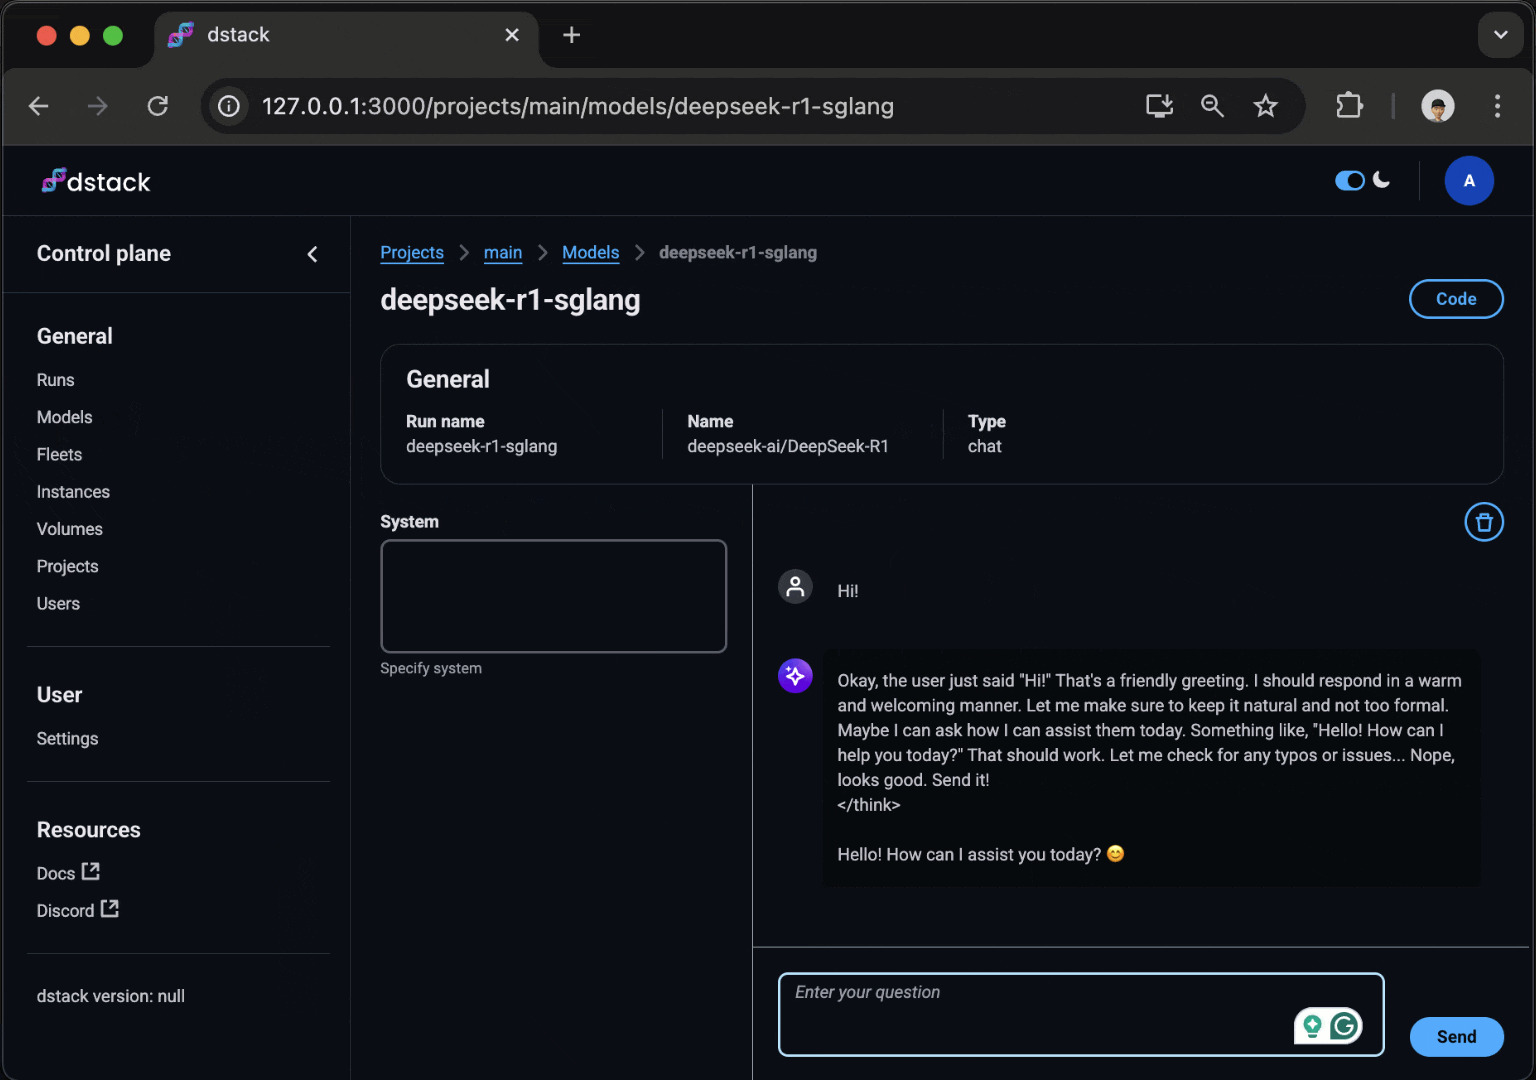 -
 -
 -
 -
 -
 -
 -