





Physics & Astronomy graduate focused on building reliable technical systems across abstraction boundaries. I'm particularly interested in DevOps, robotics, and physical AI, with an emphasis on automation, deterministic behaviour, failure handling, and understanding how software interacts with the physical systems beneath it.

Deterministic, transaction-aware scaffolding for modern Python projects



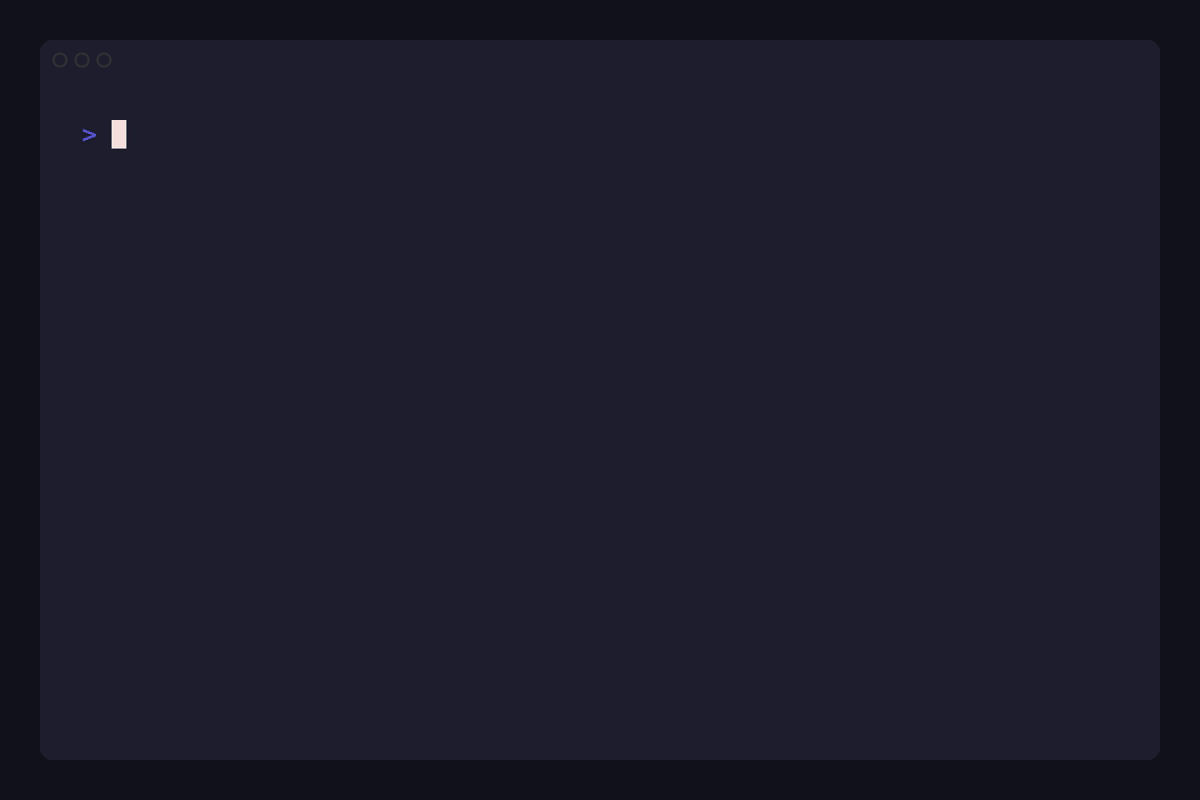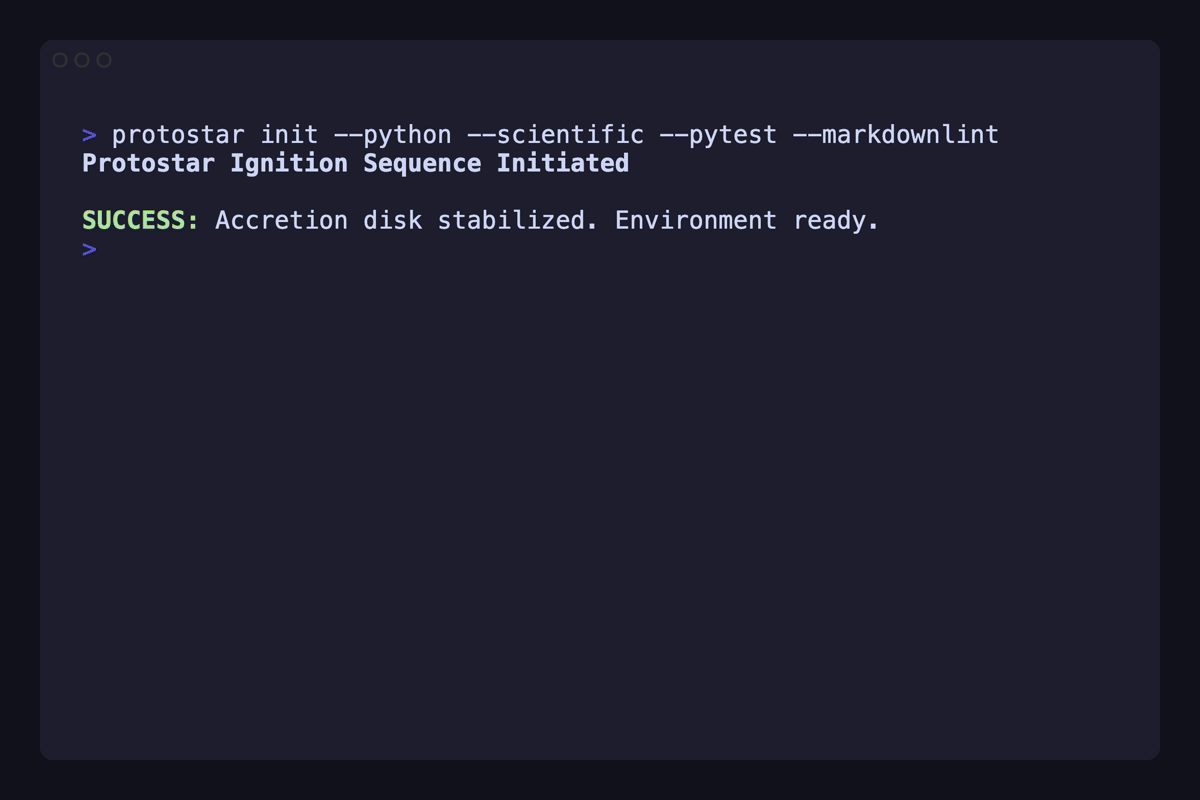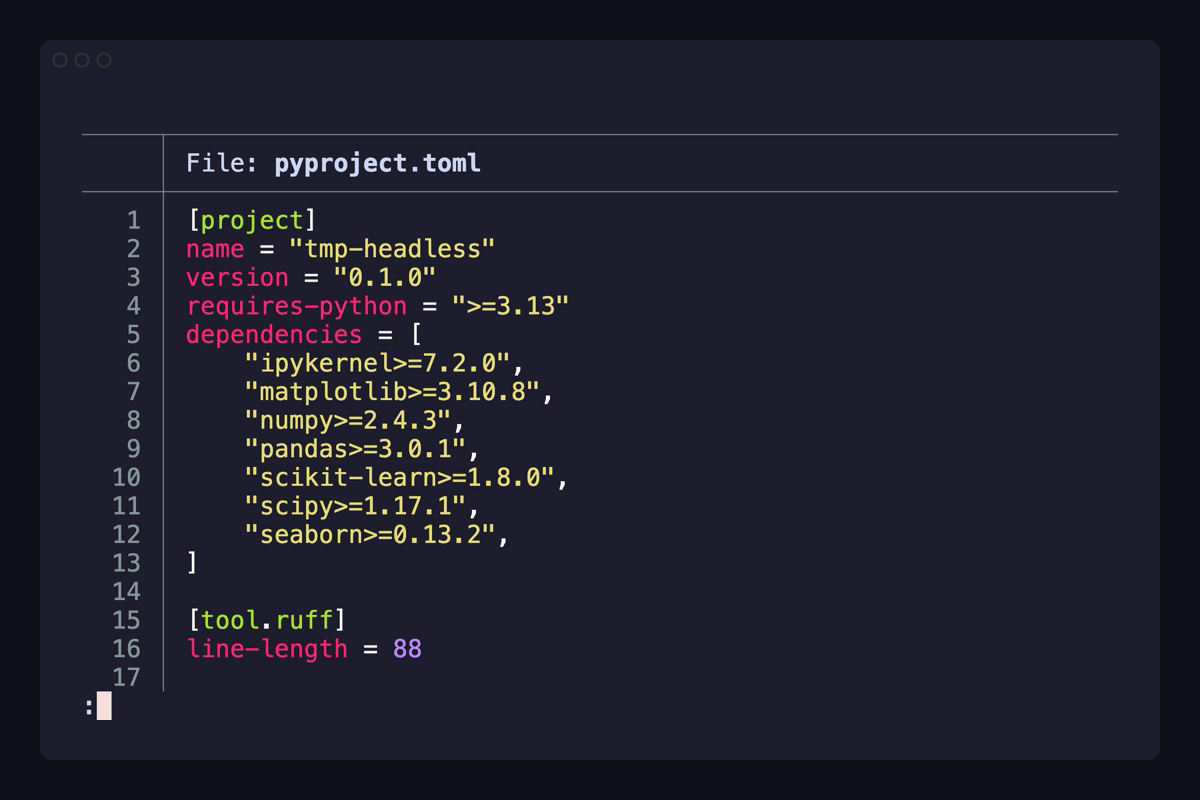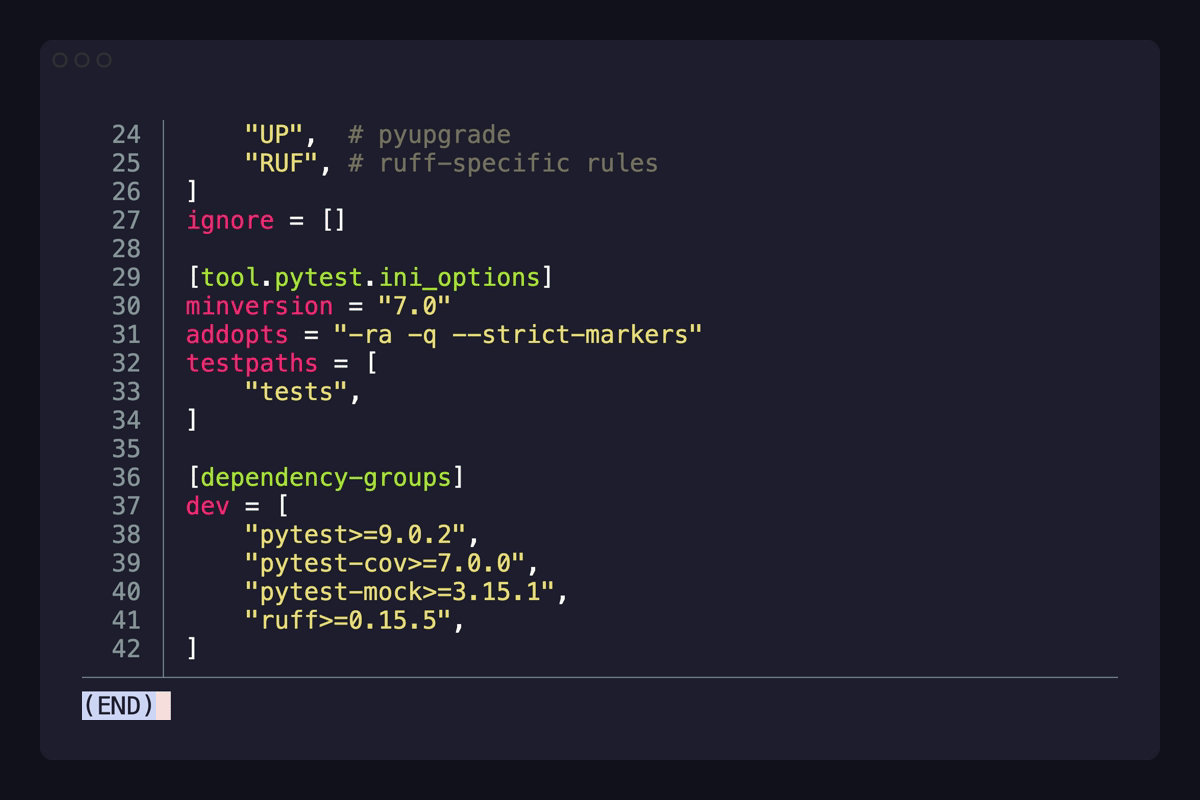
Protostar treats project initialization as a controlled state transition rather than a sequence of shell commands. Repository state is calculated first as structured data, then applied by a separate execution engine with explicit failure and rollback semantics.
-
Plan first, execute second:
plan()is read-only and produces anEnvironmentManifestcontaining the exact intended filesystem, configuration, dependency, and subprocess operations.execute(manifest)is the only phase permitted to perform side effects, so--dry-run --jsonexposes the same plan that live execution consumes. -
Bounded transactional rollback: A mutation journal records transaction-managed paths before modification, filesystem writes pass through a transaction-aware interface, and managed subprocesses are terminated before rollback. Failed or interrupted executions restore journaled files in reverse order to their original bytes and modes rather than leaving a partially configured workspace.
-
Headless core: The engine communicates through structured
InitRequest,EnvironmentManifest, andExecutionResultobjects and contains no terminal interaction. Prompts, progress displays, collision decisions, and JSON serialization remain in the CLI layer, allowing the same core lifecycle to support humans, CI, and automation. -
Semantic configuration composition: Uses
tomlkitAST manipulation and format-aware merge logic instead of replacing existing configuration files. Tooling can be introduced while preserving unrelated keys, comments, formatting, and existing project state. -
Failure handling as architecture: Pre-flight validation occurs before mutation, dependency-installation failures are fatal, collision states are represented explicitly, and the transaction boundary is documented rather than implying that arbitrary external side effects can always be reversed.
End-to-end audio instrumentation spanning analog electronics, embedded acquisition, and Python signal analysis


Built as a complete measurement chain rather than a collection of isolated electronics projects. To quantitatively characterize a CD4049 CMOS guitar overdrive, I built the supporting infrastructure myself: low-noise power regulation, the analog device under test, an RP2040-based data-acquisition instrument, and the host-side signal-processing pipeline.
-
Custom instrumentation: Designed a configurable analog front end for the RP2040 ADC supporting high-impedance instruments, line-level audio, and DC sensor inputs. The signal path handles current limiting, AC coupling, midpoint biasing, attenuation, and input protection before acquisition.
-
Hardware tradeoffs: Component choices were made around measurable constraints rather than rules of thumb. For example, the high-impedance protection stage uses silicon rather than Schottky clamps to trade a higher clamp voltage for substantially lower reverse leakage, preserving measurement headroom and DC accuracy.
-
Timing-aware acquisition: Store-and-forward firmware captures into memory before USB transmission, decoupling sample timing from host-side USB latency. The prototype achieved a calibrated 97.8 kSps sample rate with a measured 1.3 mV RMS read-noise floor.
-
Empirical validation: Python/Jupyter tooling performs calibrated waveform analysis, Hann-windowed FFTs, and harmonic characterization. Measurements resolved the Red Llama's soft-knee saturation and strong second-harmonic component; active sweep generation and transfer-function deconvolution are the next stage of the analysis.
Reusable release automation and distribution infrastructure for Python projects


Centralized infrastructure for release policy that would otherwise be duplicated across repositories. Application projects remain thin callers while versioning, publication, Homebrew synchronization, dependency resolution, and failure handling live in one tested source of truth.
-
Two-phase release orchestration: A read-only pre-flight phase validates tools, repository cleanliness, branch state, remote synchronization, SemVer metadata, and tag availability before any release state is changed.
-
Transactional publication: Execution updates
pyproject.toml, synchronizes and validatesuv.lock, creates the release commit and annotated tag, then publishes branch and tag together withgit push --atomic. Local state is rolled back if execution fails or is interrupted before successful publication. -
PyPI → Homebrew automation: Reusable workflows wait for new PyPI distributions, verify source checksums, resolve dependency trees with
uv, generate Homebrew resource blocks, update Ruby formulae, and runbrew audit. A separate path supports projects whose dependencies are exported directly from their repository manifests. -
Reusable by design: Automation scripts use PEP 723 inline metadata so they can be executed directly with
uv run, while caller repositories delegate to centralized GitHub Actions rather than maintaining copies of the release logic.

Deterministic dependency management for physical hardware


Software package managers make dependency resolution deterministic; physical projects still fail because someone forgot a ten-cent component. Star Ground applies the same mindset to hardware procurement, converting inconsistent BOMs and inventory into a validated, reproducible pipeline.
-
Structured ingestion: A Strategy-based parsing layer normalizes PDF, CSV, pasted text, uploaded files, URLs, and presets behind a common interface. PDF ingestion prefers spatial table extraction and deterministic parsing rather than probabilistic inference where an incorrect component value can invalidate a physical build.
-
Grammar-based normalization: A
pyparsinggrammar converts engineering notation such as10k,4.7u, and BS 1852 values such as4k7into exactDecimalbase units, avoiding fragile string matching and unnecessary floating-point ambiguity. -
Physical-aware outputs: Procurement logic calculates net need before applying category-specific safety buffers, while generated field manuals sort components by physical Z-height so the software output reflects the actual assembly process.
-
Layered verification: Golden-master snapshots detect regressions against real BOM documents, Hypothesis fuzzes malformed and edge-case values while checking mathematical invariants, and
Streamlit.AppTestexercises the full paste/upload → parse → download workflow in CI.

Fault-tolerant state capture for distributed development


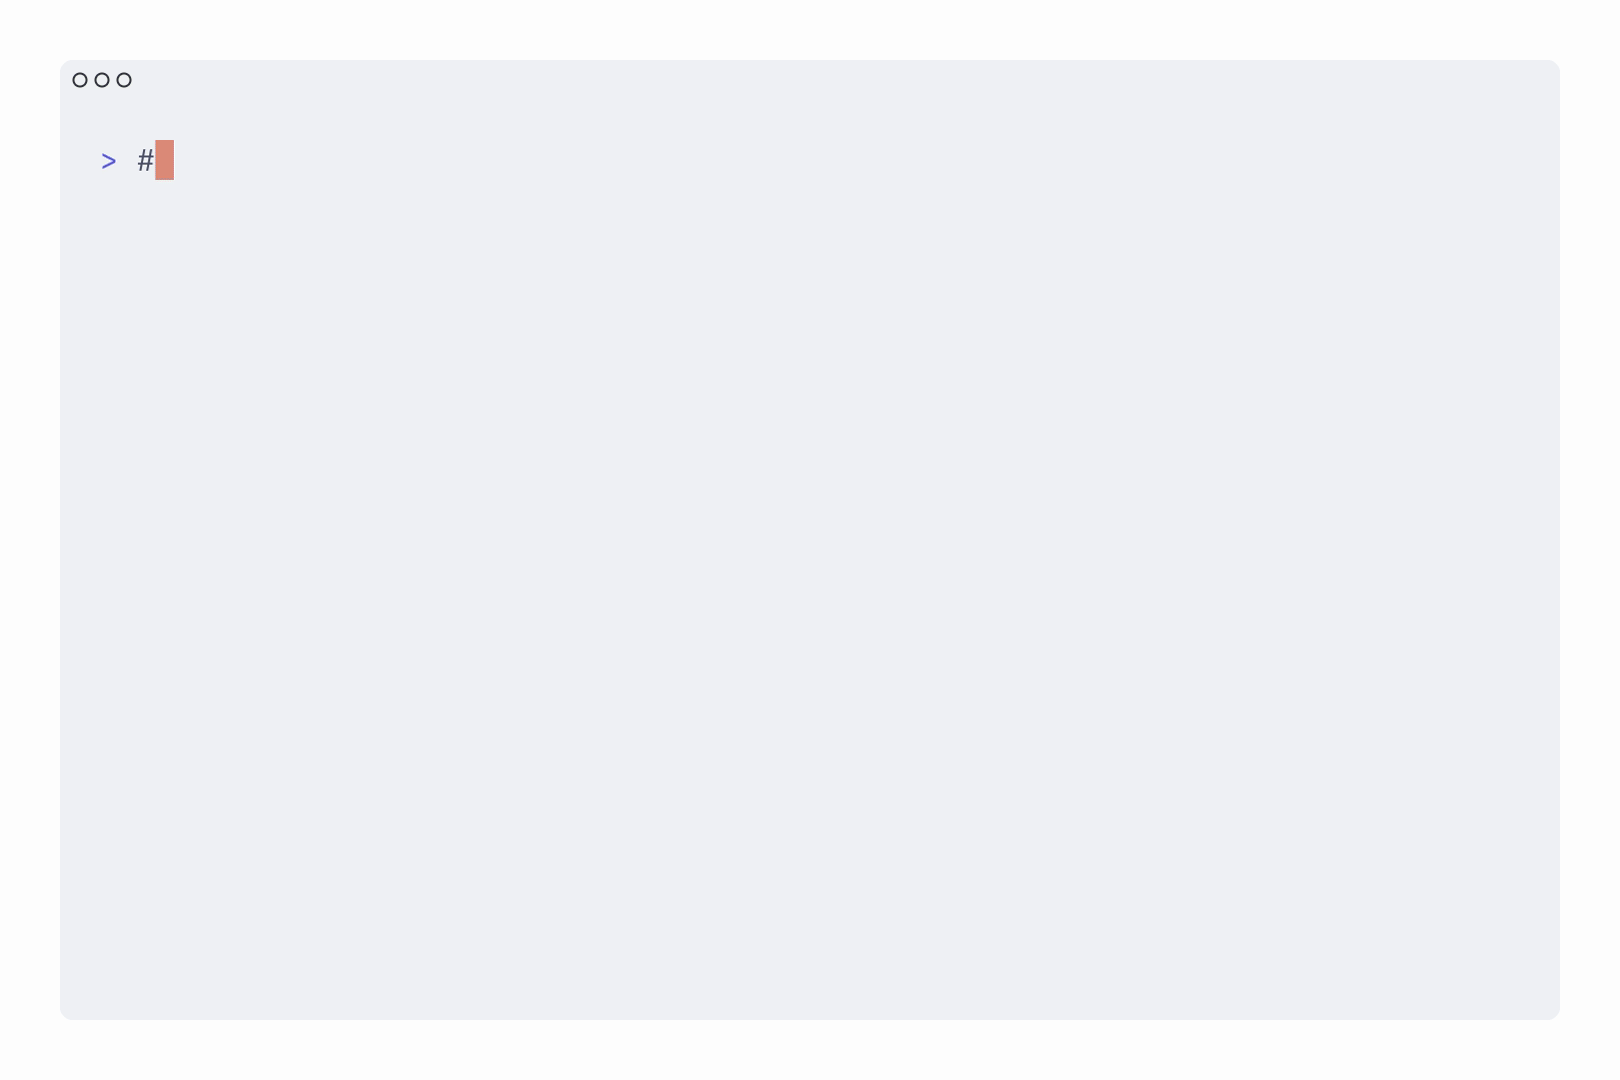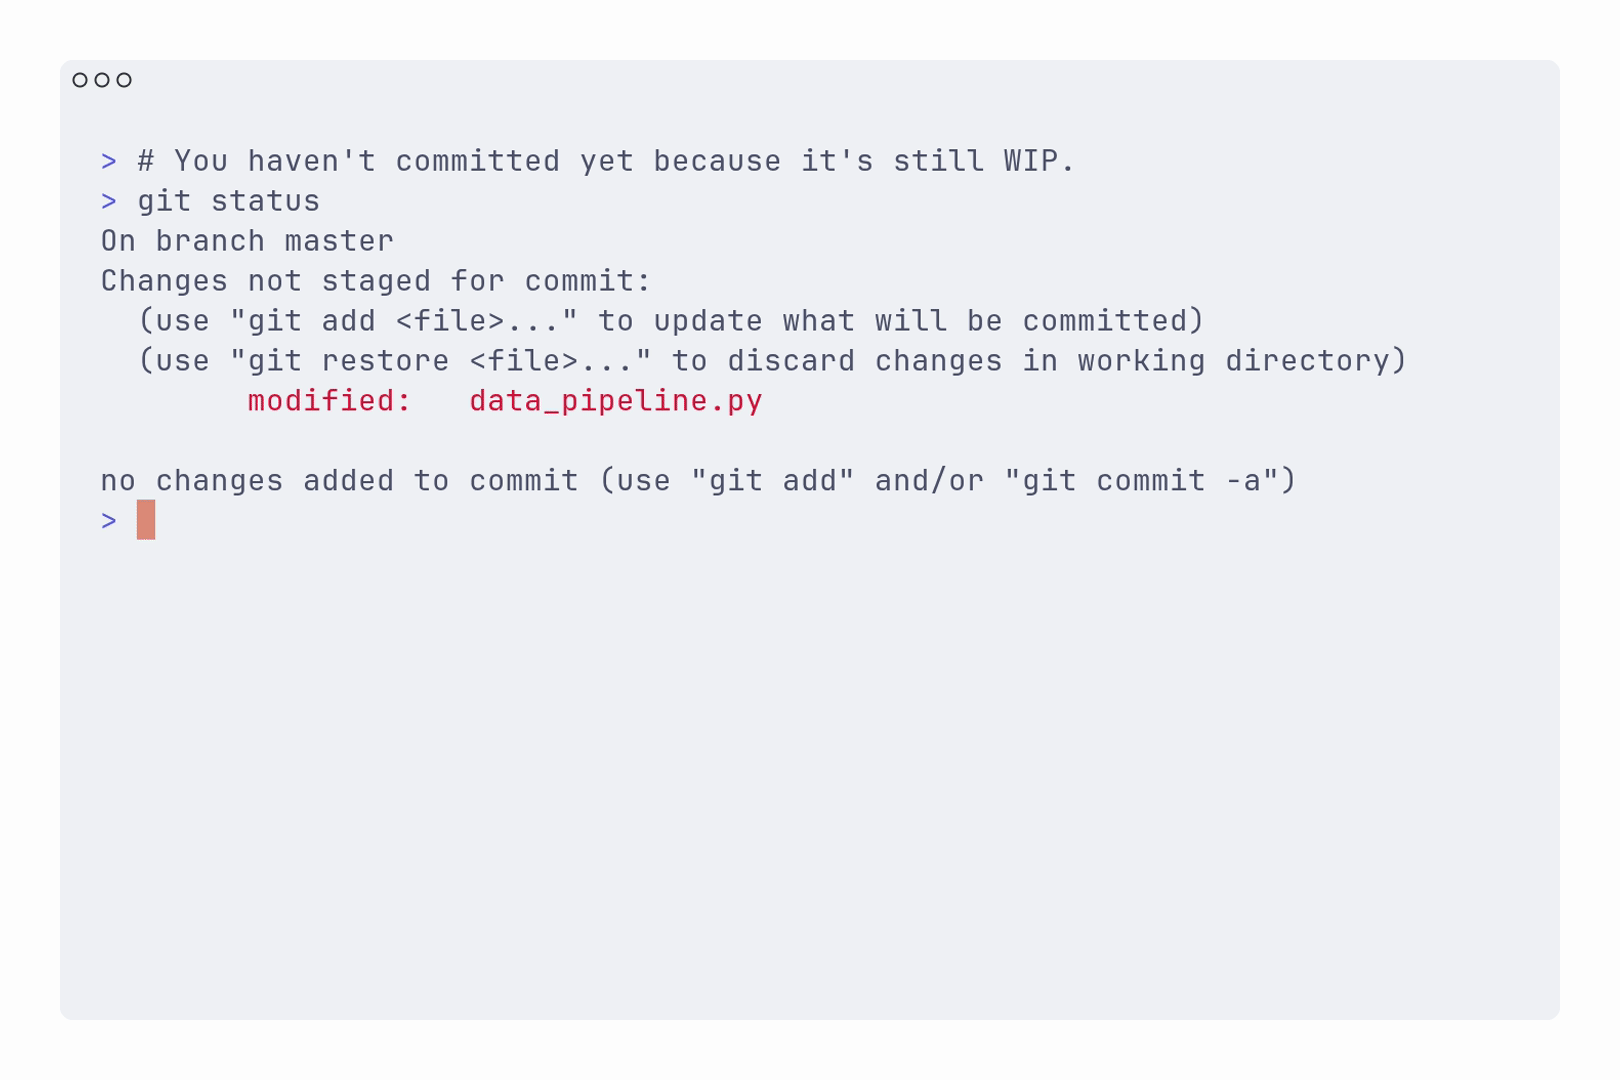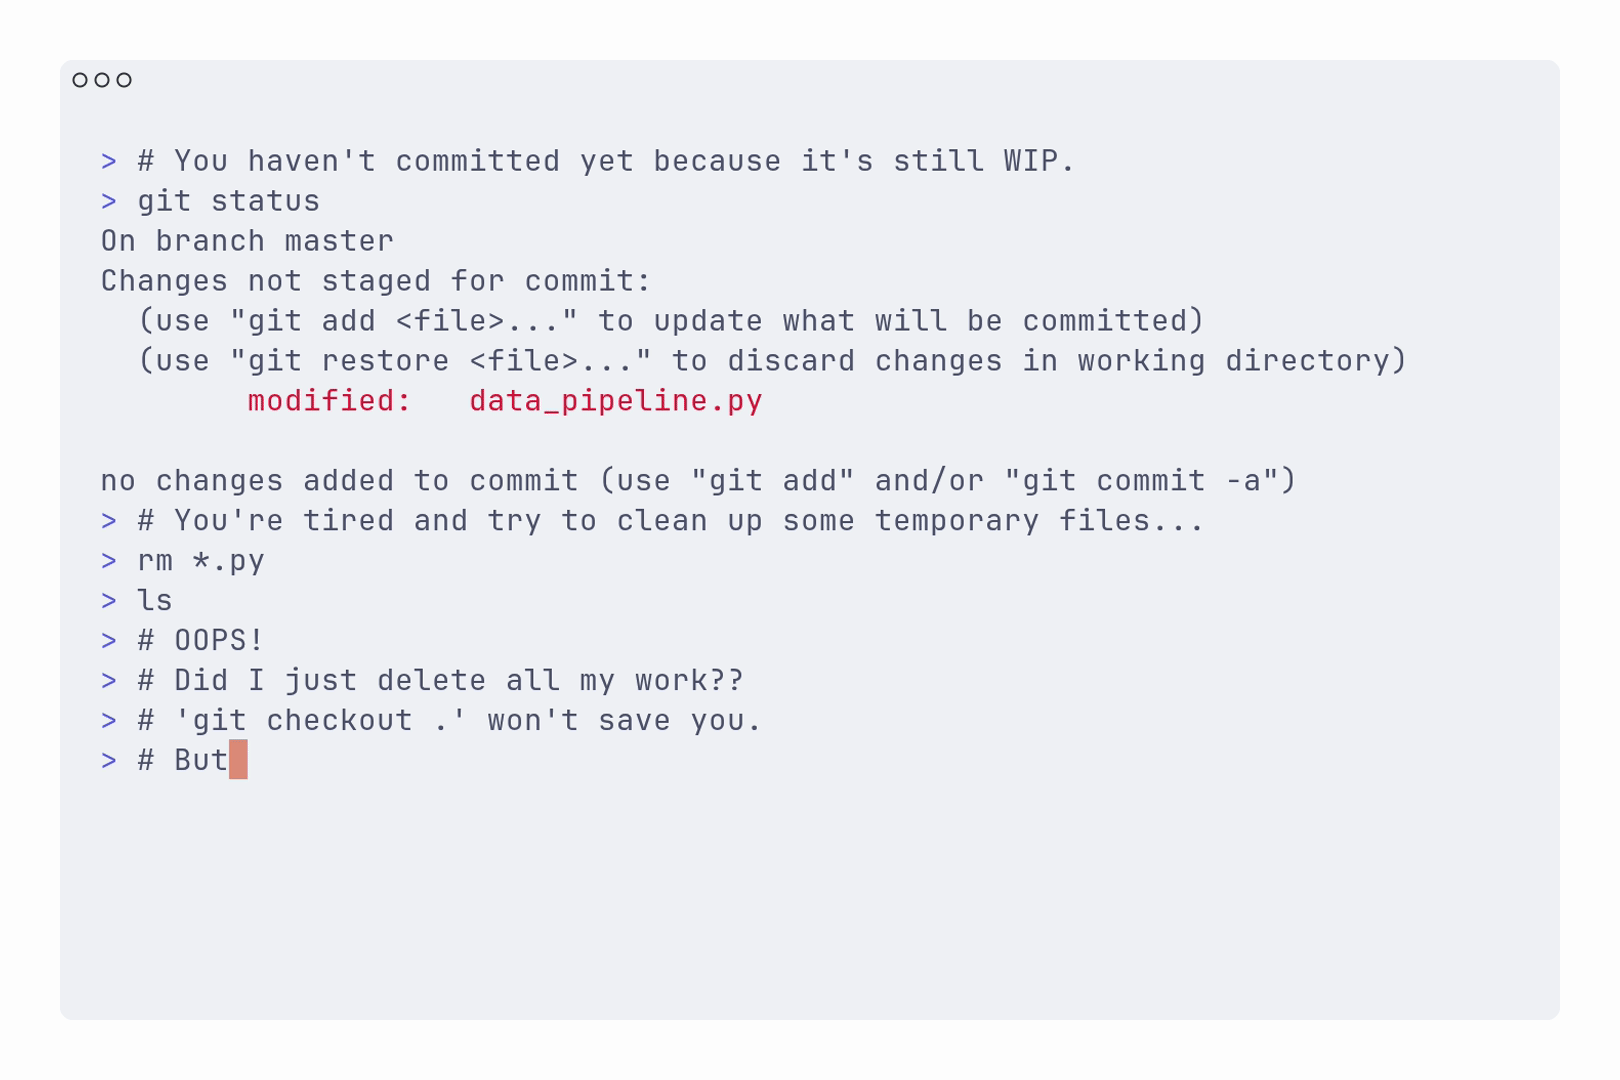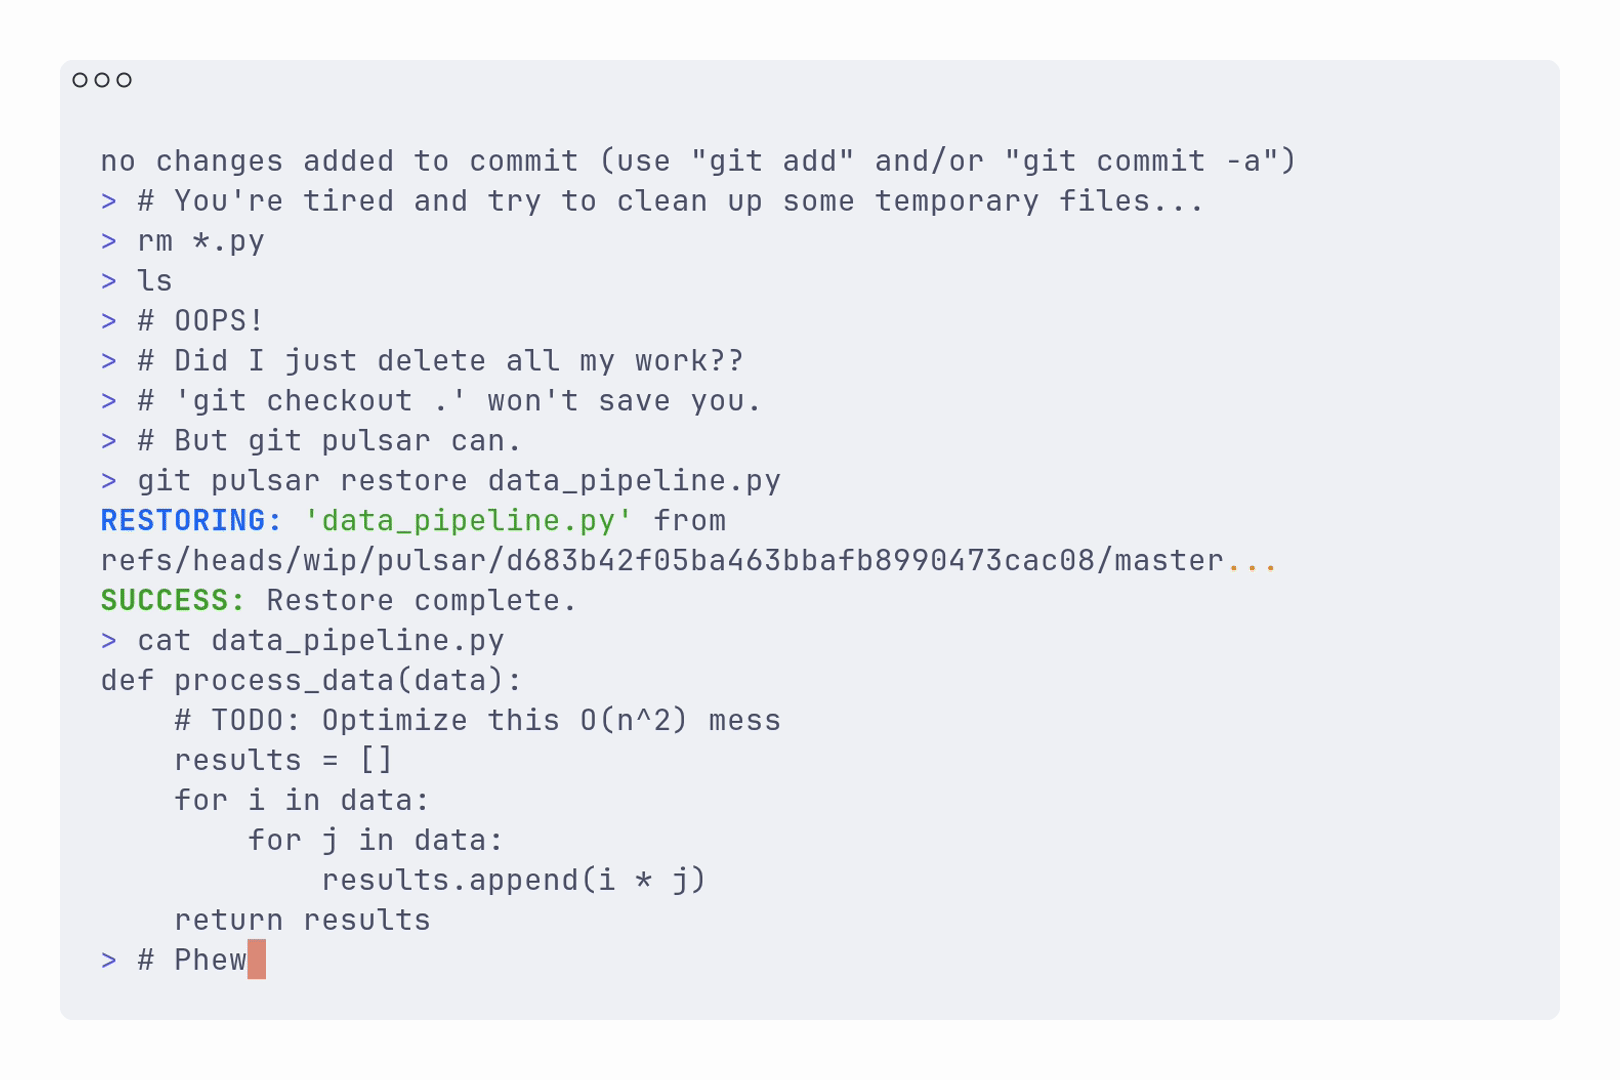
Git's normal commit workflow makes one history serve two different purposes: recovering unfinished work and publishing meaningful project history. Git Pulsar separates those concerns by maintaining an immutable, out-of-band graph of recoverable workspace states.
-
Recovery without staging interference: Constructs Git objects through a temporary index and
write-tree, leaving the user's active index and deliberate commit workflow untouched. -
Distributed reconciliation: State captured independently across multiple machines is reconciled through a "Zipper Graph" rather than allowing separate recovery histories to diverge into split-brain state.
Dependency-graph-aware storage analysis for Homebrew


Homebrew exposes package sizes and dependency metadata, but neither alone answers what an explicitly installed package actually costs once shared infrastructure is accounted for. Dark Matter reconstructs the dependency DAG and attributes transitive storage costs across the packages that share them.
-
Graph-aware attribution: Computes both direct package size and weighted recursive size, fractionally allocating shared dependencies rather than charging their full footprint to every parent. The resulting Bloat Ratio distinguishes self-contained tools from small packages that pull in disproportionately large dependency trees.
-
Measurement semantics: Separates physical analysis of installed Cellar contents from theoretical analysis of Homebrew's catalog. Theoretical modes use compressed bottle sizes, so absolute values are treated as estimates while relative ratios remain the useful comparison—an explicit limitation rather than hidden measurement error.
-
Targeted and ecosystem-scale analysis: Supports full-catalog leaderboards alongside
inspect,compare, andexplainpaths for individual packages, plus CSV/JSON export for downstream analysis.

Fast, curated codebase context for LLM-assisted development


A small CLI for turning repositories, diffs, CI failures, notebooks, PDFs, and web documentation into focused context that can be pasted directly into an LLM conversation.
-
Architecture follows workload: A lightweight Bash dispatcher sends common operations directly through compiled UNIX tools such as
rg,fd, andfzf; Python is reserved for structured work such as Git topology, APIs, notebooks, PDFs, and DOM processing. -
Context rather than autonomy: Filters generated/binary noise, enforces context-size bounds, supports local and cached remote repositories, and formats Git/GitHub state for clipboard-first use without attempting to become an autonomous coding agent.
A collection of computational pipelines bridging theoretical astrophysics, atmospheric science, and statistical inference.


Applied statistical methods to extract physical measurements from noisy astronomical and experimental data.
-
Galaxy Cluster Mass Estimation (ACO 2670): Used velocity measurements of galaxies in a cluster to estimate total mass through the virial theorem, finding a mass-to-light ratio of 291 ± 60 (solar units)—evidence that most of the cluster's mass is dark matter rather than visible stars.
-
Exoplanet Atmosphere Modeling: Solved equations for atmospheric pressure and temperature profiles to model the atmospheres of high-gravity exoplanets.
-
Monte Carlo Particle Simulation: Validated theoretical attenuation equations by simulating individual particle interactions and confirming expected statistical behavior.
| Domain | Technologies |
|---|---|
| Systems & CLI | Python 3.10–3.14, Bash, Git internals, Click, Rich, Questionary, UNIX tooling (rg, fd, fzf) |
| Infrastructure & Release | GitHub Actions, reusable workflows, uv, PyPI, Homebrew, Docker / GHCR |
| Parsing & Data Pipelines | tomlkit, pdfplumber, pyparsing, Pint, NumPy, SciPy, Pandas |
| Testing & Verification | pytest, Hypothesis, snapshot/regression testing, Bats, ShellCheck, mypy, Ruff |
| Hardware & Instrumentation | MicroPython, RP2040, ADC acquisition, analog signal conditioning, circuit fabrication |
| Analysis & Applications | Jupyter, Streamlit, Matplotlib, fpdf2 |
| Documentation | Zensical / MkDocs, Read the Docs, LaTeX, BibTeX |
When I'm not building deterministic toolchains, I'm usually deep in the Coast Mountains, either skiing or scrambling alpine ridges. I treat DJing and event logistics the same way I treat software: as complex systems that require careful routing, signal integrity, and risk management.

