

The fastest way to run GGUF models on Apple Silicon.
gmlx is a local inference platform. You can chat with an open model in the terminal or your browser, serve it over OpenAI and Anthropic compatible APIs, connect a coding agent to it, talk to it by voice, build a local RAG stack on it and fine-tune it with LoRA.
It runs the community's K-quant and IQ-quant GGUF builds exactly as published. Those formats are the most accurate open quants at a given file size, and the companion project mlx-kquant supplies the Metal kernels that run them natively on Apple's MLX framework.
On the same file gmlx benchmarks faster than llama.cpp, and the gap is widest at the long contexts that coding agents and long sessions use. A mixture-of-experts model bigger than RAM still runs, by streaming its experts from disk.
If you are coming from llama.cpp, Ollama or LM Studio, migrating.md says what carries over.

Higher is faster, and depth is the number of tokens already in the context. The per-model charts and the method behind them are in benchmarks.md.
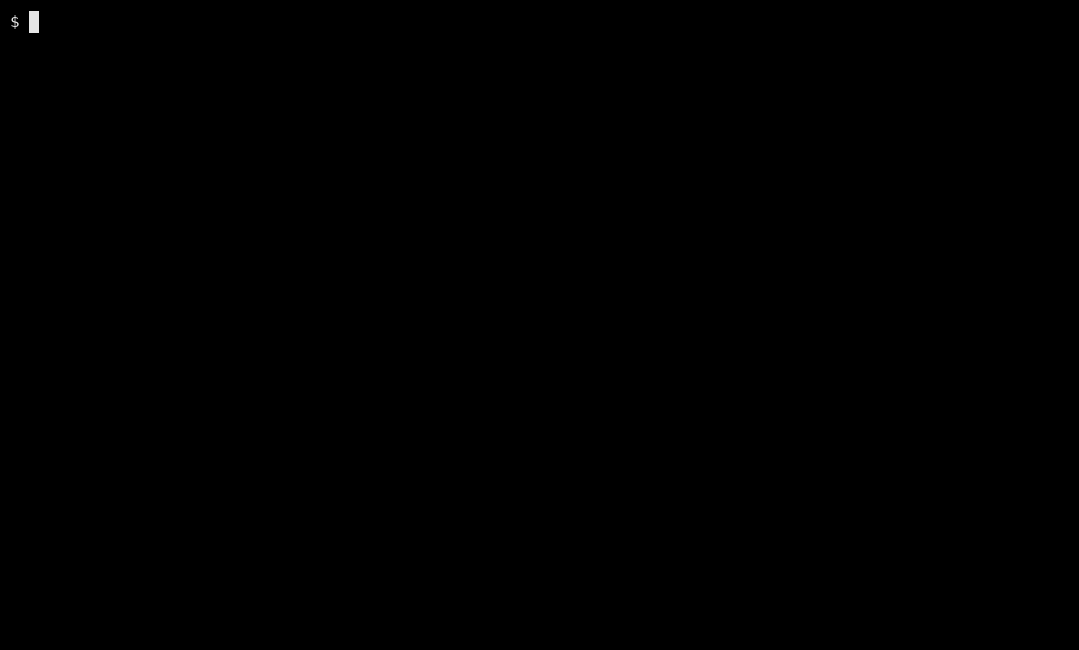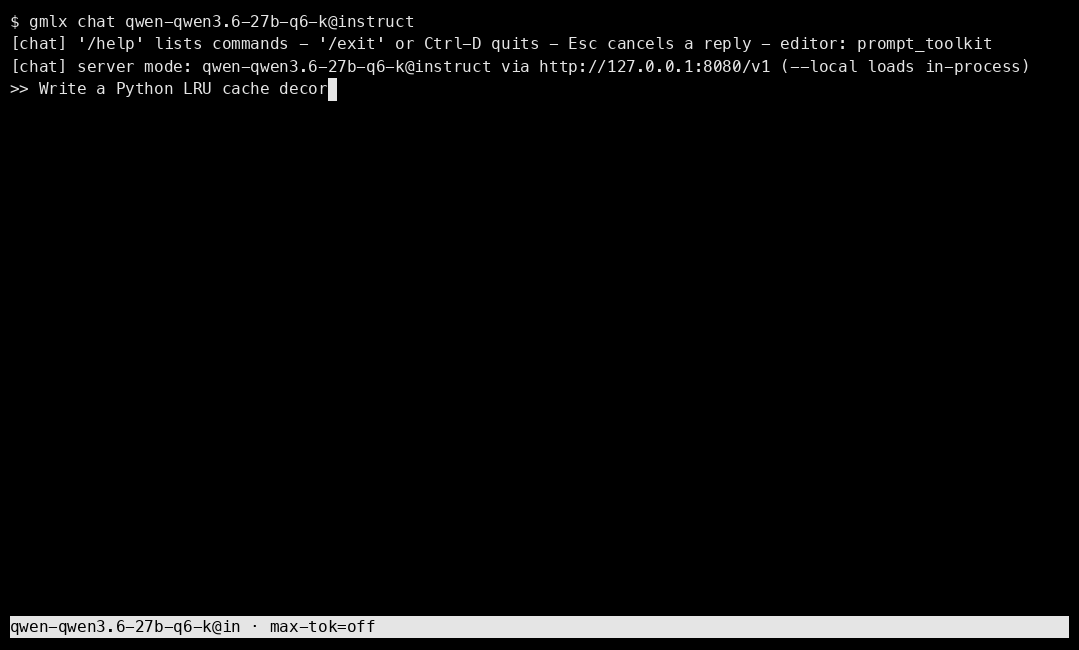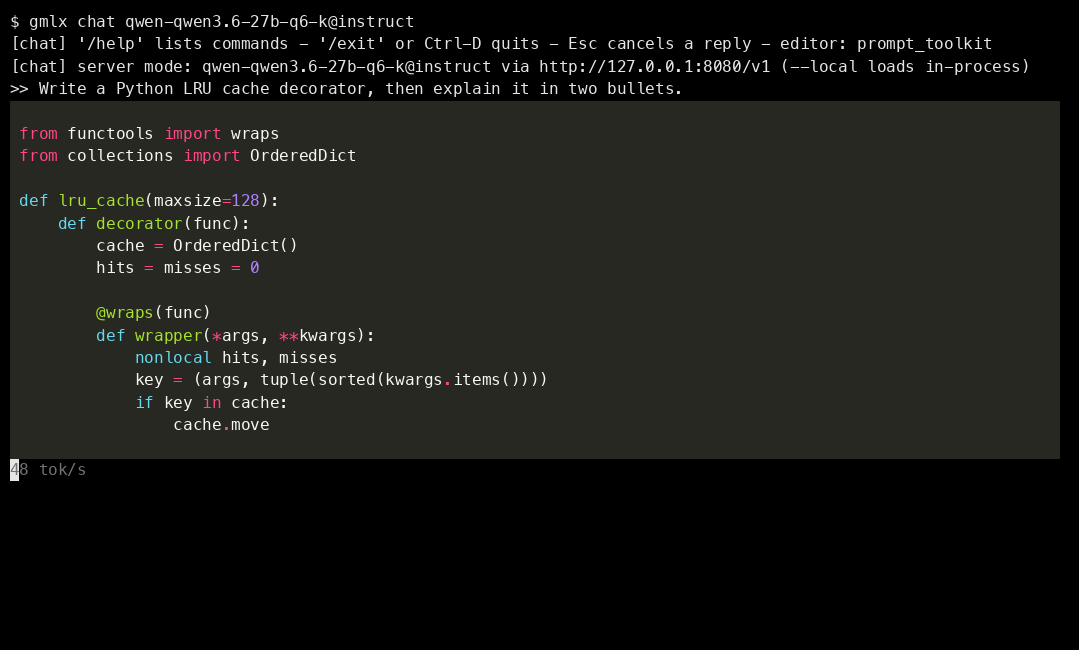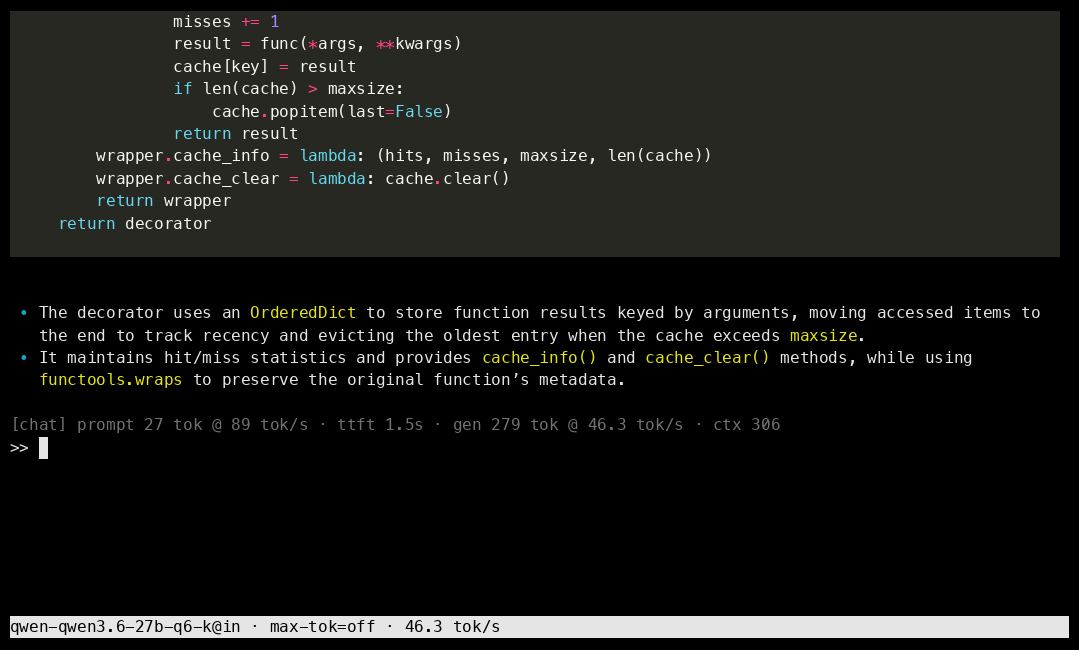
The recording runs at true speed, with a 27B model resident in a local server answering at 46 tokens per second.
gmlx needs an Apple Silicon Mac and Python 3.11 or newer. Intel Macs and Linux are not supported. On macOS 26.2 or newer the Metal kernels install as a prebuilt wheel, and getting-started.md covers older versions, which build them from source.
uv tool install "gmlx[all]"     # or: pip install "gmlx[all]" into a venv you manage
brew install ffmpeg             # voice and non-wav audio only

mkdir ~/gmlx && cd ~/gmlx
gmlx pull hf:unsloth/Qwen3-0.6B-GGUF/Qwen3-0.6B-Q4_K_M.gguf --to .
gmlx run  Qwen3-0.6B-Q4_K_M.gguf --prompt "Explain entropy in one paragraph."
gmlx chat Qwen3-0.6B-Q4_K_M.gguf
gmlx serve Qwen3-0.6B-Q4_K_M.gguf --port 8080

curl localhost:8080/v1/chat/completions -d \
  '{"model": "qwen3-0.6b", "messages": [{"role": "user", "content": "hi"}]}'
gmlx stop
Any local .gguf runs, chats or serves this way with no other setup. The
curl asks for qwen3-0.6b because a single served file takes its filename,
minus the quant tag, as its id. The other id rules are in
server-config.md.
gmlx[all] turns on every optional feature, and
getting-started.md
lists the extras. A model needs memory for roughly its file size plus the
conversation's KV cache, and the same guide
suggests models
for each machine size. Upgrade with uv tool upgrade gmlx. To remove gmlx,
follow
troubleshooting.md.
gmlx init finds your GGUF files, names them and writes the config that the
other commands read to ~/.config/gmlx/gmlx.yaml. Run with no arguments it
opens a wizard that walks through the model folders, the ids, the default
model and the optional services.
gmlx init                 # the wizard
gmlx serve                # finds the config, detaches, returns
gmlx list                 # the model ids it defines
gmlx launch pi            # connect a coding agent to the server
After that, every command takes a model id in place of a path, and pull
registers each download in the config. The wizard, its flags and what
follows are in the
getting-started guide.
run generates, benchmarks or prints the load plan of one file. chat is a
multi-turn terminal client with markdown rendering, sessions, live sampling
changes and image input. Both start from each model family's
recommended sampling,
and every flag is listed under its verb in
cli.md.
validate reads only a remote file's header to tell you whether it will load
and fit, and it can list the quants in a repo so you can pick one before
downloading anything. pull then fetches sharded files, resumes an
interrupted download and registers the result in your config.
One port serves OpenAI Chat Completions, OpenAI Responses and Anthropic Messages, all streaming, with tool calling, structured output, logprobs and vision messages. Concurrent requests decode together, a new prompt's prefill is paced so that live replies keep streaming, and a prompt cache skips repeated prefixes. The server binds loopback by default, requires a static key for anything wider and never contacts Hugging Face to satisfy a request. api.md documents the endpoints and server-config.md the YAML that configures them.
gmlx launch pi --model qwen3.6-27b@coding writes the tool's native config
without touching your dotfiles, starting the server first if it is not
running. It works for the common coding agents, two terminal chat clients
and Open WebUI, each listed with its quirks in
launch.md. A menu
bar app shows what is resident, and gmlx service install keeps the server
running from login.
With gmlx talk a wake phrase opens the mic, Whisper transcribes, and the
reply is spoken as it streams
(talk.md). The
built-in assistant
adds MCP tools and long-term memory to a voice session, to
chat --assistant, and to assistant ids that the server exposes as models.
The server also exposes /v1/embeddings, /v1/rerank,
/v1/audio/transcriptions and /v1/audio/speech, which together give a
client like Open WebUI a local RAG and voice stack. The services are
described in
services.md and
the RAG setup in rag.md.
train fine-tunes through the quantized matmul, so a model too large for
memory in fp16 still trains, and it writes the adapter as a GGUF that
llama.cpp reads too. --adapter applies it at run, chat or serve, and one
base can serve several adapters at once, which
lora.md walks through
end to end.
Because gmlx and llama.cpp run the same file, the comparison is direct. On an
M5 Max, gmlx prefills faster on every model in the fleet at every depth, and
with speculative decoding on both engines it decodes faster at every depth as
well. Absolute numbers scale with the machine's memory bandwidth, so measure
your own with gmlx run model.gguf --bench 128,512,2048.
performance.md
covers the performance features. Speculative decoding uses a model's own
draft head, or a companion drafter on models without one, and run and
chat turn it on by themselves. The prompt cache skips prefill for the
repeated prefixes of agent workloads, and KV-cache quantization shrinks long
contexts. Disk-streamed execution, described in
streaming.md,
runs MoE models larger than memory and makes a 200B-class model usable on a
64 GB machine.
The file you choose matters as well. A uniform K-quant decodes faster than a heavily mixed one at similar quality, and K-quants carry less error per byte than MLX's native quantization, as mlx-kquant explains.
A one-minute video shows the same server moving from one chat at full speculative speed to four concurrent streams and back, with no break in the live stream:
mtp-batching-qwen36-35b-demo.mp4
- Llama, Mistral, Phi-3, SmolLM3, Seed-OSS and ERNIE-4.5
- Qwen 2 through 3.8, dense and MoE, with the hybrid attention families
- Gemma 1 through 4, except the 3n variant, whose GGUFs are broken upstream
- DeepSeek V3, R1 and V4-Flash
- GLM 4 through 5.2, Kimi-K3, MiniMax M2 and M3, and gpt-oss
- Hunyuan, Hy3, HY4 and Muse Glimmer
- Granite, Nemotron-H and Falcon-H1
A family appears in the generated coverage table only after token-parity certification against llama.cpp at 16k context, and the table names the caveats where an architecture has any. All 19 K-quant, legacy and IQ codecs load, plus the MXFP4 and NVFP4 pair. Vision models load as a GGUF paired with its projector, as vlm.md describes, and adding-architectures.md explains what adding a family involves.
from gmlx import load_model, generate

model, config, tokenizer = load_model("model.gguf")
print(generate(model, tokenizer, "Explain entropy.", max_tokens=128))
load_model returns a ready-to-run mlx-lm model, the synthesized config and
the tokenizer. The full API, including preflight and the mlx-lm server bridge,
is in python.md.
- getting-started.md: install to a served model with a connected client.
- cli.md: every verb and flag.
- server-config.md: every key of the YAML config.
- api.md: the endpoints and request features.
- troubleshooting.md:
gmlx doctorfirst, then the common failures, where files are on disk and how to remove gmlx. - migrating.md: what transfers from llama.cpp, Ollama and LM Studio.
- glossary.md: the terms these docs use, from GGUF and quant to arena and governor.
- docs/README.md: the full index, grouped by what you want to do.
Pull requests are welcome. Dev setup and the rules are in CONTRIBUTING.md, the test tiers in testing.md, and the runtime's design in docs/internals.
gmlx builds on llama.cpp and ggml for the GGUF format and the K-quant reference implementations, MLX and mlx-lm for the runtime and model implementations, mlx-vlm for the server app, generation step loop and vision towers, mlx-whisper for speech-to-text, and mlx-audio for text-to-speech.
gmlx is released under the Business Source License 1.1, which is source-available but not open source. You may use, modify and run gmlx for your own purposes, including commercial work. You may not redistribute or sublicense it, incorporate it into another product, or offer it as a hosted service. Each released version converts to the Apache License 2.0 four years after its release, and downloaded model weights have their own licenses.
The files listed in LICENSE-MIT are MIT licensed and have an SPDX header saying so. Vendored third-party code is documented in THIRD_PARTY_NOTICES.md.